-
-
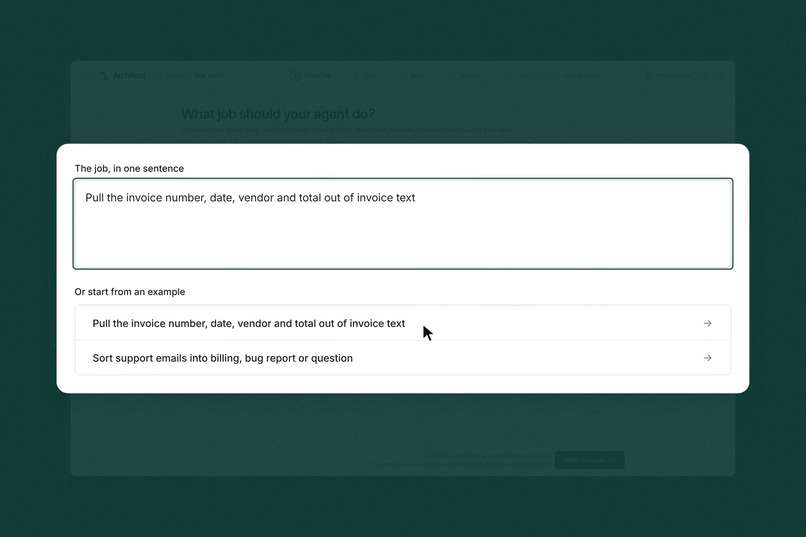
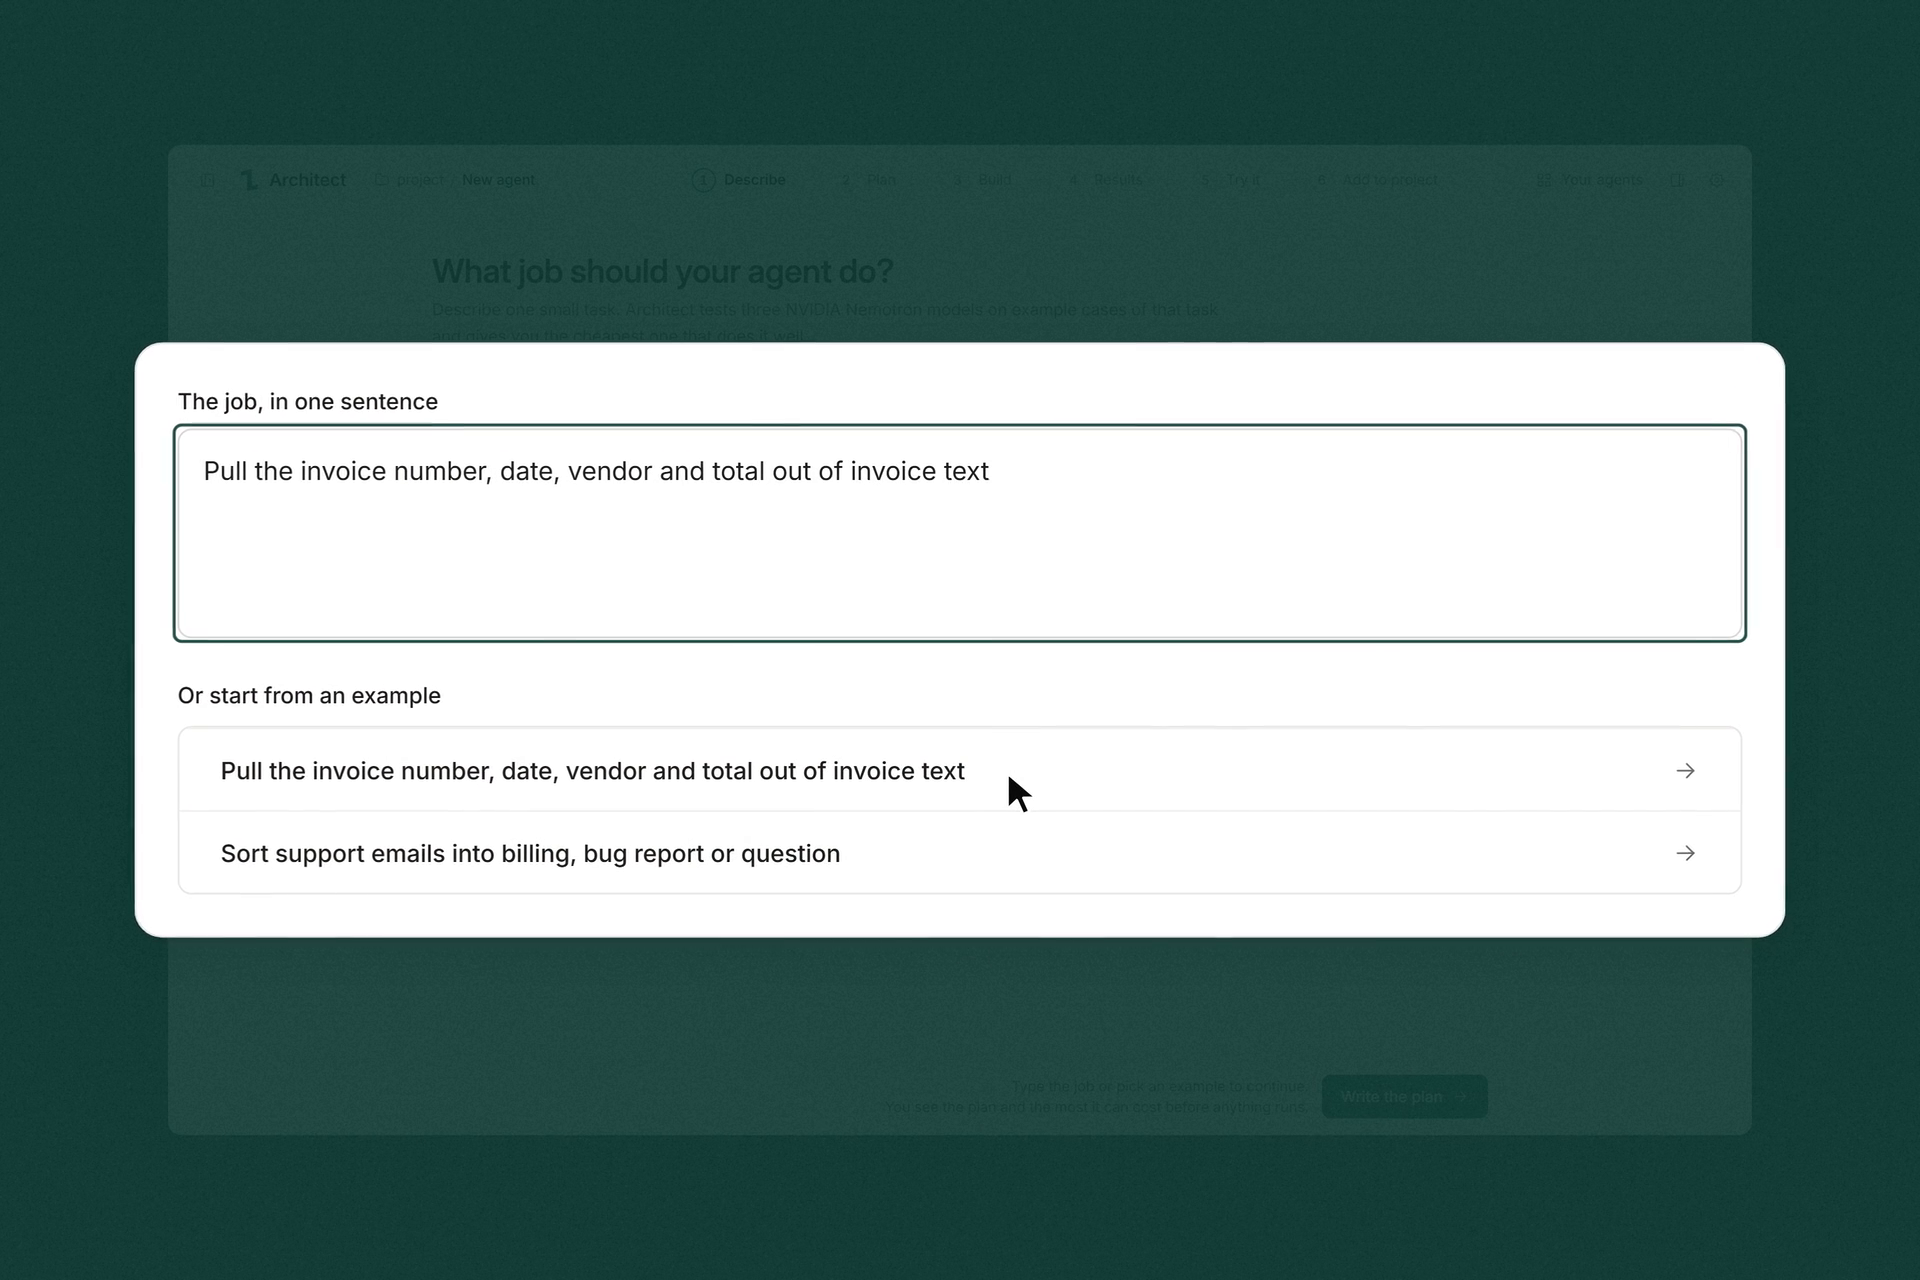
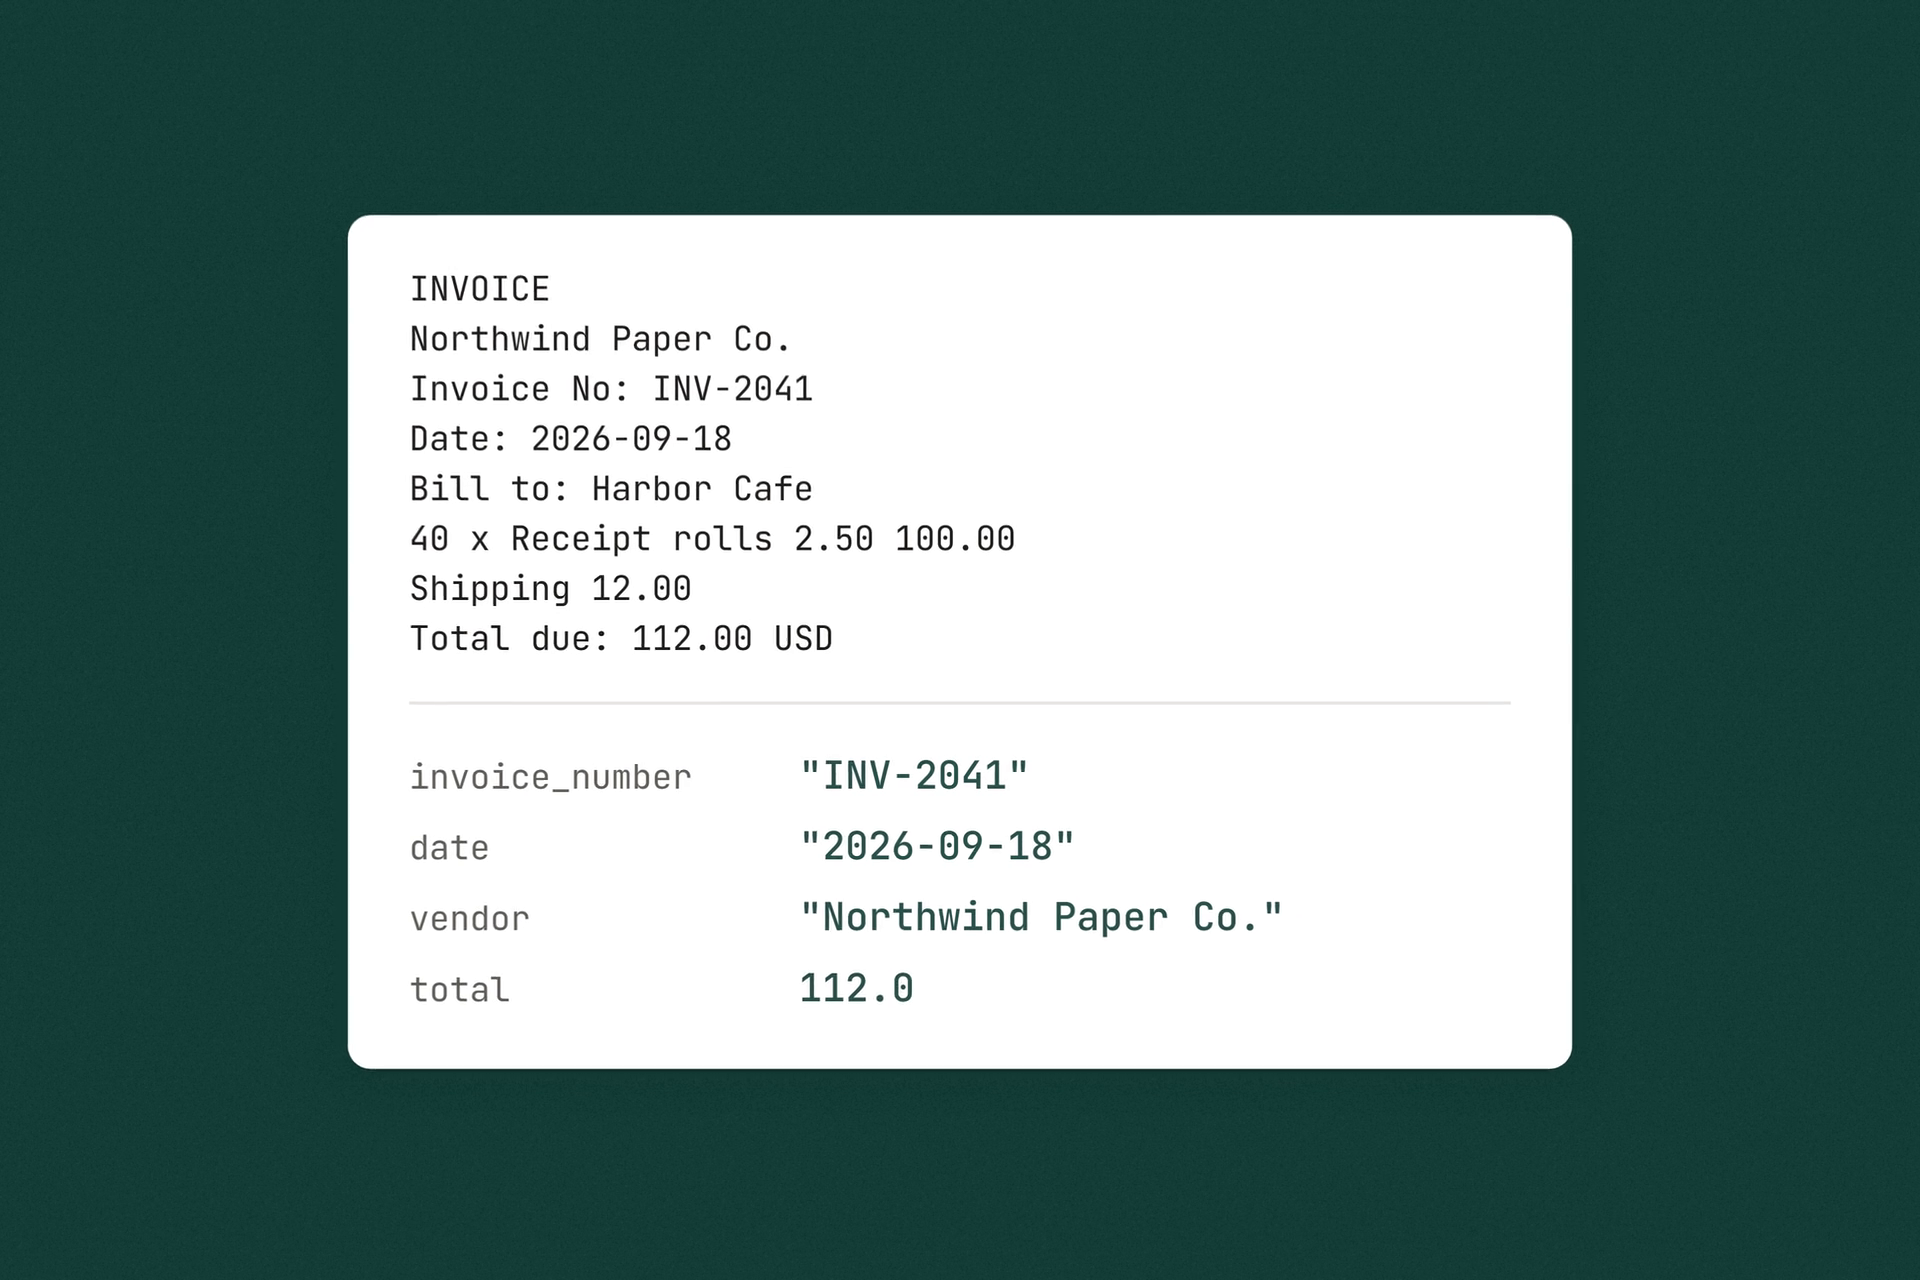
I type the job in one sentence, or pick an example. Here it's pulling the number, date, vendor and total out of an invoice.
-
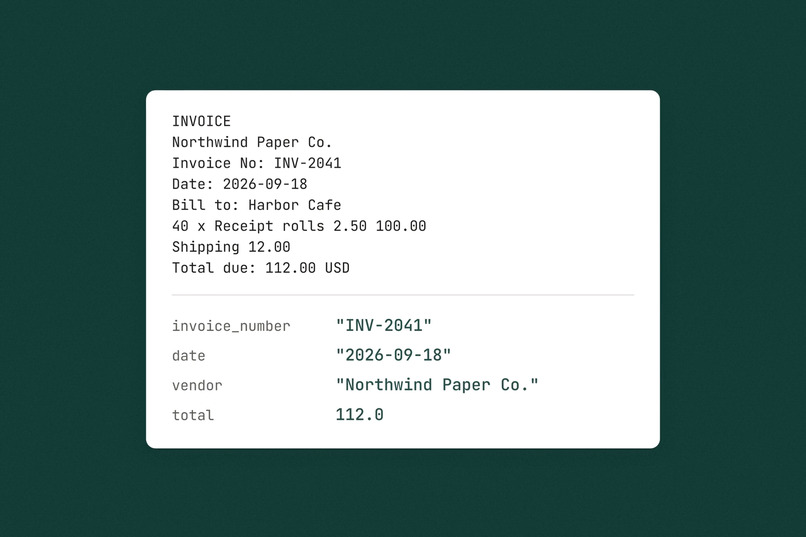
The invoice agent, built from the sentence in the first picture: a made-up invoice goes in and its four fields come out.
-
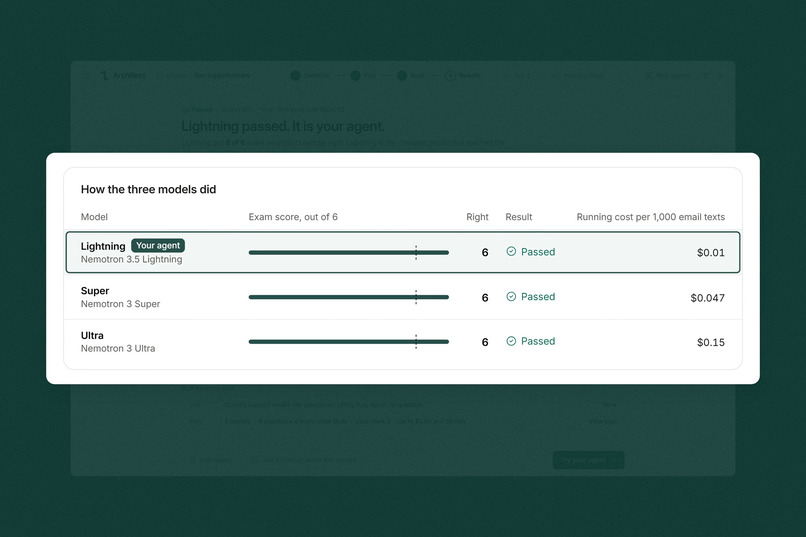
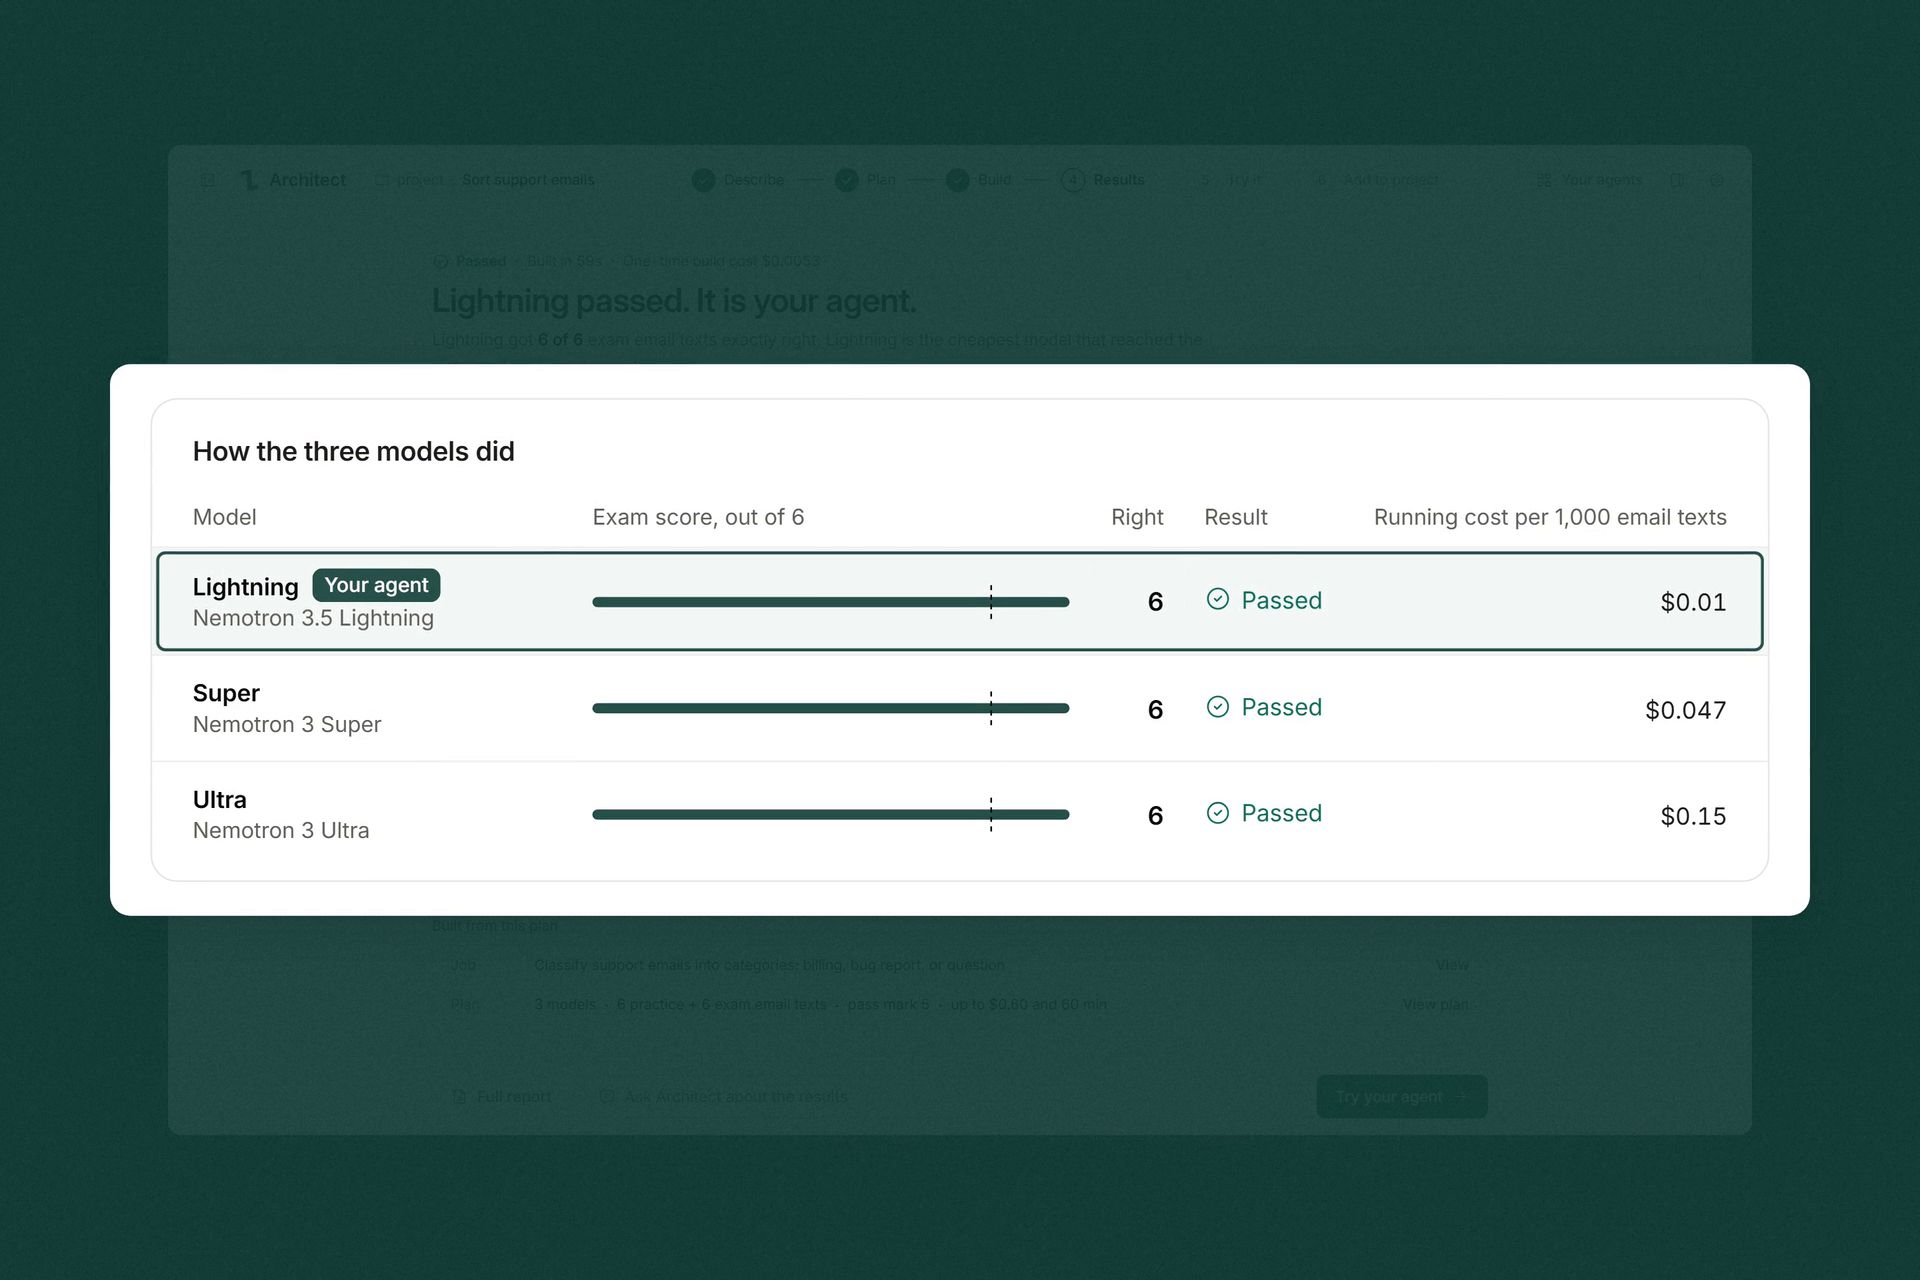
Three Nemotron models sat the email job's exam of 6 made-up cases and all got 6. Lightning is the cheapest to run, so it became the agent.
-
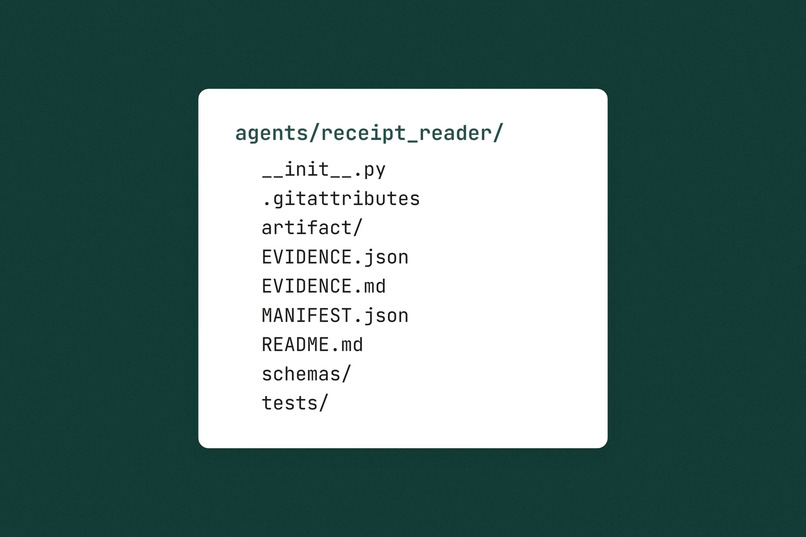
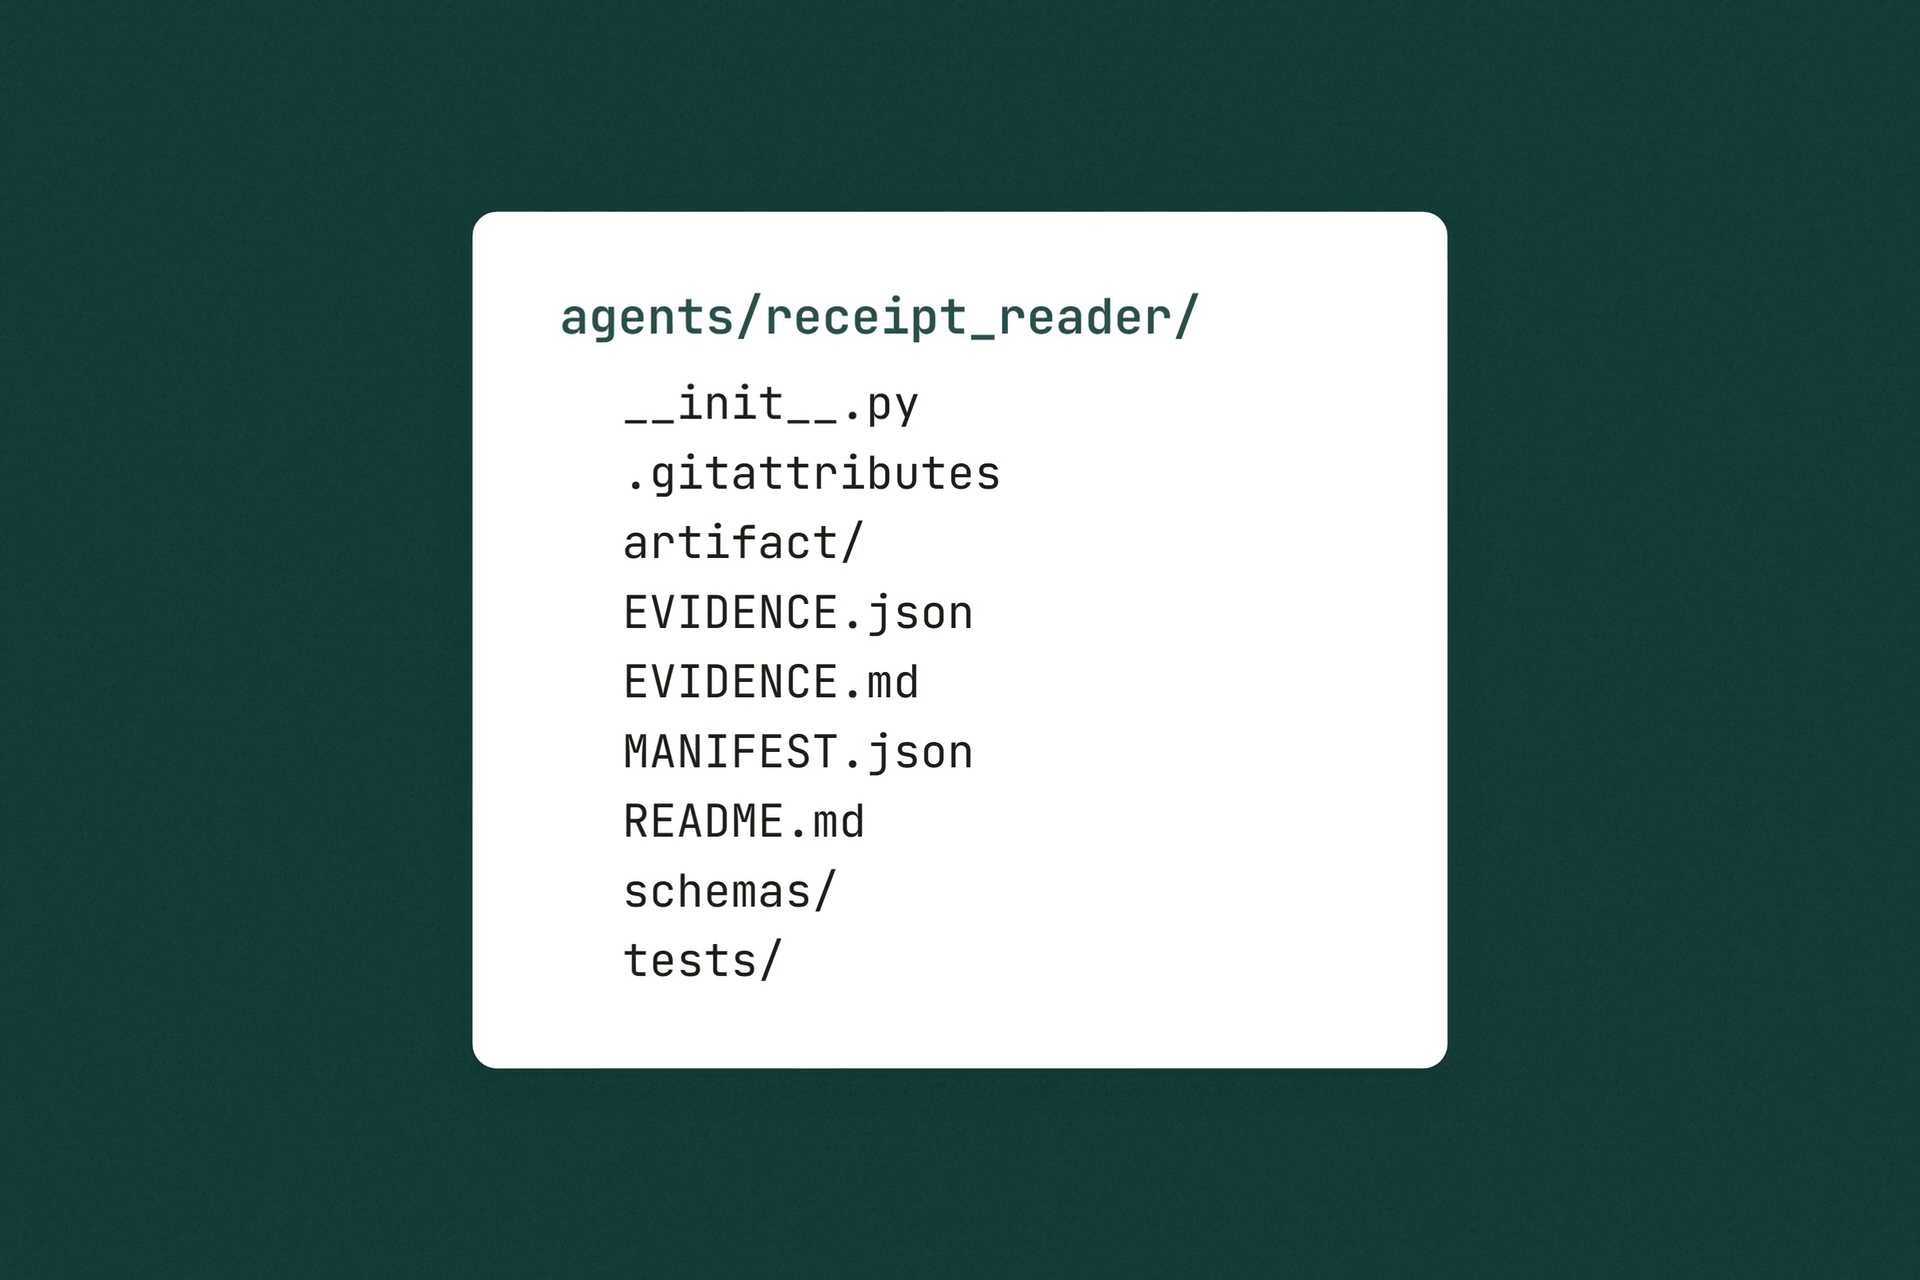
Add to project puts the agent in my code as a folder of files. This one is the receipt reader I built earlier.
-
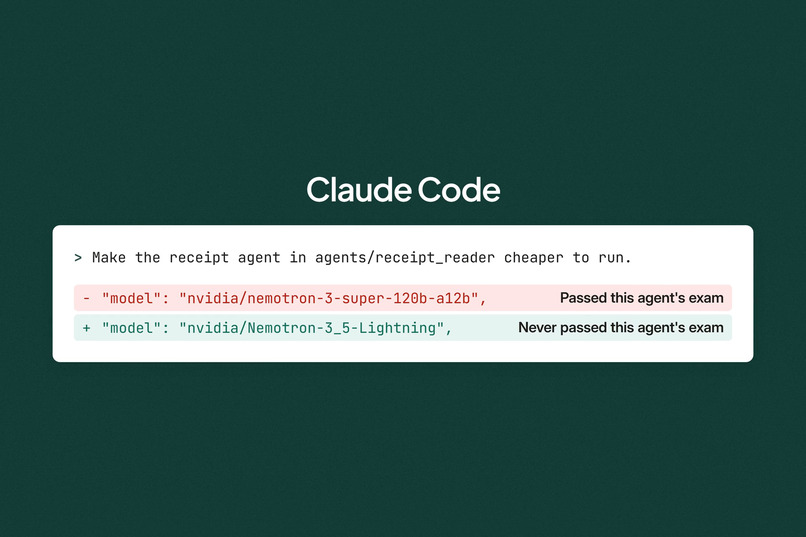
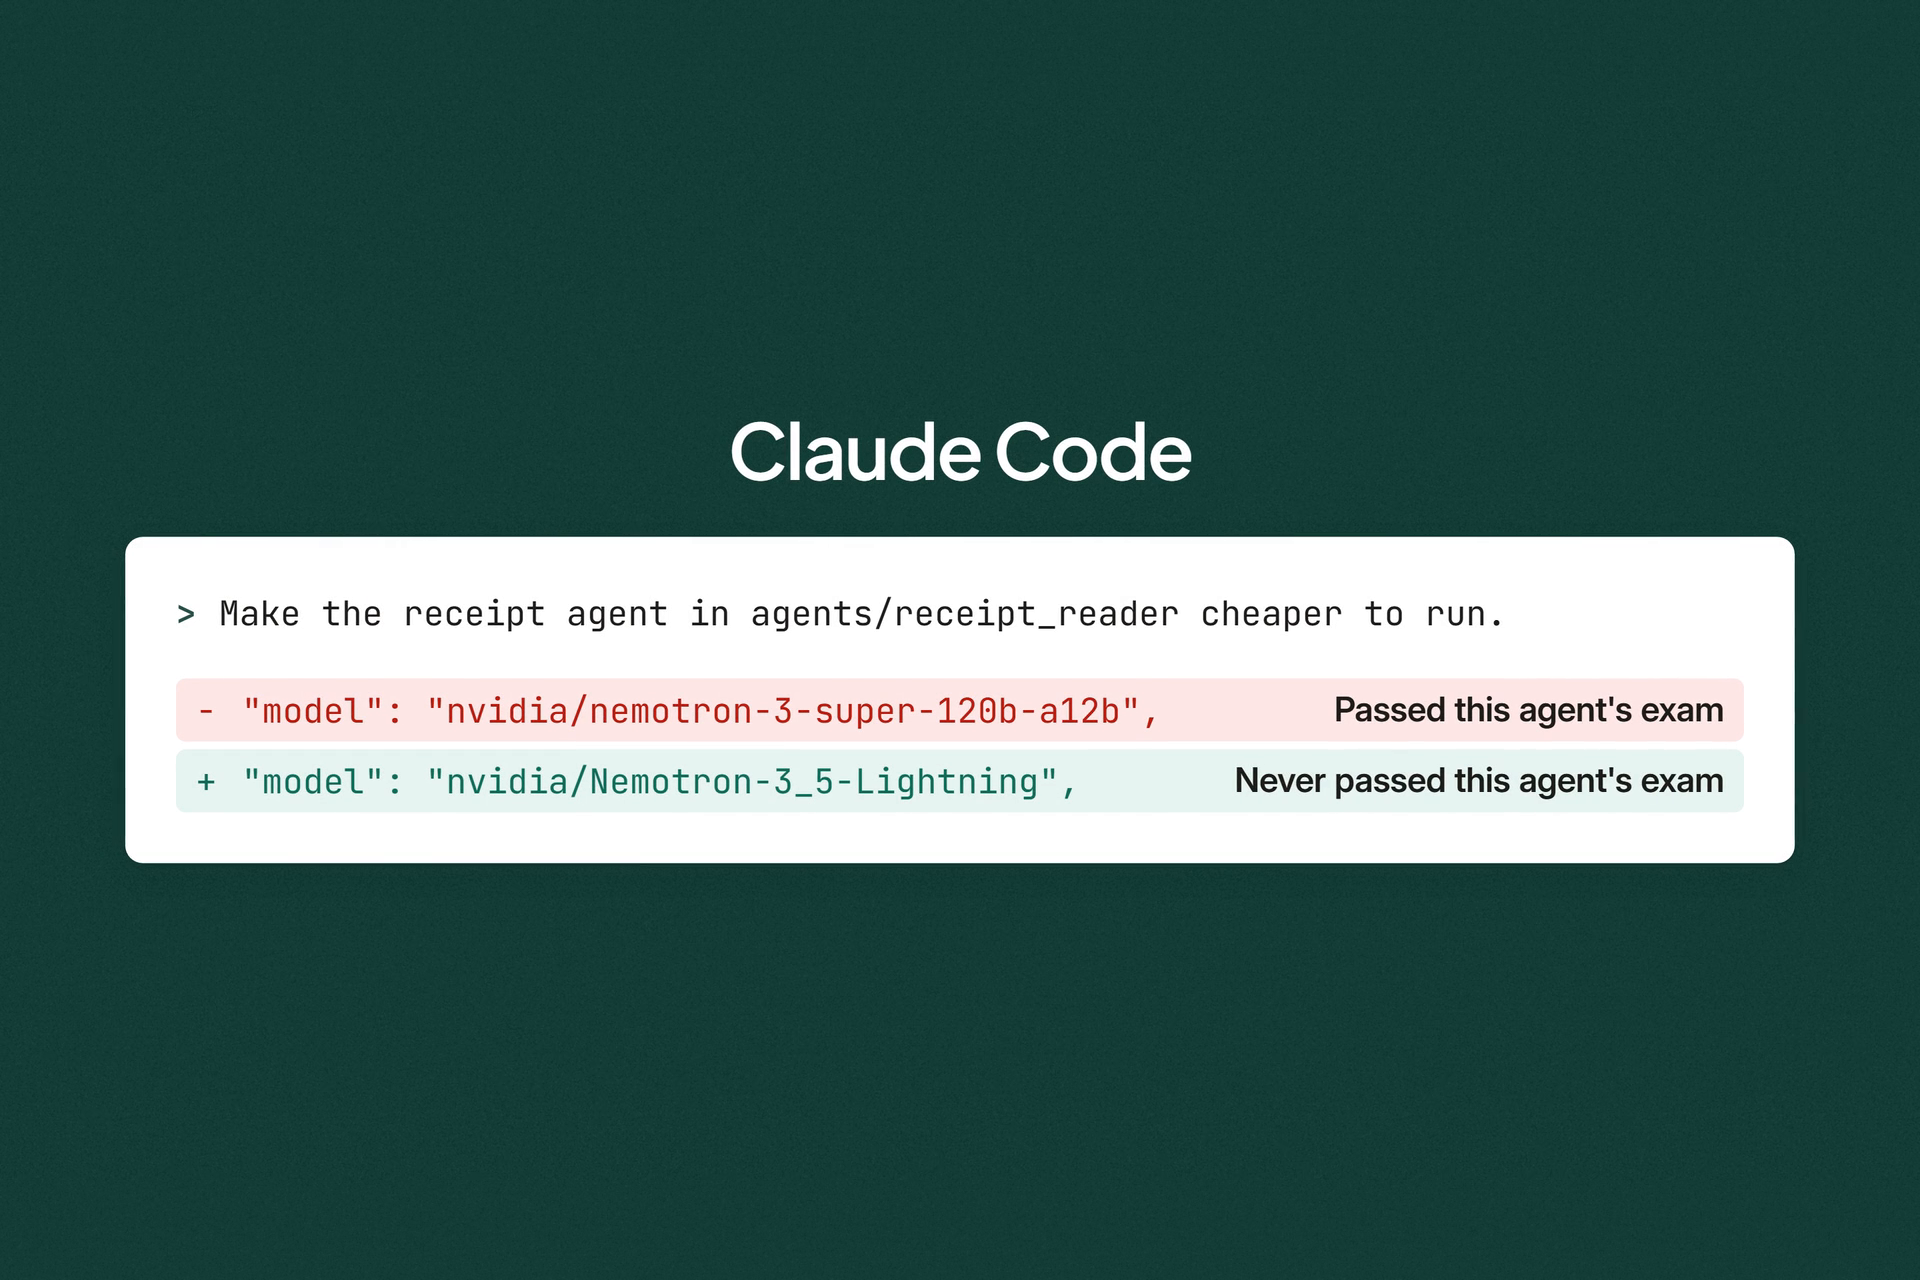
I asked Claude Code to make the receipt agent cheaper to run. It swapped in a model the agent never passed its exam with.
-
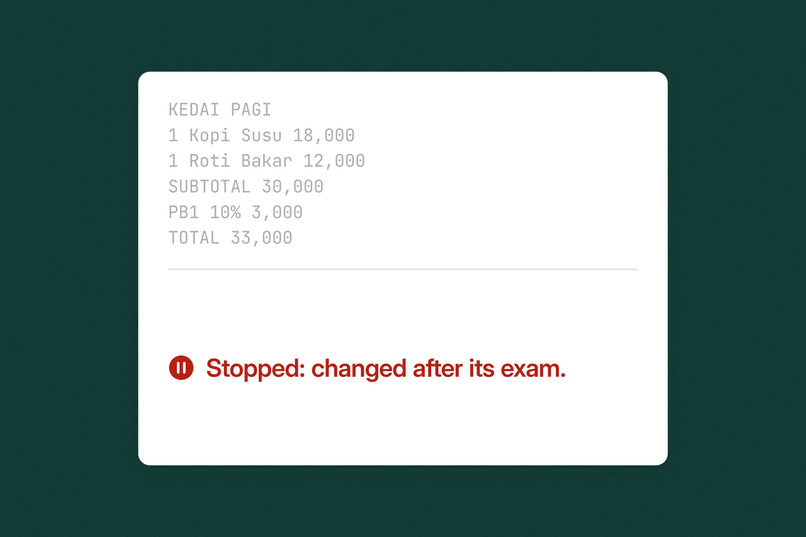
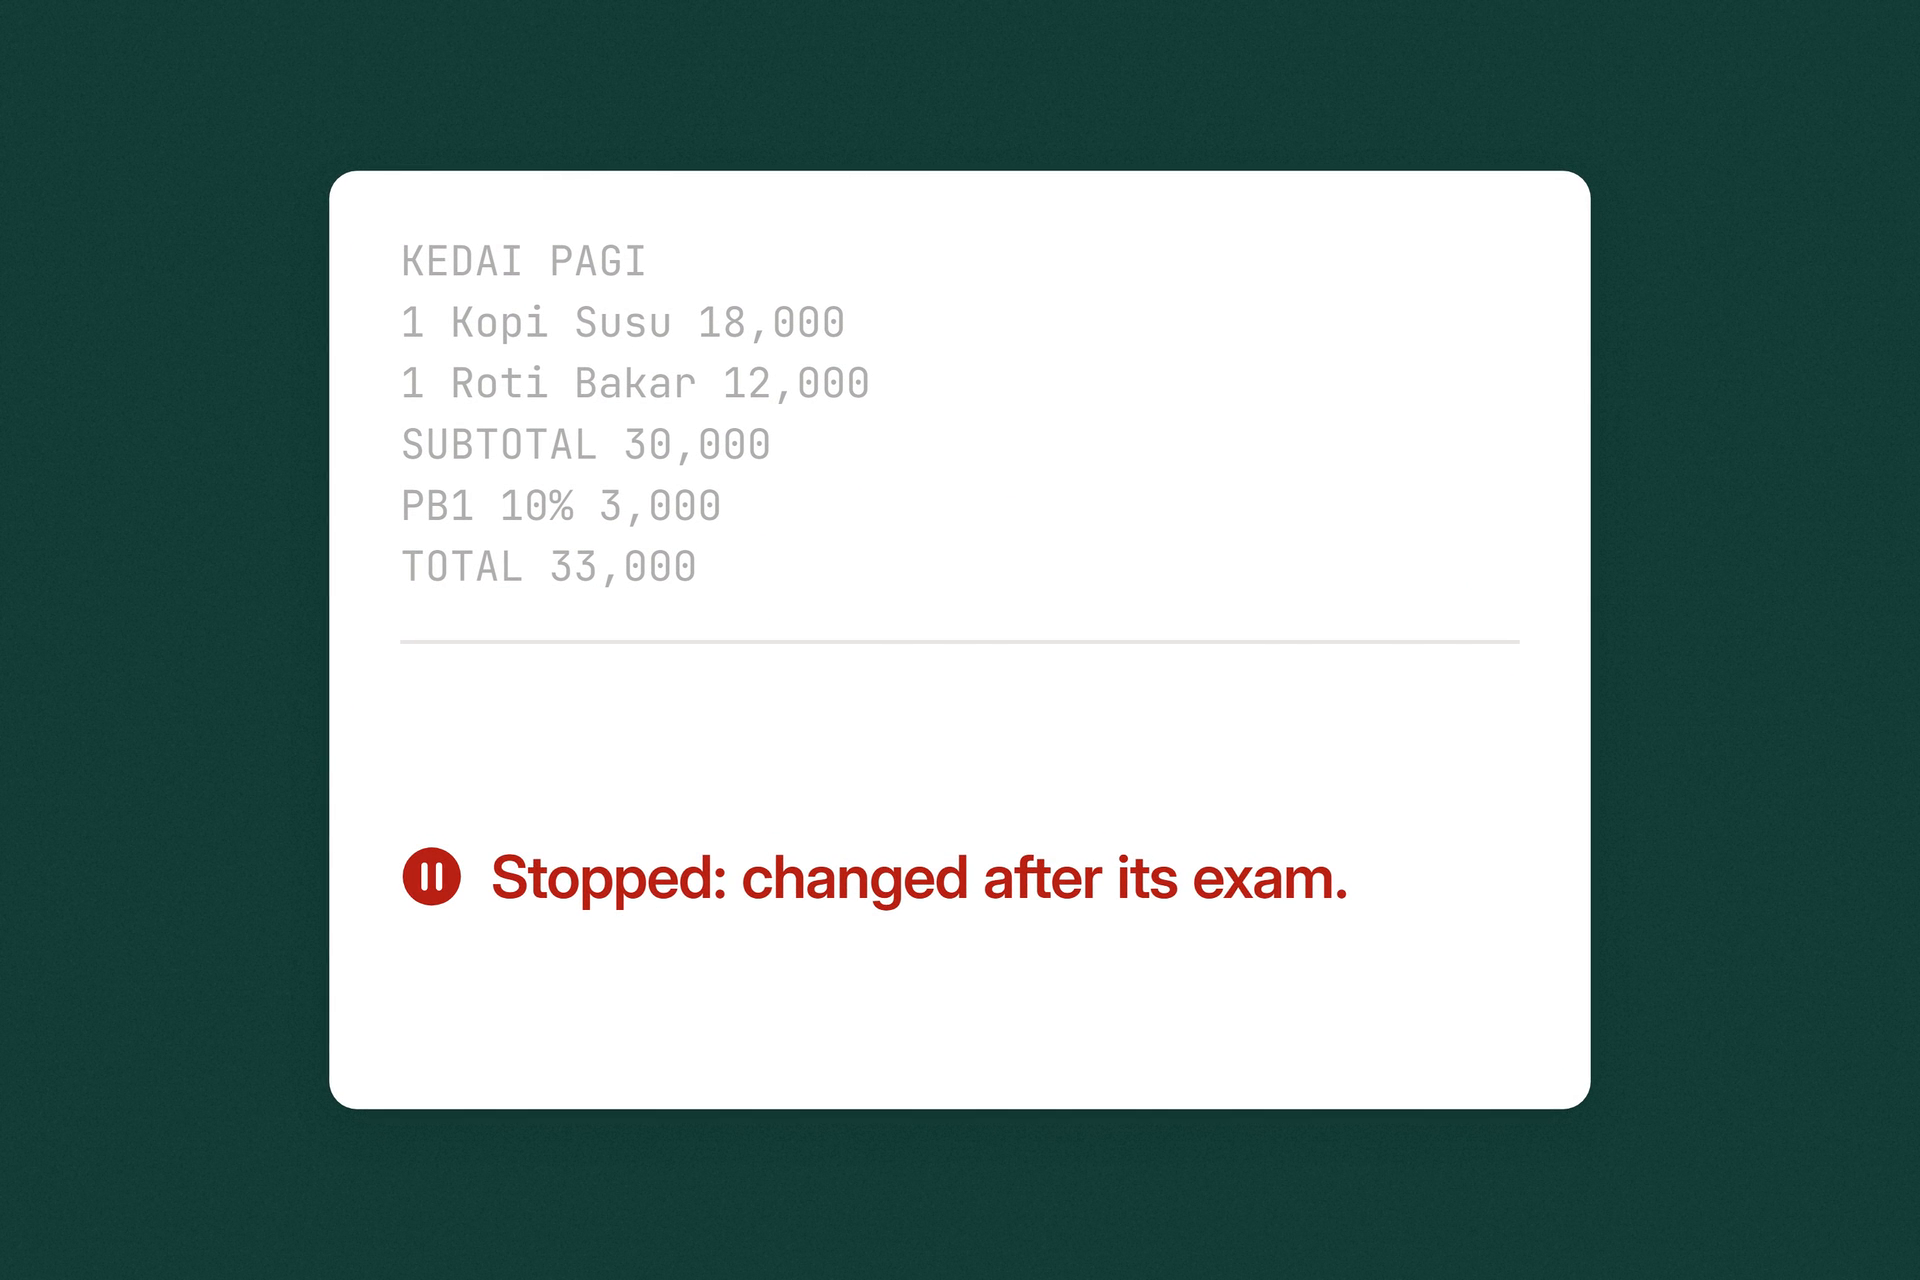
The app sent the next receipt and got this back. The agent stays stopped until it passes its exam again or I undo the change.
-
Architect: one sentence in, an agent out, and it only runs if it passed its exam. The code is at github.com/echoo19/architect-nemotron.
Architect is an agent factory. You type a job in one sentence and it builds a small AI agent for your app. The agent only runs if it passed its exam.
What it does
- Describe: type the job in one sentence.
- Exam: Architect tries models on practice cases (yours, or ones a model drafts), then checks them on separate exam cases. The cheapest one that passes becomes your agent.
- Add to project: the agent goes into your code as a folder of files.
- Stop: every call through that folder checks its files against the ones that passed. If one changed, the call is refused with 0 model calls until the agent passes again or you undo.
Other models, other editors
It isn't tied to Nemotron. Architect can also build with a Claude or ChatGPT subscription you already have, through the signed-in claude or codex command-line tool (none of my numbers used them).
The stop doesn't care who made the edit either. It checks the agent's files on every call, so a change from Claude Code, Codex or you by hand gets the same stop. There's no plugin for either tool.
What I measured
- Demo receipt build, 100 development receipts (not my published results): Nemotron 3.5 Lightning got 36, Nemotron 3 Super 59 and Nemotron 3 Ultra 64, pass mark 40. Super became the agent, in about 20 minutes for $0.31.
- 10 change requests to Architect's own coder: 8 changed the agent's files, and every changed version was refused before any model call. 3 were retaken and passed, and 5 couldn't be examined and were undone, so this doesn't show the exam catching a worse change.
- Claude Code, one run: asked to make the agent cheaper, it changed the model. The next receipt was refused, and Undo put back the version that passed. An edit by hand stopped too.
- Published run, plain models on 348 unseen CORD v2 receipts: Ultra 184 right, Super 180, Lightning 94. Super costs about 30% of Ultra per receipt, and those two are too close to rank.
- Invoices and support emails, one sentence each: built in 63 and 75 seconds for 1 cent or less each, after I fixed two bugs the first tries hit. Each exam was 6 cases a Nemotron model made up, which says nothing about real data.
The trial row by row: https://github.com/echoo19/architect-nemotron/blob/main/docs/bench/retake-trial.md Published results: https://github.com/echoo19/architect-nemotron/blob/main/docs/bench/results-receipts.md Evaluation plan, published before the run: https://gist.github.com/echoo19/217554e19b2d06d9c583f96732469dd6
How I built it
Every model call Architect made for these numbers went to NVIDIA Nemotron on Nebius Token Factory. Nemotron 3 Super runs the conversation and the coder, and a new agent tries Nemotron 3.5 Lightning first, then Super. The core is Python, and the desktop app is Electron, React and TypeScript.
What I'd do next
- Run a bigger trial, with Codex in it.
- Require a margin above the pass mark, since a model 1 or 2 receipts from it can go either way.
Video and credits
The video is a reconstruction from recorded runs, not a screen recording: the app's own interface code is fed the numbers and lines those runs recorded, and the pointer presses are re-enacted. The film typesets a few cards itself (the terminal, the two job cards), and the Undo press stands for the undo command I ran. The narration is an AI voice (Bella, ElevenLabs), and the music is "Closer" by Andrew Ev, from Mixkit. Claude, ChatGPT, Codex, NVIDIA, Nemotron and Nebius are their owners' names, and I'm not affiliated with them. Receipts come from CORD v2 by NAVER Clova (https://huggingface.co/datasets/naver-clova-ix/cord-v2, CC BY 4.0).

Log in or sign up for Devpost to join the conversation.