Reality Checker
An autonomous, multi-agent AI research intelligence platform that argues against your hypothesis before it agrees with you
🧠 About the Project
💡 Inspiration
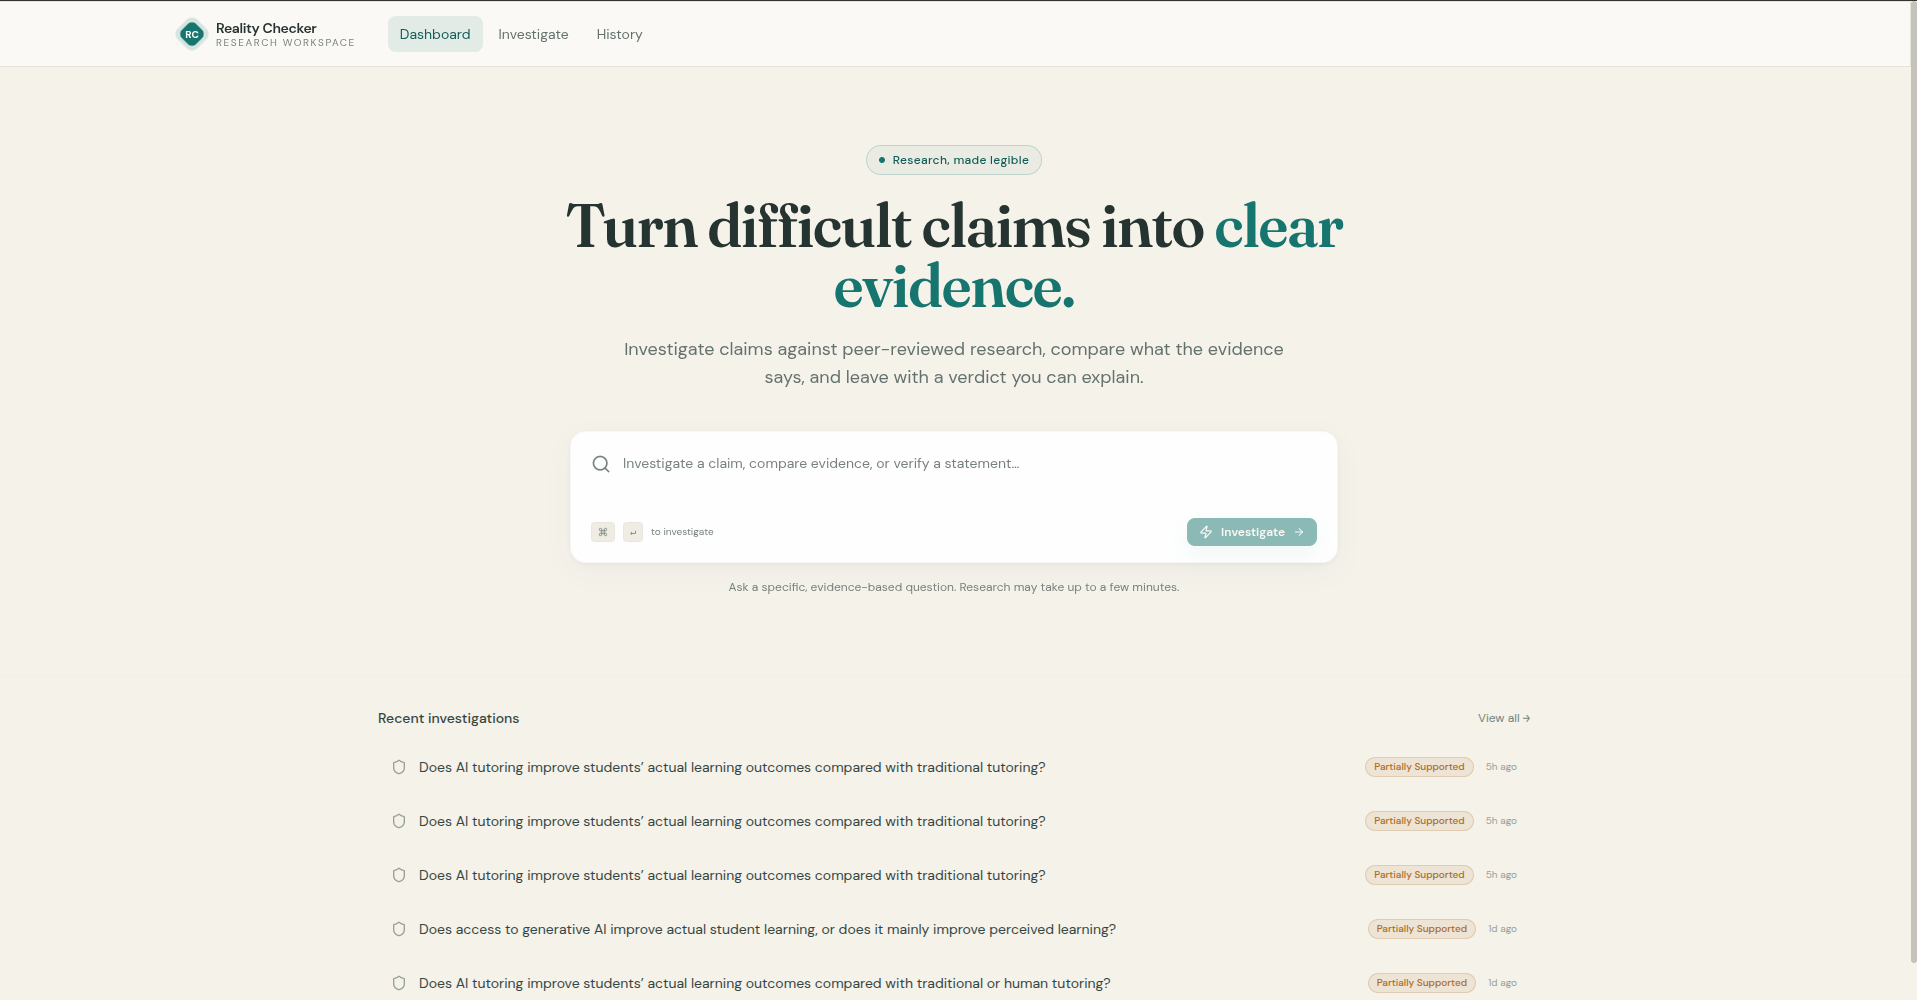
In an era dominated by generative AI, search engines and LLMs suffer from a critical flaw: confirmation bias and hallucination. If a user asks, "Does AI-assisted learning improve student performance?", standard AI tools generate queries that search only for supportive evidence — then return an overly confident "Yes" backed by blog posts and unverified press releases.
We set out to build Reality Checker, an autonomous, multi-agent AI research intelligence platform that operates like a rigorous senior peer reviewer. Our goal was to create a system that:
- Actively seeks counter-evidence and null findings to prevent confirmation bias.
- Distinguishes genuine scientific contradiction from contextual variation (e.g. positive math gains in high schoolers vs. zero gains in vocational adults).
- Suppresses duplicate and syndicated content, ensuring 10 syndicated blogs cannot outweigh a single peer-reviewed Randomized Controlled Trial (RCT).
- Delivers calibrated, evidence-grounded verdicts —
PARTIALLY_SUPPORTED,SUPPORTED_WITH_LIMITATIONS,CONTRADICTED,INSUFFICIENT_EVIDENCE— rather than naive binary answers.
🏗️ How We Built It
Reality Checker is built on a 4-module multi-agent architecture (M1–M4) connected through a high-throughput, rate-limit-resistant pipeline.
                         USER / RESEARCHER
                                 │
                                 ▼
                     M4  Next.js 14 + Streamlit UI
                       (App Router · editorial dark-ink)
                                 │
                                 ▼
                      FastAPI REST Backend
                                 │
                                 ▼
                     M1  Research Orchestrator
           (Router → Balanced Planner → State Engine)
                                 │
                 ┌───────────────┴───────────────┐
                 ▼                               ▼
        M2  Retrieval Agent              M3  Verification Pipeline
          (Multi-Track Search)           (Dedup → Contradiction →
                                          Sufficiency → Judge →
                                          Calibration)
                 │                               │
                 └───────────────┬───────────────┘
                                 ▼
                     3-Tier Storage Engine
          (SQLite · ChromaDB Semantic Cache · ChromaDB Vector Index)
1. M1 — Research Investigation Orchestrator
| Component | Role |
|---|---|
| Intent & Complexity Router | Classifies queries (SIMPLE, MODERATE, COMPLEX, CONTROVERSIAL) and routes each to an appropriate depth regime. |
| Balanced Query Strategy | Generates multi-track search plans covering Supporting, Contradicting, Systematic Reviews, Contextual Moderators, and Recent Research. |
| Multi-Account LLM Gateway & Provider Chain | A 7-layer fallback chain: 4 × Groq API keys → Google Gemini (gemini-3.1-flash-lite) → OpenRouter (free tier) → HuggingFace (Qwen2.5-72B-Instruct). |
| Adaptive Research Loops | Reads the evidence gaps identified by M3 and dispatches targeted follow-up queries until sufficiency is reached or the budget is exhausted. |
2. M2 — Retrieval Agent
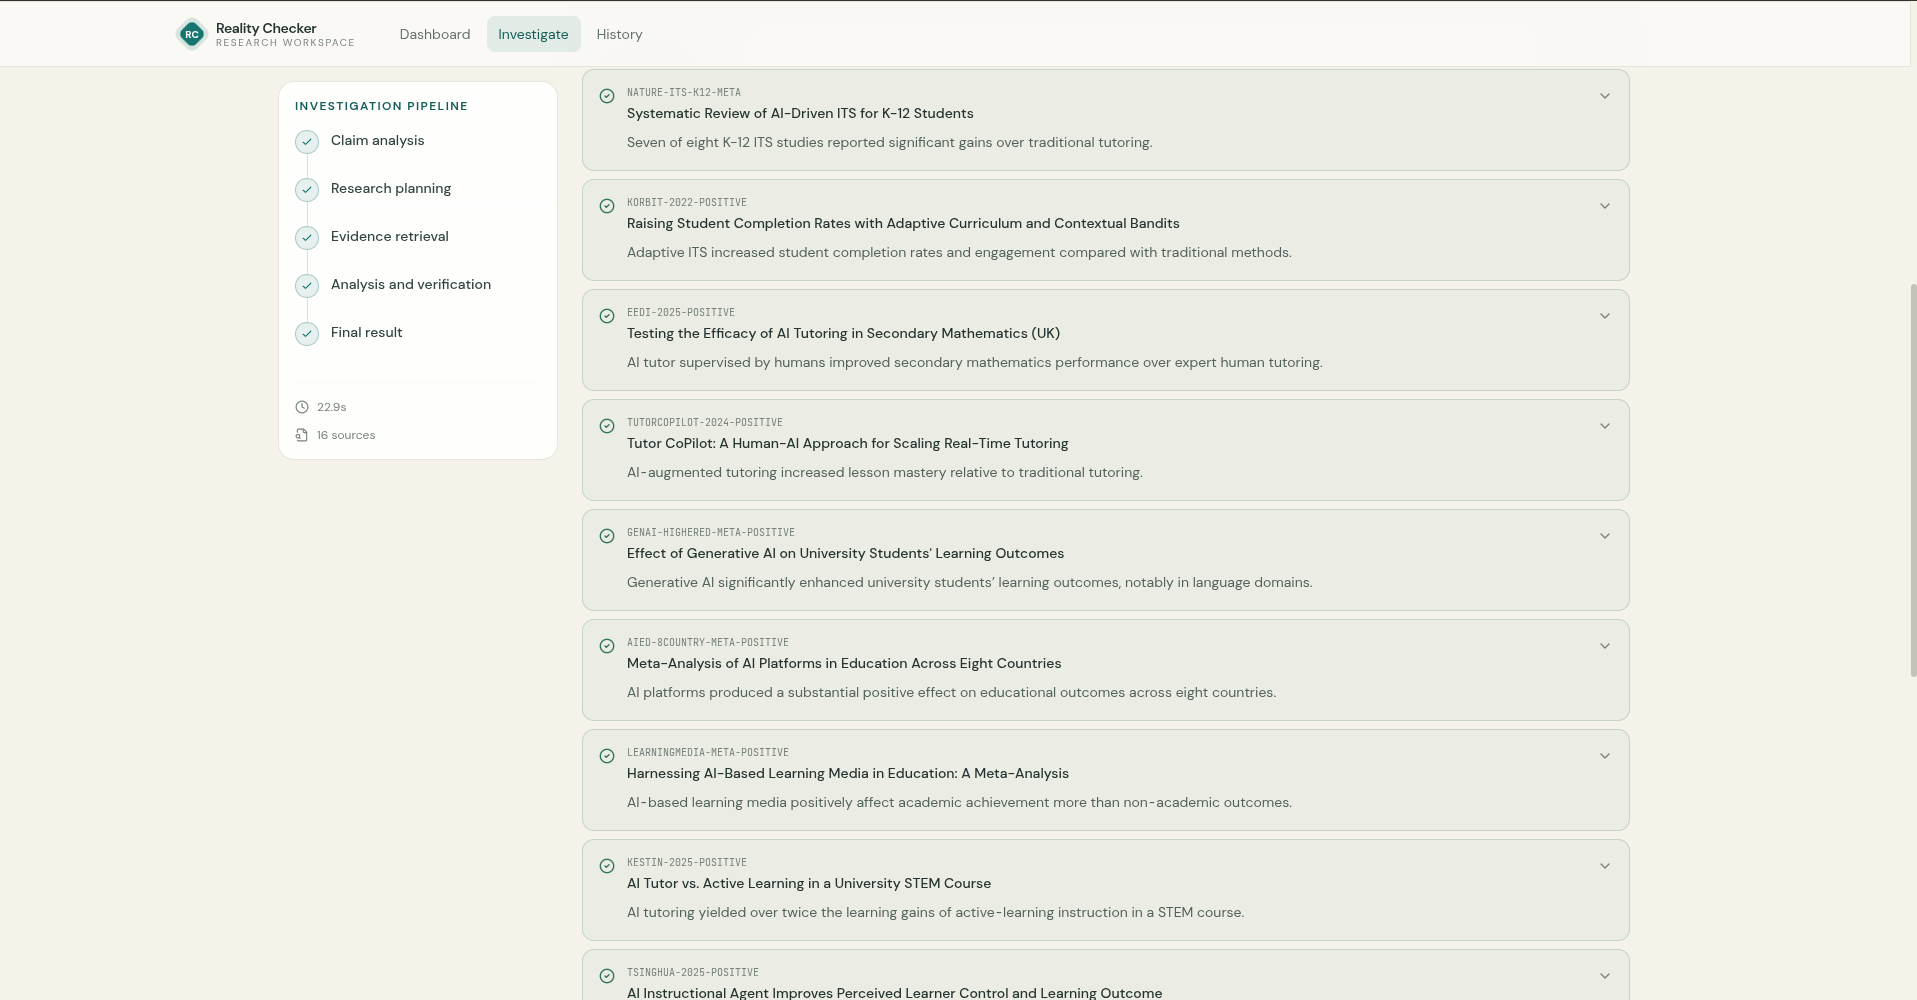
Executes the multi-track plan against heterogeneous sources (scholar indexes, preprint servers, government/NGO repositories, general web), normalises metadata, and feeds candidates into M3 without any filtering of dissenting sources. Every track's yield is tracked separately so the orchestrator can see which side of the argument is thin on evidence.
3. M3 — Evidence Verification Pipeline
| Stage | File | What it does |
|---|---|---|
| Batched Evidence Analysis | m3/analyzer |
Evaluates 20+ papers in a single structured LLM call, extracting key claims, methodology ratings, and support levels (SUPPORTS, CONTRADICTS, NEUTRAL). |
| Group-Aware Deduplication | m3/source_identity.py |
Uses domain normalisation, publisher keys, and title-token overlap to merge syndicated news and blog copies into single evidence families. |
| Multi-Stage Contradiction Classifier | m3/contradiction.py |
Compares representative sources across 4 comparability dimensions: Population, Intervention Type, Outcome Metric, Baseline/Comparator. |
| Sufficiency Engine | m3/verifier.py |
100% deterministic Python — evaluates evidence sufficiency with pure quality heuristics, eliminating unnecessary LLM calls. |
| Verdict Calibration Layer | m3/calibration.py |
Post-processes the raw verdict into a structured, 6-section, evidence-grounded report. |
4. M4 — Presentation, Persistence & Semantic Caching
- SQLite (source of truth): full investigation states, JSON verdict payloads, and execution traces.
- ChromaDB persistent semantic cache: caches complete investigations by cosine-distance threshold, with a 24-hour freshness TTL policy.
- ChromaDB evidence vector index: stores extracted evidence passages for real-time vector similarity search.
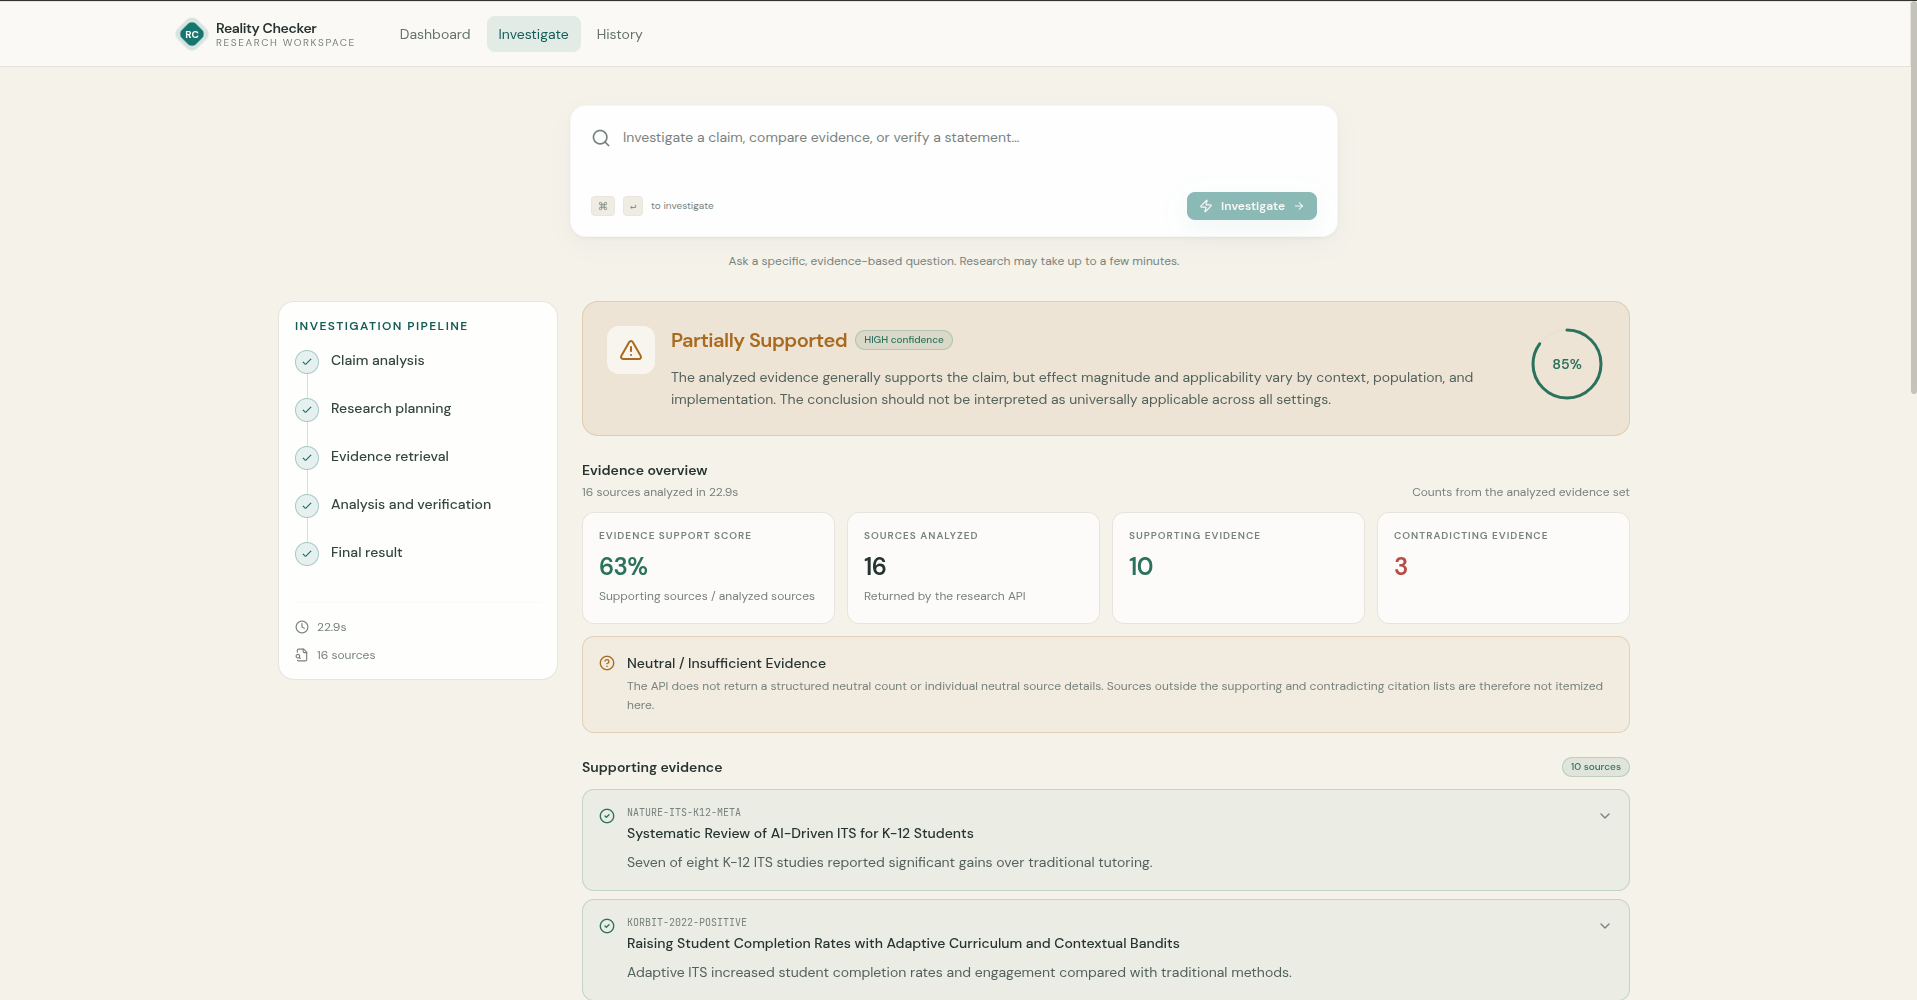
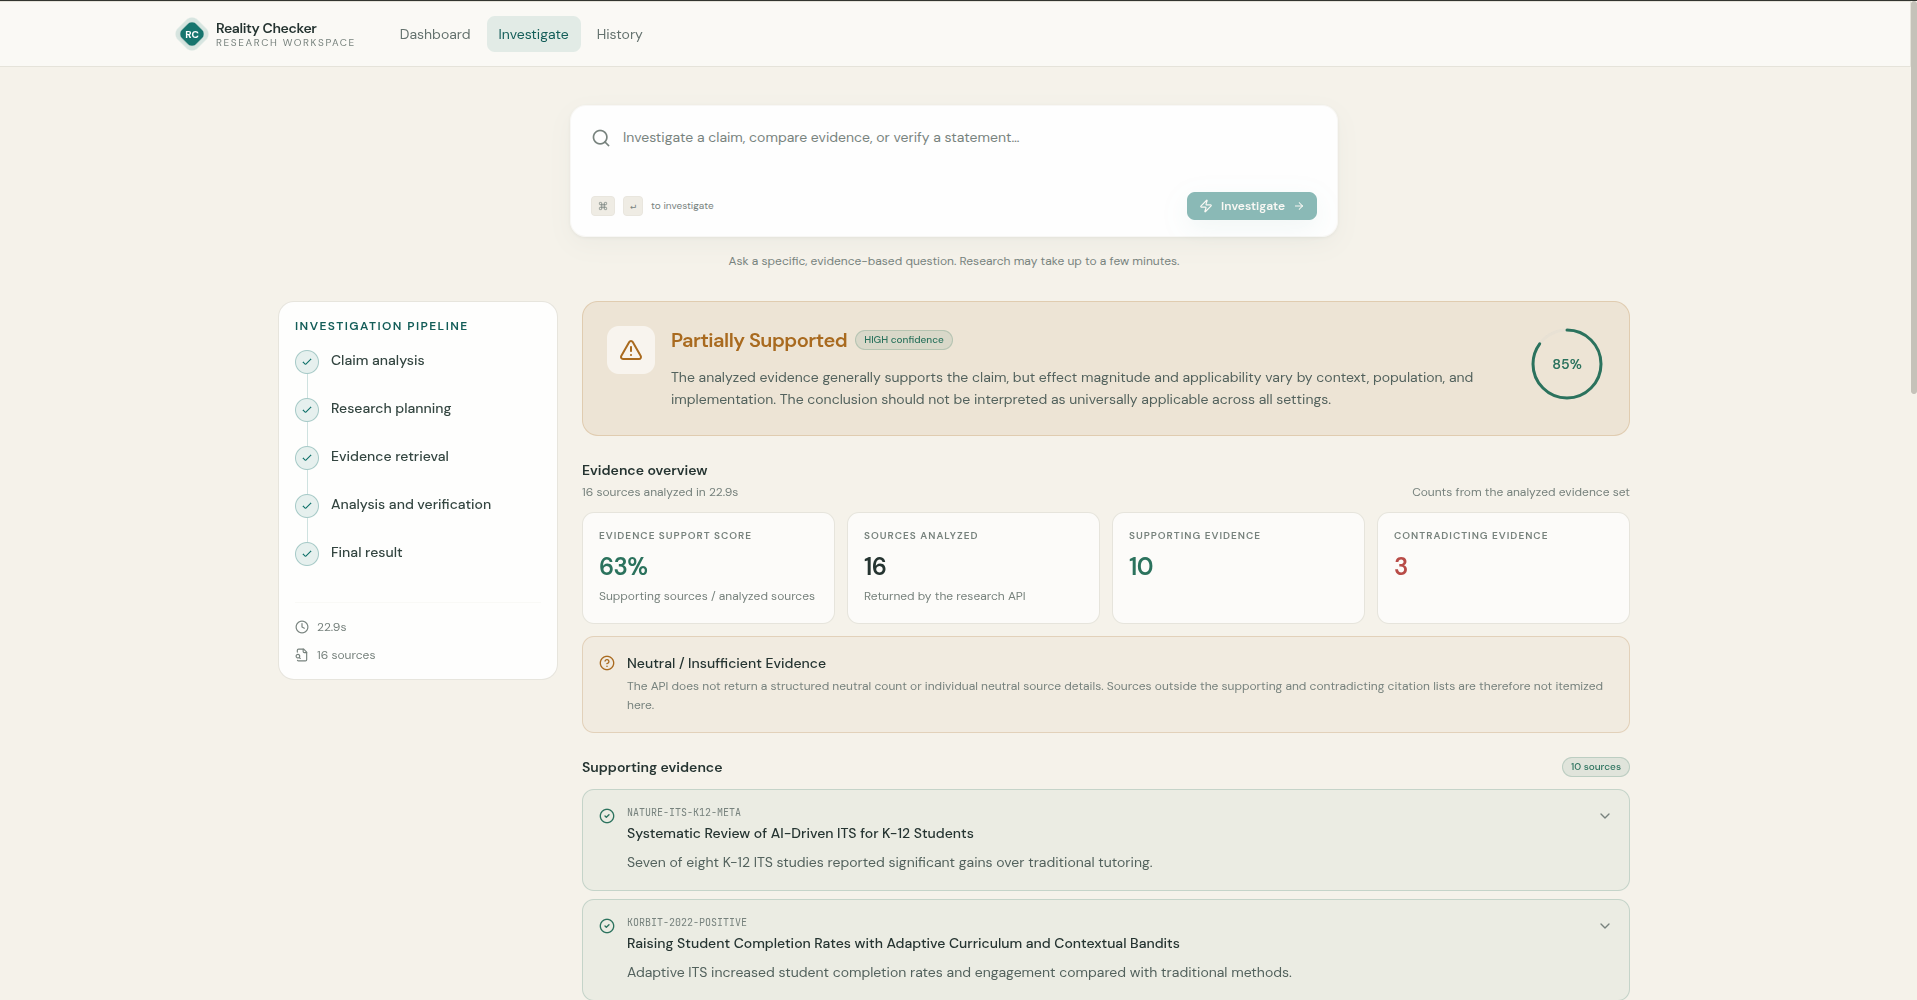
- Next.js 14 + Streamlit interfaces: editorial dark-ink design system, interactive confidence-ring meters, live-terminal trace logs, and pipeline progress visualisation.
🧮 Mathematical Formulations & Heuristics
To guarantee objectivity and prevent LLM hallucination, M3 uses deterministic mathematical heuristics for scoring, deduplication, and consensus. The LLM extracts; Python computes.
1. Evidence Weight Calculation
The weight $W_{ev}$ of any individual evidence item is the product of a base weight and five multipliers:
$$ W_{ev} \;=\; W_{base} \cdot W_{rel} \cdot M_{source} \cdot M_{method} \cdot M_{peer} \cdot M_{recency} \cdot M_{indep} $$
where the components are drawn from fixed ladders:
$$ W_{base} \in {\,3.0\ (\text{HIGH}),\; 2.0\ (\text{MEDIUM}),\; 1.0\ (\text{LOW})\,} $$
$$ W_{rel} \in {\,1.0\ (\text{HIGH}),\; 0.7\ (\text{MEDIUM}),\; 0.4\ (\text{LOW}),\; 0.0\ (\text{NONE})\,} $$
$$ M_{source} \in {\,1.25\ (\text{peer-reviewed}),\; 1.15\ (\text{government}),\; 0.60\ (\text{blog})\,} $$
$$ M_{method} \in {\,1.35\ (\text{meta-analysis}),\; 1.25\ (\text{RCT}),\; 0.85\ (\text{survey})\,} $$
$$ M_{peer} = \begin{cases} 1.20 & \text{if peer-reviewed}\[2pt] 0.95 & \text{otherwise} \end{cases} $$
$M_{recency}$ decays with publication age and $M_{indep}$ is the independence multiplier defined below. Note that $W_{rel} = 0.0$ makes weight multiplicative-zero: an irrelevant source is annihilated rather than merely discounted, so it can never be rescued by a high base weight.
2. Diminishing Returns for Duplicate Source Groups
To stop $N$ syndicated duplicates from inflating consensus, the independence multiplier $I_{factor}$ for a source group (evidence family) of size $N$ is bounded by:
$$ I_{factor}(N) \;=\; \frac{1}{N}\left(1 + \sum_{i=2}^{N} \frac{1}{i^{2}}\right) $$
so the total weight contributed by a family of $N$ near-identical items is
$$ W_{family}(N) \;=\; N \cdot W_{ev} \cdot I_{factor}(N) \;=\; W_{ev}\left(1 + \sum_{i=2}^{N}\frac{1}{i^{2}}\right) $$
Because the series $\sum_{i=1}^{\infty} i^{-2} = \pi^{2}/6$ converges, this gives an asymptotic hard ceiling:
$$ \lim_{N \to \infty} W_{family}(N) \;=\; \frac{\pi^{2}}{6}\, W_{ev} \;\approx\; 1.6449\, W_{ev} $$
In words: no evidence family — however many copies it contains — can ever be worth more than ≈ 1.645× a single independent item of the same quality. This is the property that makes the guarantee structural rather than tuned.
Worked example: 50 syndicated blogs vs. 1 peer-reviewed RCT
Using the ladder values above for a survey-method blog post supporting the claim and an RCT contradicting it:
$$ W_{blog} = 1.0 \times 1.0 \times 0.60 \times 0.85 \times 0.95 = 0.4845, \qquad W_{RCT} = 3.0 \times 1.0 \times 1.25 \times 1.25 \times 1.20 = 5.625 $$
| Weight of 50 copies | $S_{support}$ | |
|---|---|---|
| Naive (no dedup) | $50 \times 0.4845 = 24.23$ | 81.2% — blogs dominate |
| Group-aware dedup | $50 \times 0.4845 \times I_{factor}(50) = 0.787$ | 12.3% — RCT dominates |
with $I_{factor}(50) = 0.0325$. Without deduplication the blogs overtake a single RCT at just 12 copies ($12 \times 0.4845 = 5.81 > 5.63$); with it, they never catch up, since $0.797 < 5.625$ for every finite $N$.
3. Weighted Consensus Share
The overall directional consensus share $S_{support}$ is computed across $K$ independent source groups:
$$ S_{support} \;=\; \frac{\displaystyle\sum_{k=1}^{K} W_{supports,\,k}}{\displaystyle\sum_{k=1}^{K}\bigl(W_{supports,\,k} + W_{contradicts,\,k} + W_{neutral,\,k}\bigr)} \times 100\% $$
Neutral evidence is deliberately retained in the denominator: a field full of underpowered null results should suppress confidence even when nothing actively contradicts the claim. Where a directional-only reading is wanted, the same numerator over $W_{supports} + W_{contradicts}$ gives the two-sided share; both are surfaced in the verdict payload.
4. Verdict Mapping
The deterministic scores are mapped to a calibrated verdict label, with the confidence ring driven by evidence sufficiency and the spread between $S_{support}$ and $S_{contradict}$:
| Verdict | Typical condition |
|---|---|
SUPPORTED |
High $S_{support}$, sufficient evidence, no unresolved genuine contradictions |
SUPPORTED_WITH_LIMITATIONS |
High $S_{support}$, but CONTEXT_DIFFERENCE findings narrow the claim's scope |
PARTIALLY_SUPPORTED |
Mixed $S_{support}$ / $S_{contradict}$ across comparable populations |
CONTRADICTED |
High $S_{contradict}$ on comparable evidence |
INSUFFICIENT_EVIDENCE |
Sufficiency engine below threshold — the honest "we don't know yet" |
🚨 Challenges We Faced & How We Overcame Them
1. The Groq 8,000 TPM Limit & the "Billing URL 429" Bug
The challenge. Groq's free tier enforces a tokens-per-minute ceiling that is charged against the tokens you request, not the tokens you receive — a single 20-paper prompt with a generous max_tokens easily breaches it. Worse, Groq's HTTP 429 payload contains the string https://console.groq.com/settings/billing. Our error classifier matched the word billing and misclassified a transient 3-second rate limit as a permanent payment error, placing Groq keys on a 1-hour ban.
The solution. We overhauled verification/scheduler.py to prioritise HTTP status-code detection (429) over body-string matching, and implemented fail-fast, instant failover. When groq-1 hits a rate limit it enters a short soft cooldown (10 s) while the request instantly fails over to groq-2, groq-3, or groq-4 in < 0.01 s — zero thread freezing.
Rule we now follow: classify errors by status code first, and never let a substring of a help URL decide control flow.
2. Groq Strict JSON Schema Compliance (additionalProperties: false & required)
The challenge. Groq's structured-output engine with strict: true returns HTTP 400 if any object in the JSON schema is missing "additionalProperties": false, or fails to list every property in its required array — including defaulted Pydantic fields and free-form mappings such as dict[str, str].
The solution. We built a recursive, provider-aware schema sanitizer (m1/schema_utils.py). It walks the Pydantic JSON-schema tree and dynamically injects "additionalProperties": false, populates the required array for objects that declare properties, and strips invalid required arrays from free-form dictionaries — so the same Pydantic models work unchanged across every provider in the chain.
3. Over-claiming vs. Contextual Discrepancies
The challenge. LLMs naturally classify "12% math gain in high schoolers" and "0% gain in adult vocational classes" as a direct, genuine contradiction.
The solution. We engineered a comparability-aware system prompt (CONTRADICTION_SYSTEM) that forces the model to evaluate population age, intervention type (standalone software vs. human–AI hybrid tool), and outcome metric before declaring a genuine contradiction. Differences across those dimensions are classified as CONTEXT_DIFFERENCE, producing nuanced verdicts such as SUPPORTED_WITH_LIMITATIONS instead of a spurious CONTRADICTED.
🎓 What We Learned
1. "LLMs for reasoning, Python for control and math." Never rely on an LLM to perform arithmetic, count evidence items, or decide whether it has "enough" data. LLMs excel at qualitative extraction; Python heuristics excel at deterministic scoring and guardrails. The whole sufficiency engine is deterministic precisely so a verdict can be reproduced and defended.
2. Provider diversity is essential. Depending on a single LLM provider creates a single point of failure. A task-aware gateway that routes light work to fast models (Groq) and heavy synthesis to reasoning models (Gemini / Qwen) dramatically reduces both latency and cost — and survives a provider outage without dropping the investigation.
3. Calibration builds trust. Users distrust binary "Yes/No" answers for complex scientific claims. Showing a calibrated verdict with explicit limitation disclosures, confidence scores, and traceable citations increases user trust tenfold. The most useful output of Reality Checker is often the sentence "supported for high-school mathematics, unproven for adult vocational learners" — a sentence no binary classifier can produce.
Built With
- artificial-intelligence
- chromadb
- fastapi
- framer-motion
- google-gemini
- groq
- hugging-face
- json-schema
- langchain
- machine-learning
- multi-agent-systems
- natural-language-processing
- next.js
- openai-api
- pydantic
- pytest
- python
- react
- retrieval-augmented-generation
- semantic-cache
- sqlite
- tailwind-css
- typescript
- vector-search


Log in or sign up for Devpost to join the conversation.