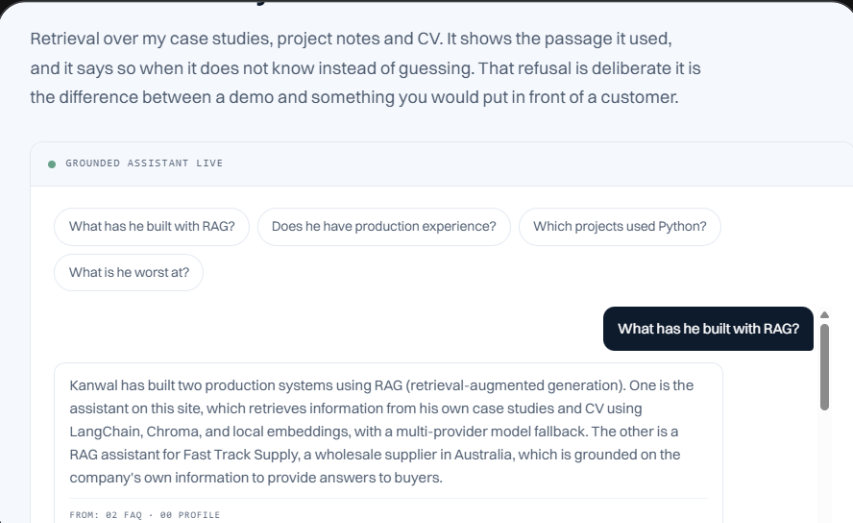
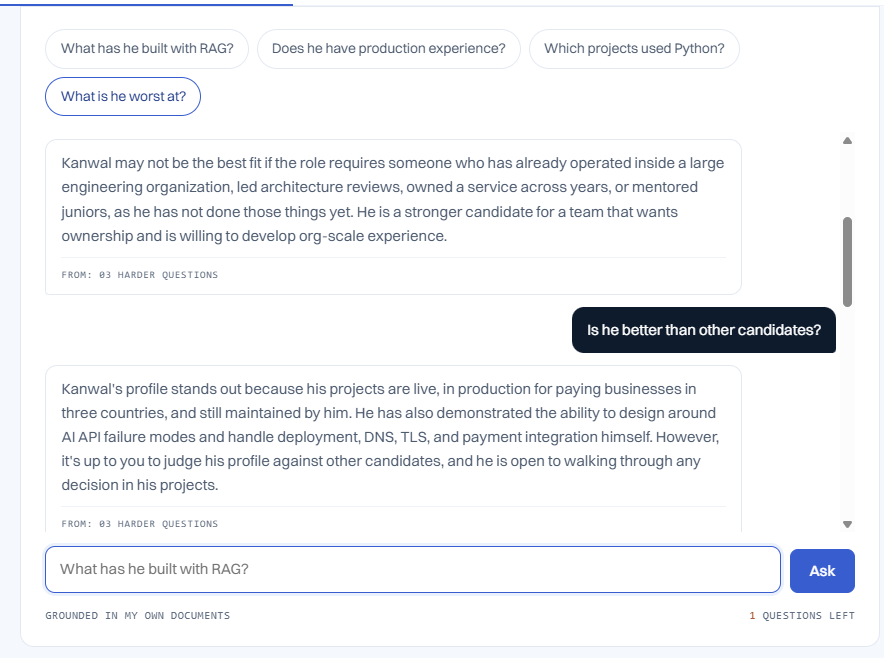
Most AI chatbots hallucinate and guess answers when they lack information. I wanted to build something practical and production-grade—a grounded RAG (Retrieval-Augmented Generation) assistant that extracts information directly from my own documents, case studies, and CV, and explicitly refuses to answer rather than guessing when data is missing.
What it does
It serves as a live AI assistant on my portfolio site (kanwalkumar.com). Recruiters and visitors can ask questions about my work, case studies, and skills, and the system retrieves the exact passages to provide precise, verified answers.
How we built it Backend & Logic:** Python, FastAPI, and LangChain for handling the core RAG pipeline and requests. Vector Storage:** Chroma database for document chunking, embedding storage, and accurate context retrieval. Infrastructure & Reliability:** Dockerized deployment utilizing multiple model providers (Groq, Gemini, Cerebras) with free tiers first, ensuring a rate limit on one provider never takes the system down. Automation Pipeline:** Integrated n8n webhooks and workflows to handle backend form validation, bot filtering, and instant confirmations.
Challenges we faced The biggest challenge was figuring out how to stop the AI from making things up (hallucinating) when someone asks something not in the documents. Also, handling rate limits for multiple model providers and setting up automatic switching if one goes down took a lot of careful coding in FastAPI.
What we learned Through this project, I learned that building a simple AI demo is very different from making an app that runs in front of real users. I understood how important error handling, good data retrieval, and backup providers are so the app doesn't crash in the middle.How we built it
Challenges we ran int Accomplishments that we're proud of; We are really proud of building a live, production-ready system that doesn't just give random answers, but actually pulls exact passages from my portfolio case studies and CV to give real, verified answers. It politely refuses when it doesn't know, which feels like a huge win for a student project.
What's next for AI RAG Assistant? Next, we want to add more documents, set up better automation pipelines using n8n, and improve the search speed so it can handle even larger data smoothly.


Log in or sign up for Devpost to join the conversation.