-
-
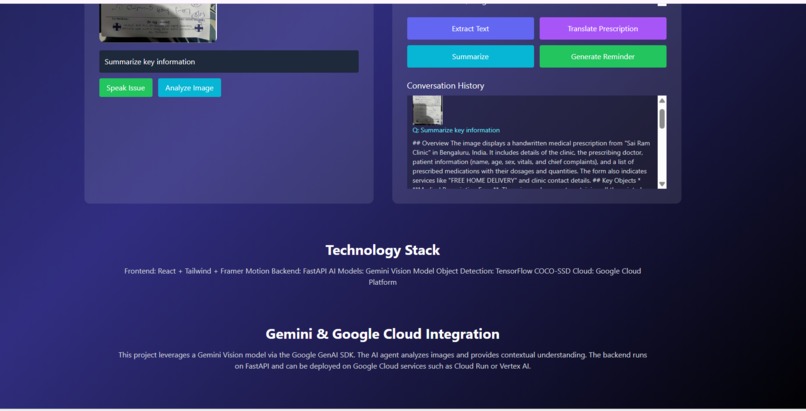
Demo 2
-
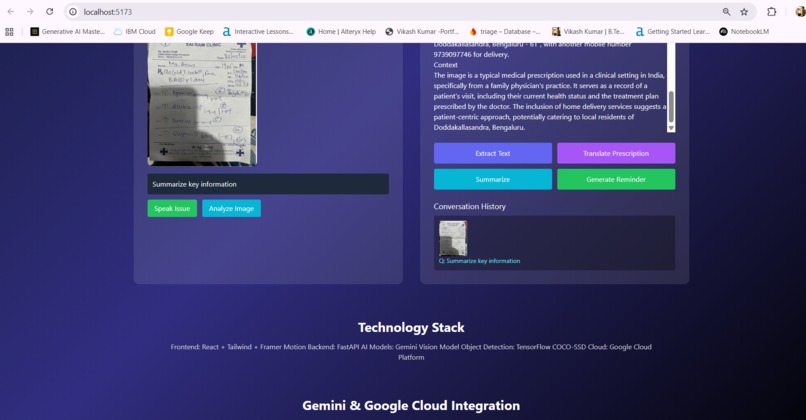
Demo 1
-
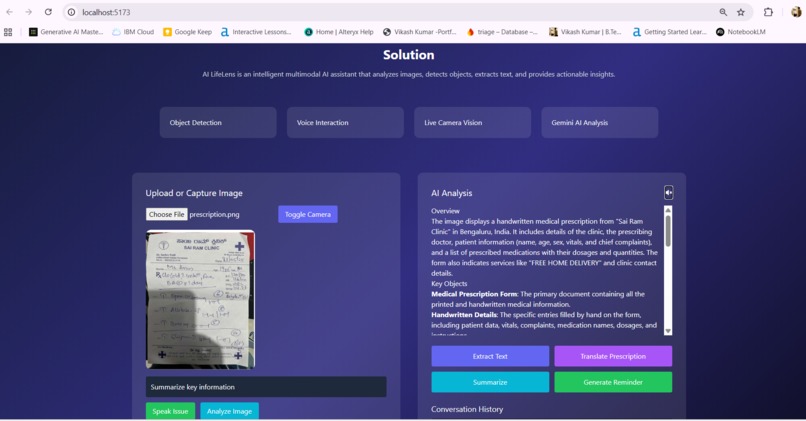
Demo 4
-
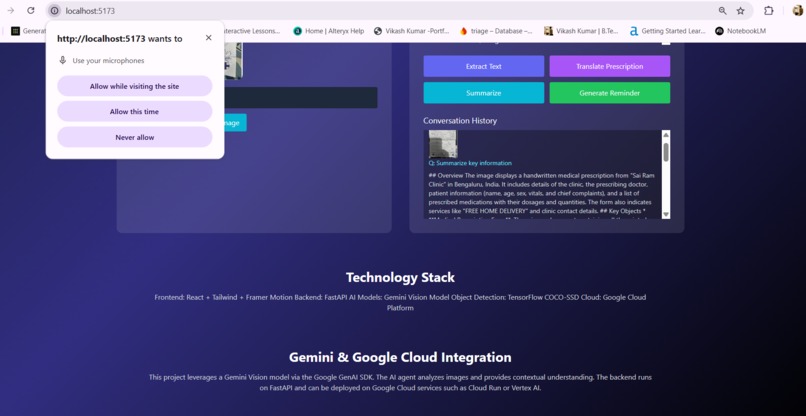
Demo 3
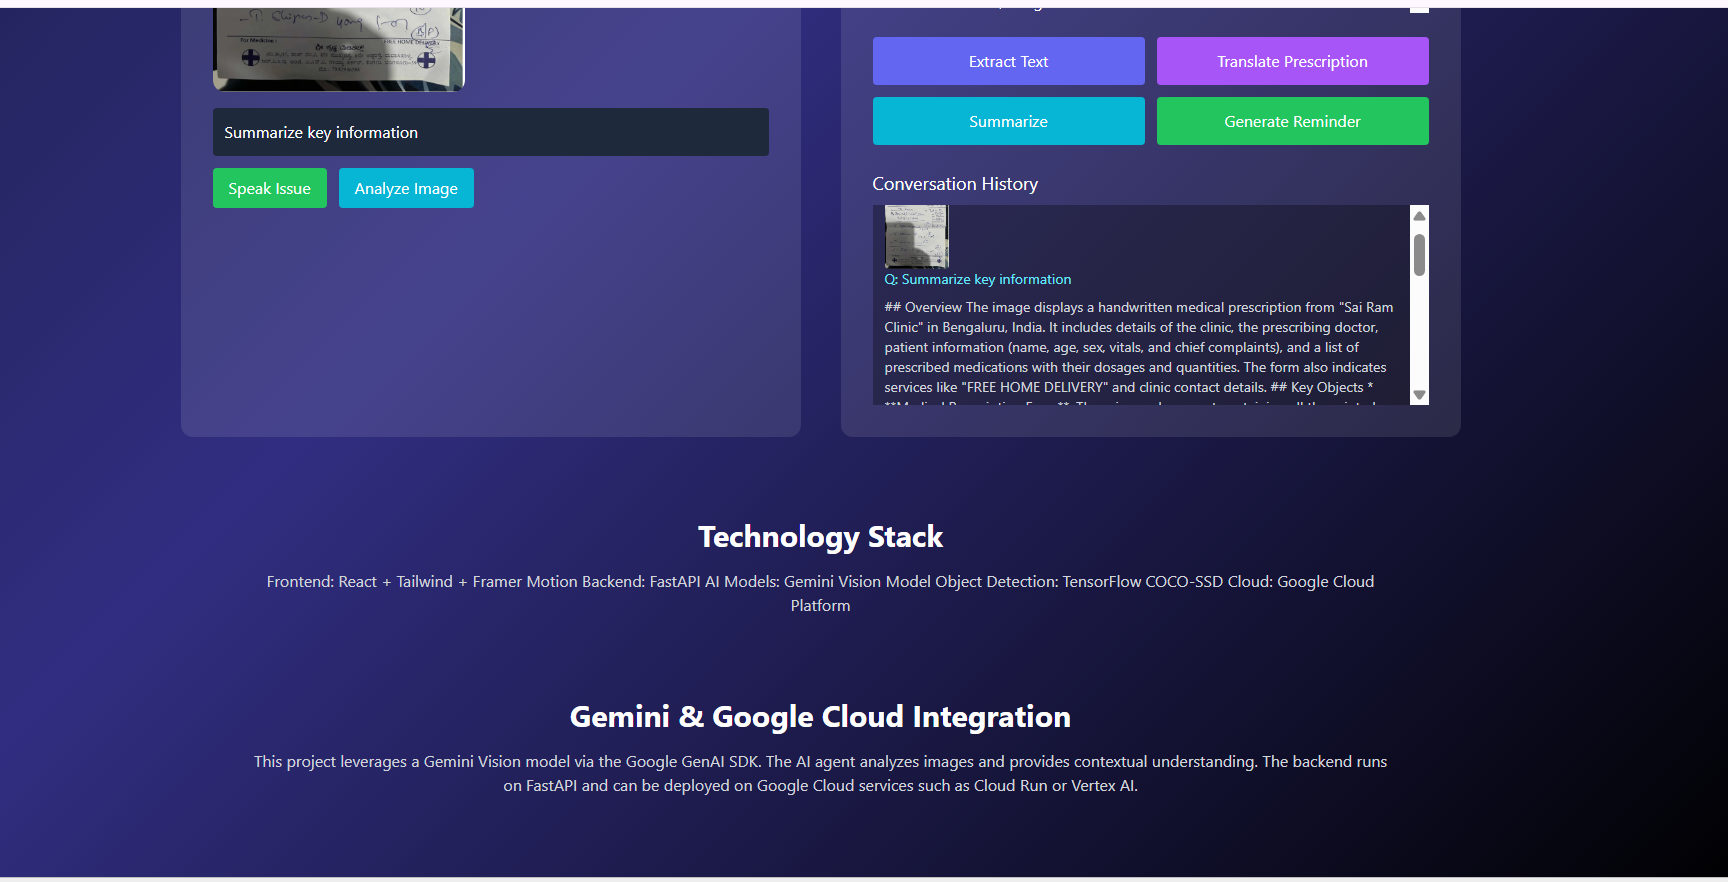
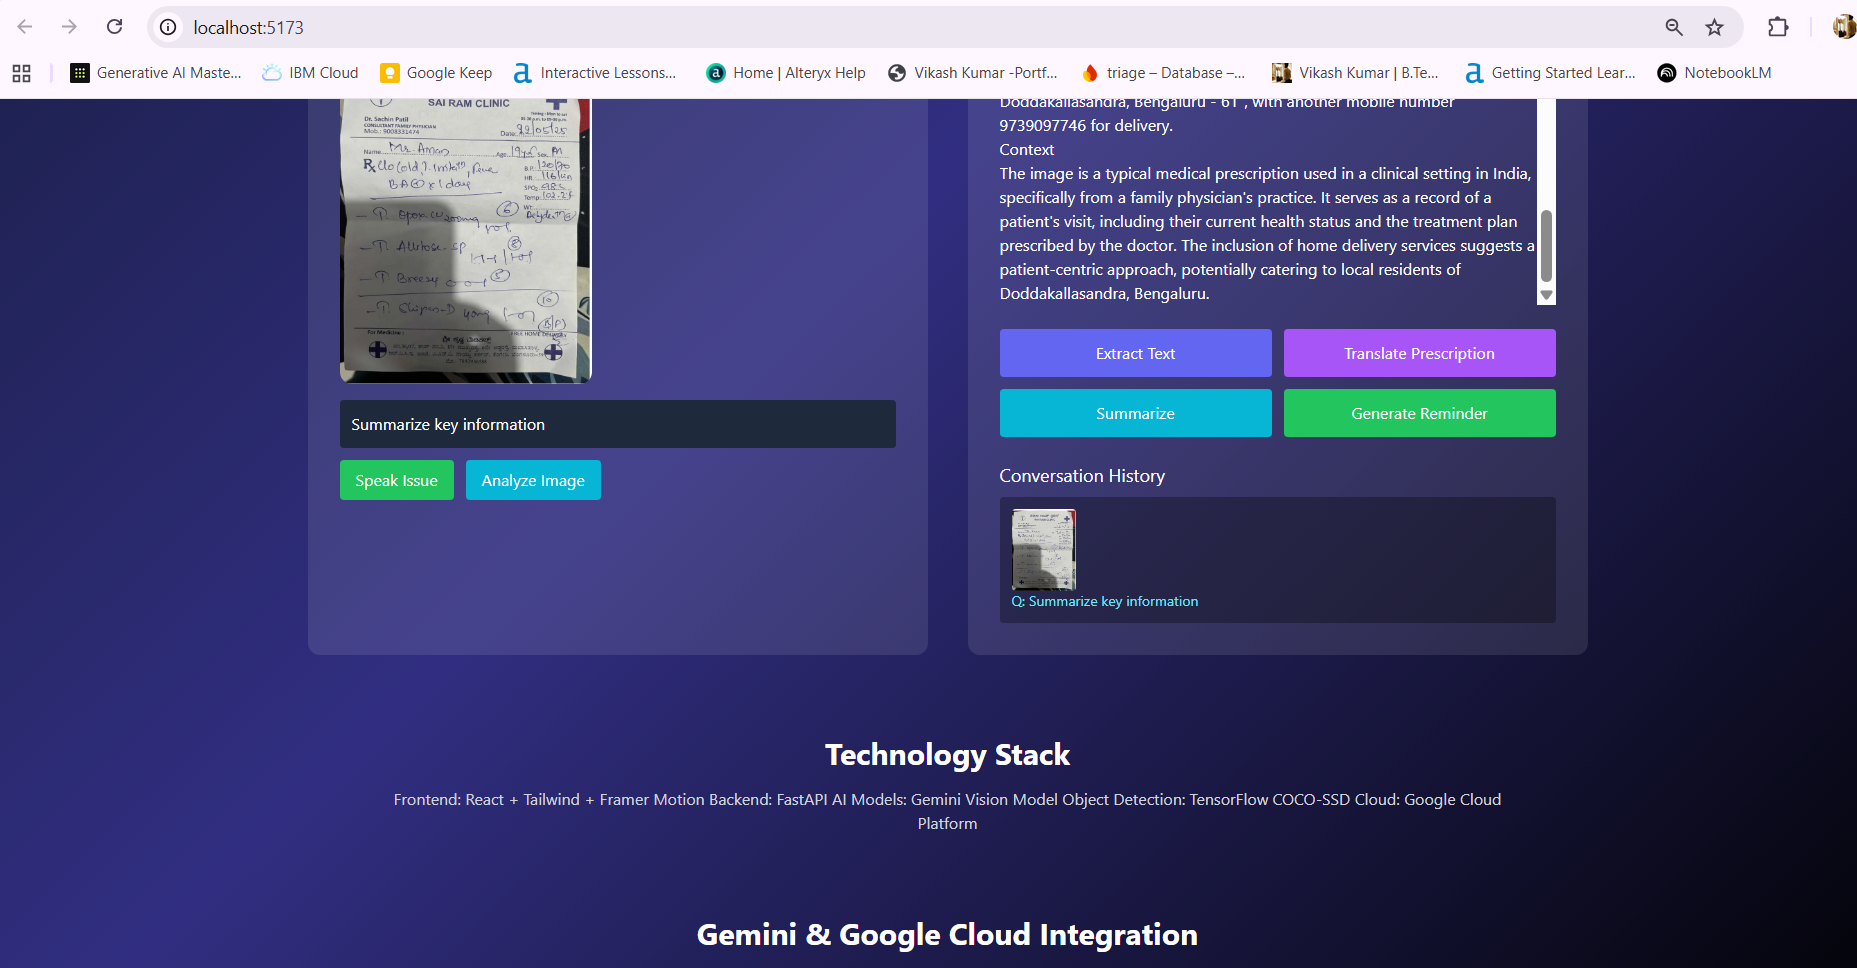
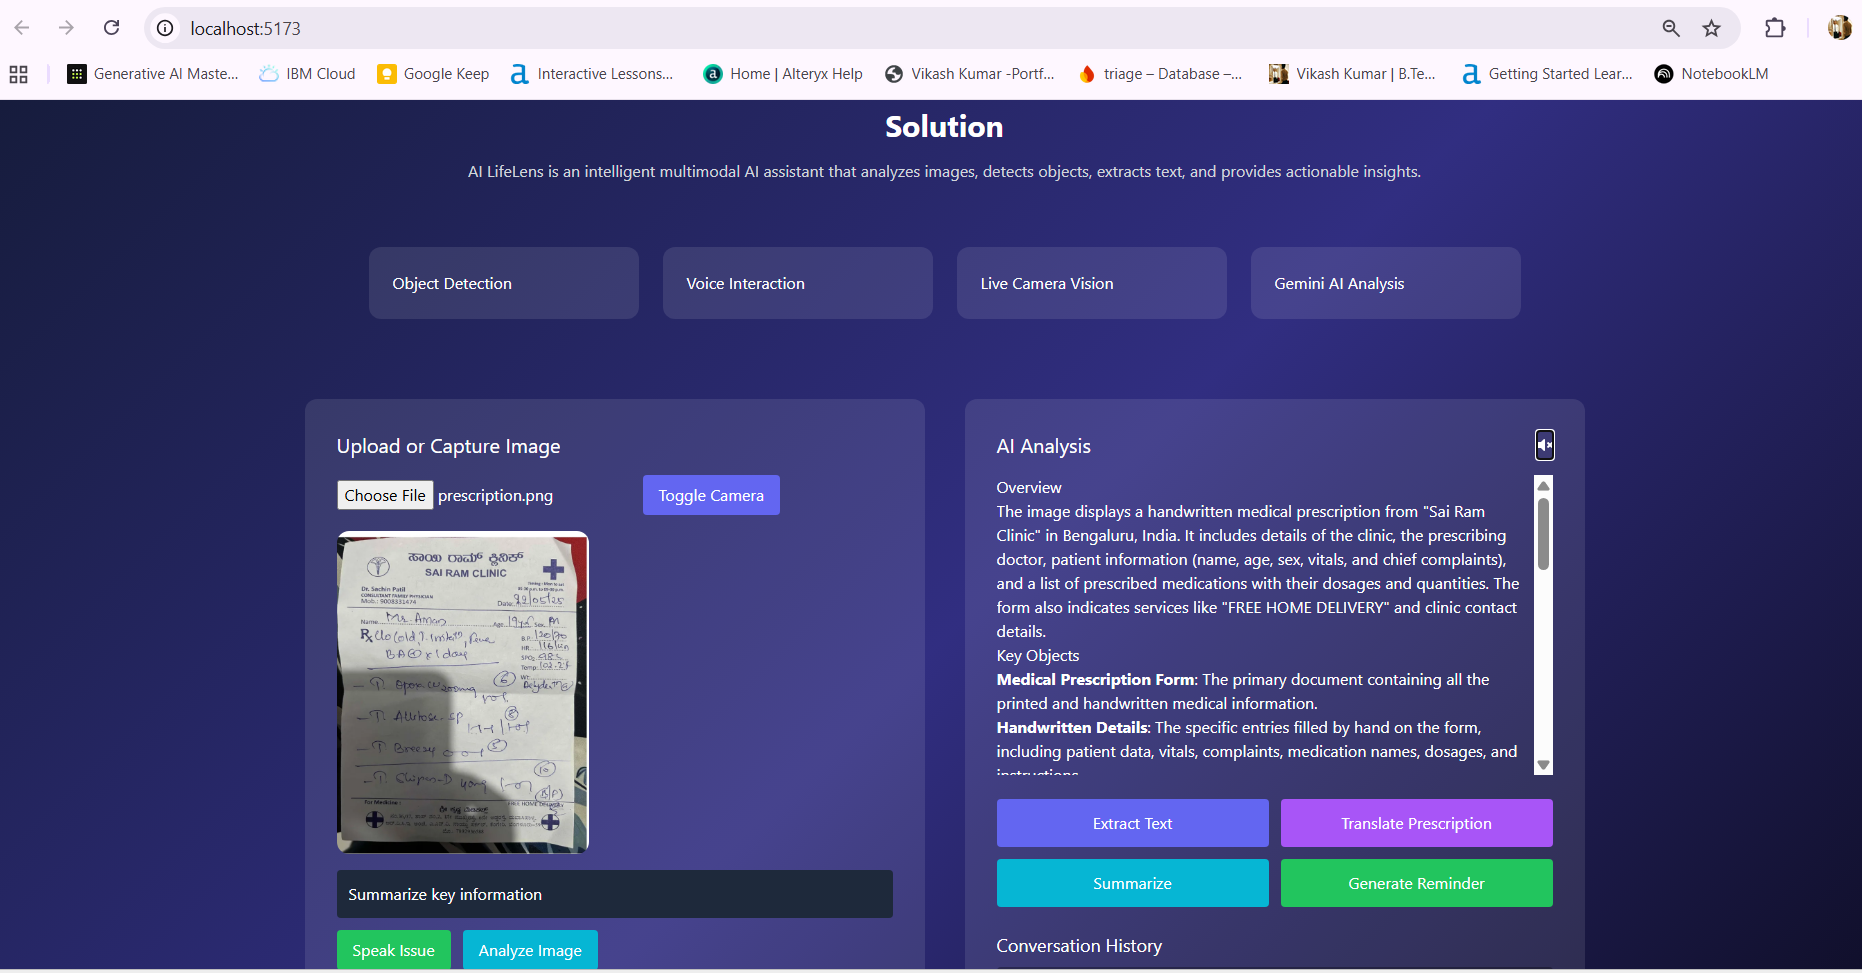
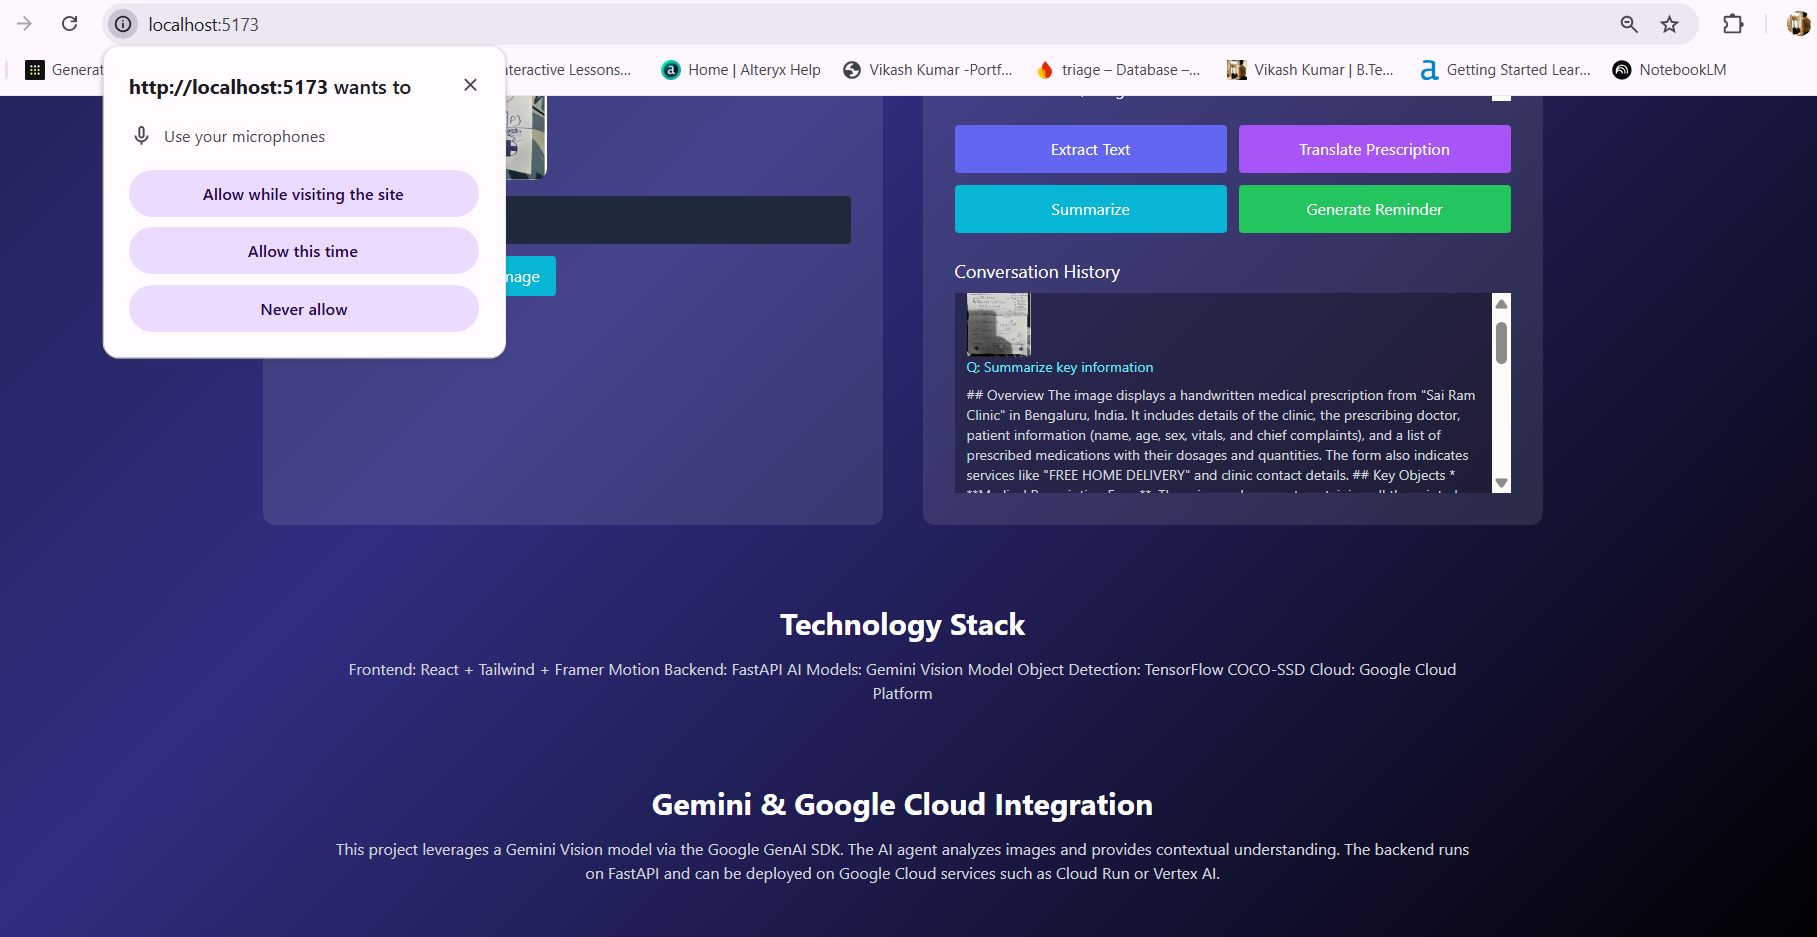
Inspiration
Understanding visual information such as medical prescriptions, product instructions, or complex scenes can be difficult and time-consuming. We wanted to build an AI system that helps people instantly understand what they see using intelligent visual analysis.
What it does
AI LifeLens is a multimodal AI assistant that analyzes images and provides meaningful insights. It can detect objects, extract text from images, and explain visual content using Gemini AI. Users can upload an image or use a live camera to interact with the system.
Key Features
- Object detection from real-world images
- Text extraction using OCR
- Gemini AI-powered explanation of visual content
- Voice interaction for a more natural experience
- Live camera vision analysis
How we built it
The system combines computer vision and generative AI technologies. Image processing and object detection analyze the visual content, OCR extracts text from documents or prescriptions, and Gemini AI generates contextual explanations and insights.
Challenges we ran into
One of the main challenges was integrating multiple AI components such as vision models, OCR, and generative AI into a seamless workflow. Ensuring accurate interpretation of complex images and optimizing response time were also key challenges.
What we learned
Through this project we learned how to combine computer vision with multimodal generative AI to create practical real-world applications. We also gained experience in integrating AI APIs, image processing, and interactive user interfaces.
Future improvements
- Support for more languages
- Enhanced real-time scene understanding
- Accessibility features for visually impaired users
- Integration with wearable devices or mobile apps
Built With
- computer-vision
- css
- google-cloud
- google-gemini-api
- html
- javascript
- node.js
- ocr-(tesseract)
- python
- react
- speech-recognition
- vite
- web-camera-api


Log in or sign up for Devpost to join the conversation.