-
-
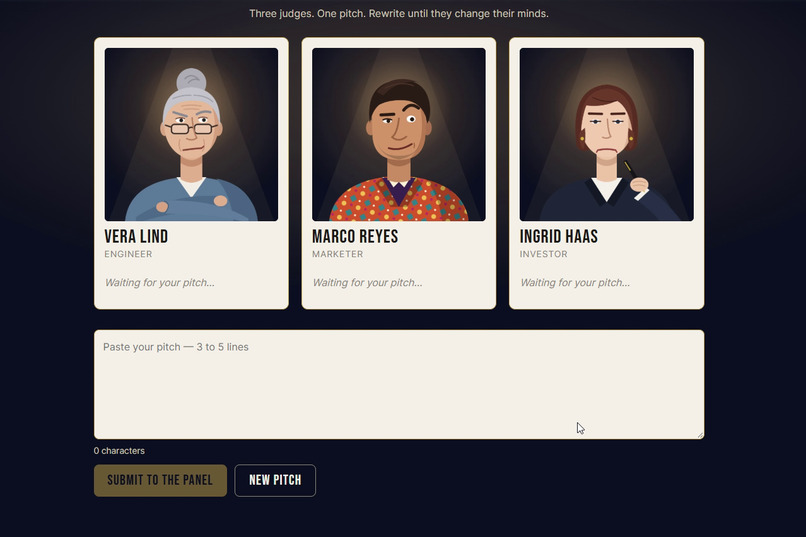
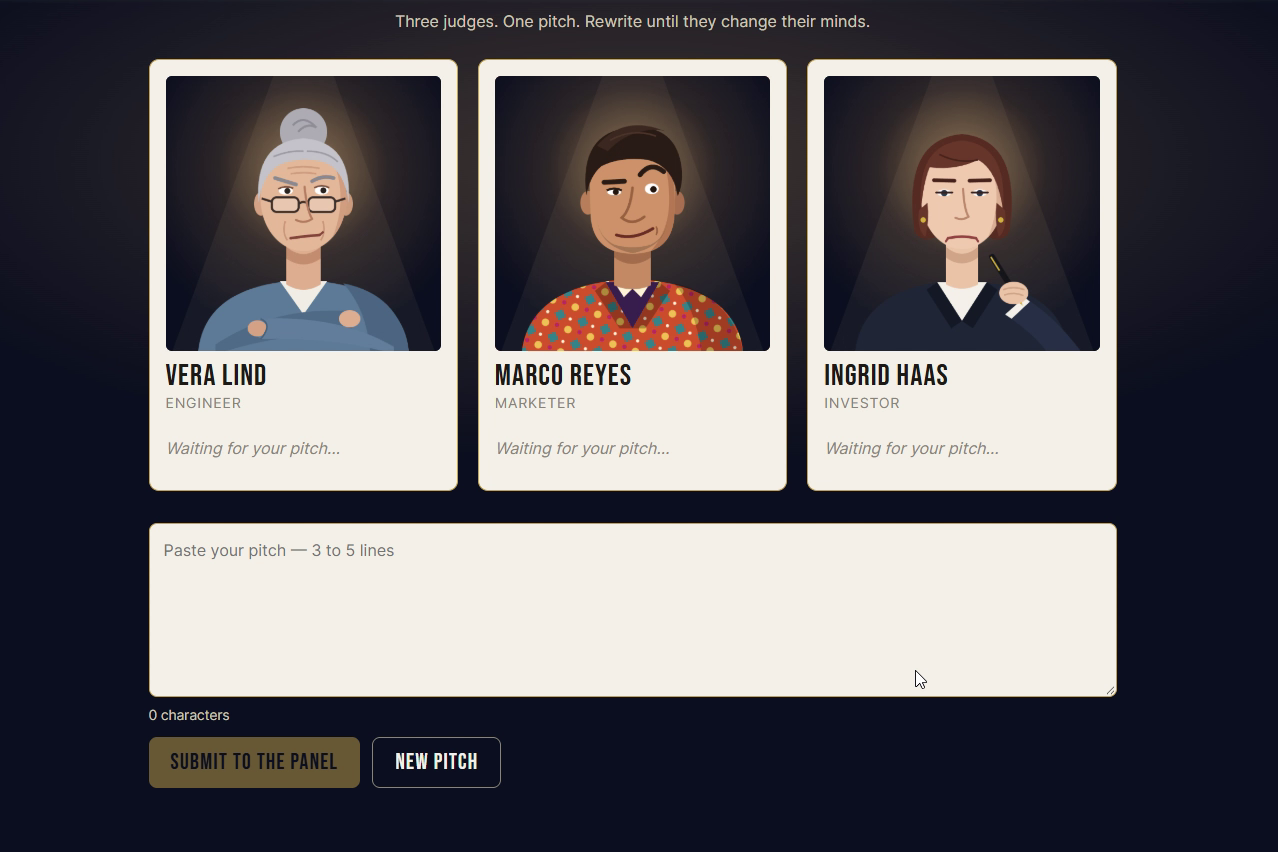
The panel: a skeptical engineer, a marketer, and an investor, waiting for your pitch.
-
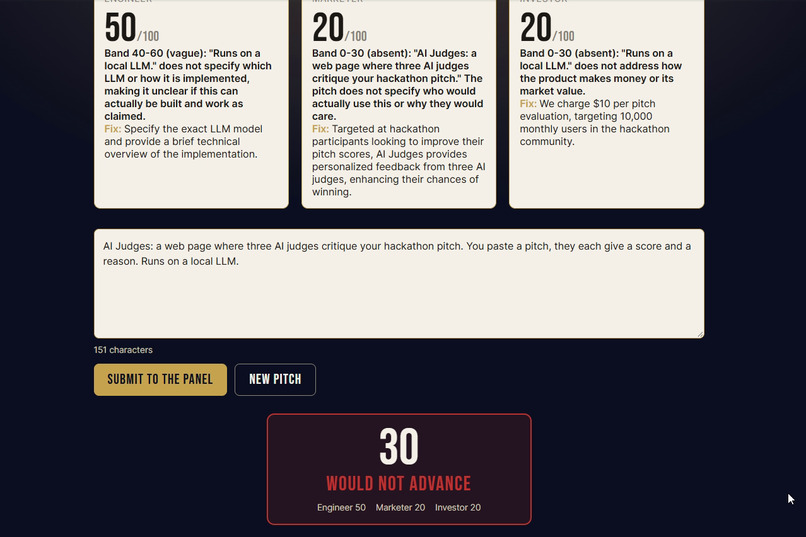
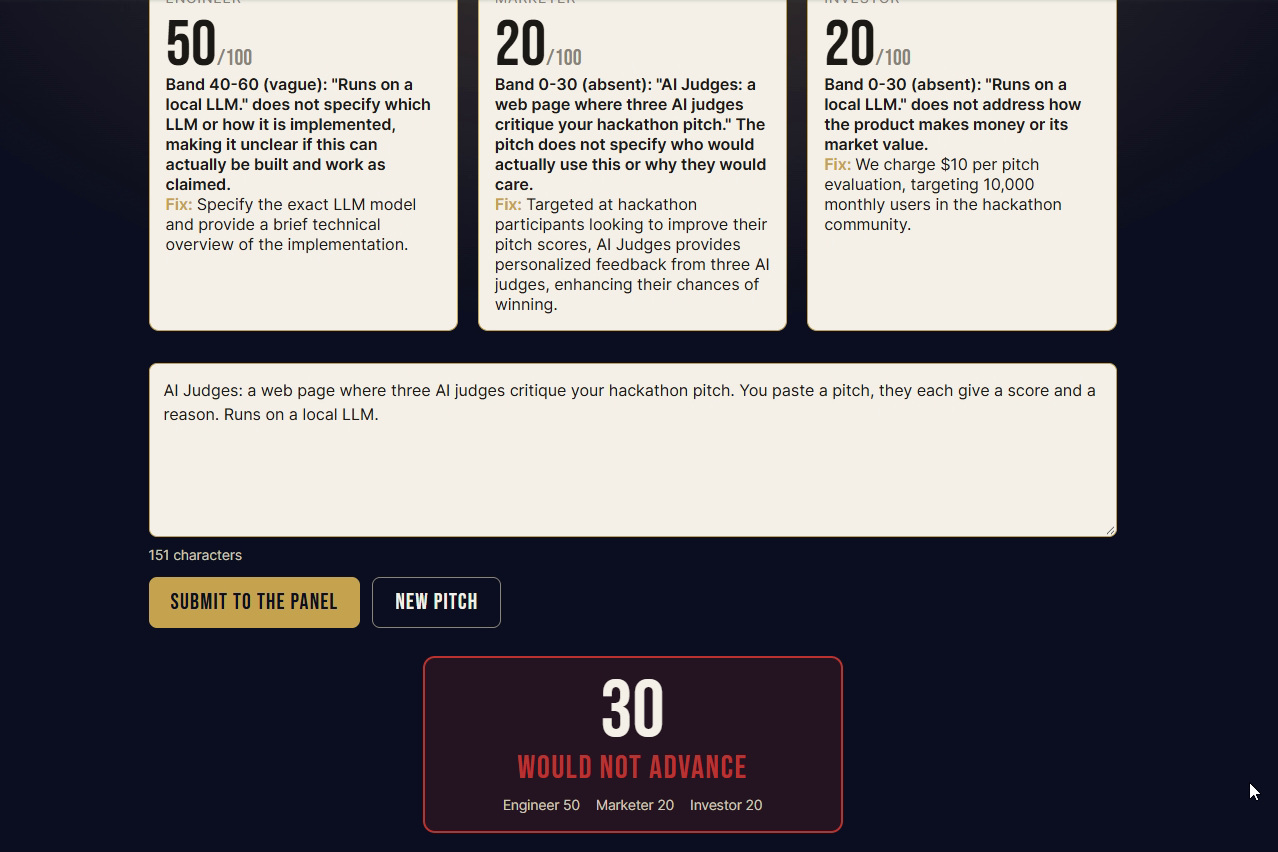
Round 1: a vague pitch scores 30. Each judge quotes the sentence it judged and gives one fix.
-
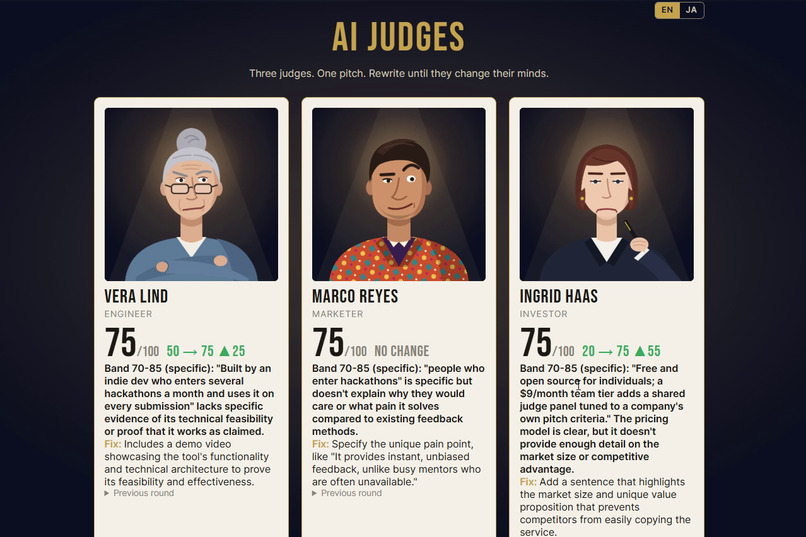
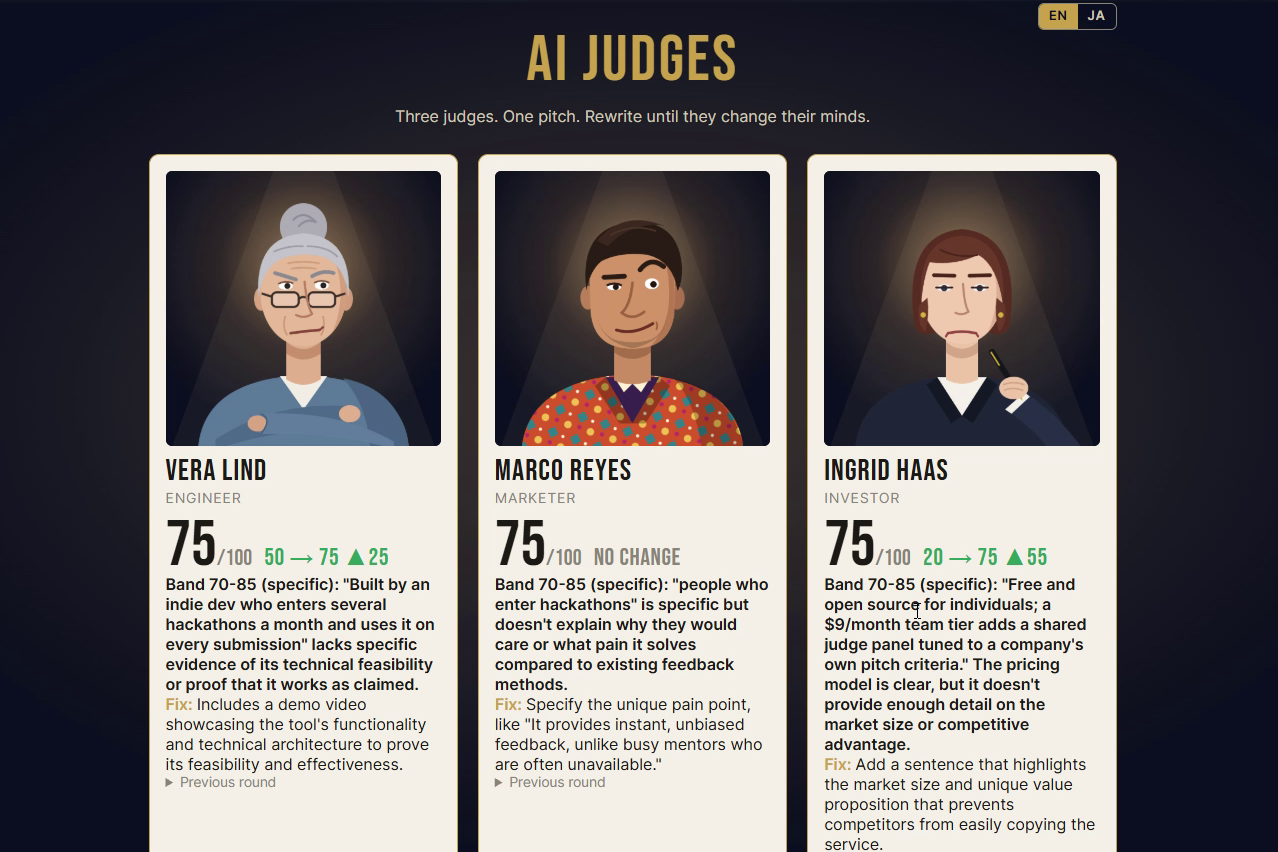
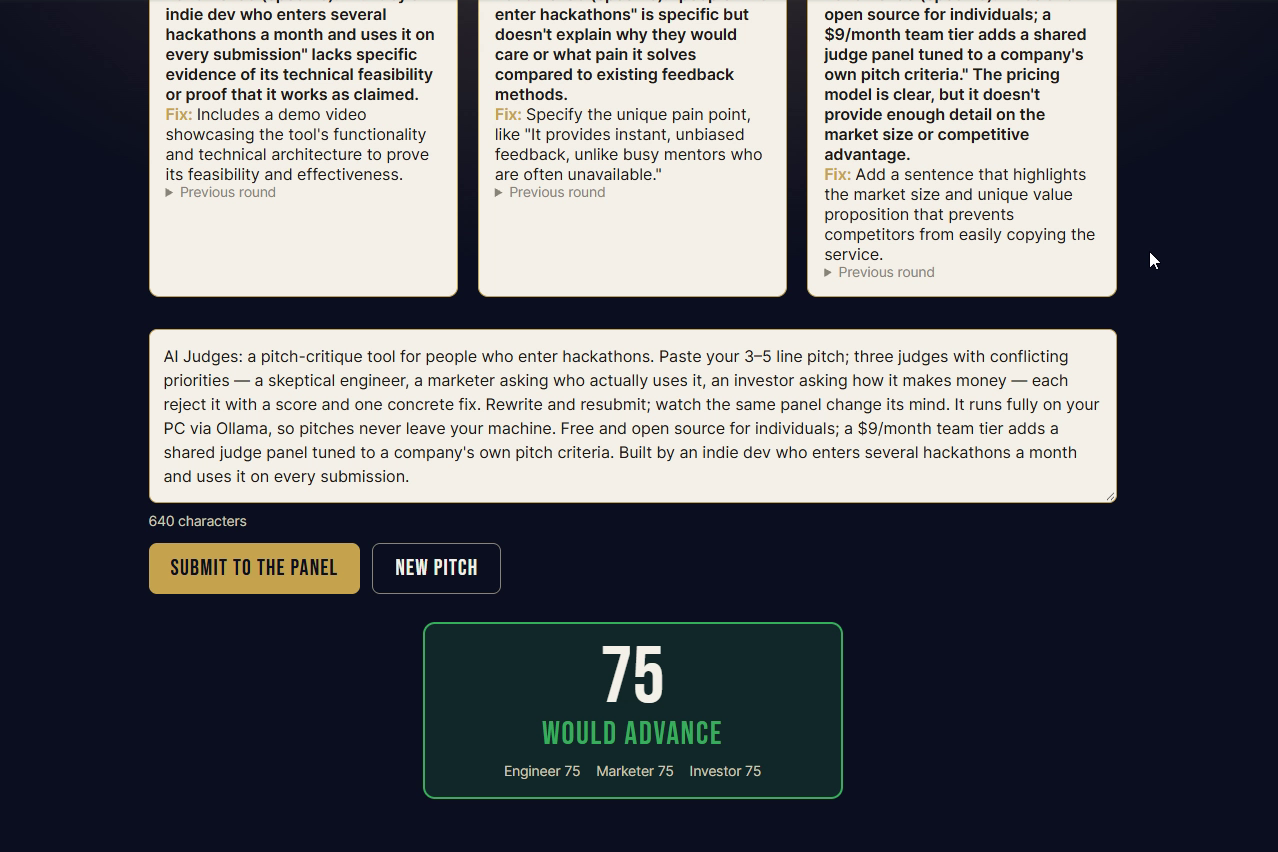
Round 3: after adding who it's for and how it makes money, all three judges move to 75.
-
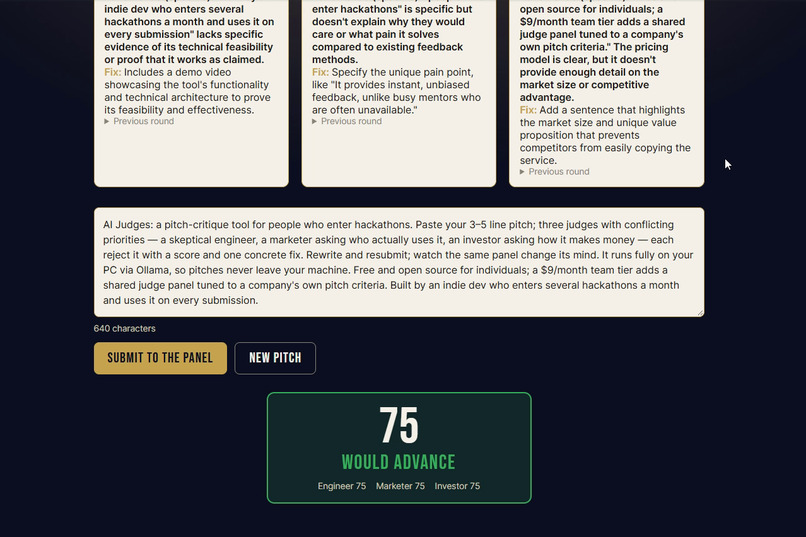
75 — Would advance. Scores went 30 → 48 → 75 by rewriting three sentences. Everything ran locally on Ollama.
What it does
AI Judges is a pitch-critique panel that runs entirely on your own PC. Paste a 3–5 line hackathon pitch and three AI judges with conflicting priorities — a skeptical engineer, a marketer who asks who would actually use it, and an investor who asks how it makes money — each reject it with a score, a quoted sentence from your pitch, and one concrete fix. Rewrite, resubmit, and watch the same panel change its mind: 30 → 48 → 75, "Would advance."
New in v1.1 (Submission review): attach your actual submission — Project story, README, demo-video script — and paste the hackathon's judging criteria. Each judge takes one criterion (Design, Presentation, Innovation), quotes the exact sentence from the exact document it is judging, and tells you what's missing. The UI and the verdicts work in English and Japanese; the verdict language can be switched independently of the pitch.
Why not just ask a chatbot to "be harsh"? Three things a chat can't give you: judges with conflicting priorities who disagree with each other; a score that moves only when the text changes (fixed seed, low temperature), so you see exactly which sentence won a judge over; and every verdict anchored to a quoted sentence from a named document, checked by code, so the panel can't complain about something you already said.
What it feels like: you open one page and three judges are already sitting there, waiting. You paste, press "Submit to the panel", and the cards reveal left to right as each judge finishes reading — portrait, score, the quoted sentence, one fix. Rewrite in the same box and resubmit: each card shows "20 → 75 ▲55" or "no change", the old verdict folds away under "Previous round", and the total badge counts up to its verdict. If Ollama isn't running, one banner tells you so; if one judge fails, the other two keep their verdicts and that judge gets a retry button. Reload and it's all still there.
Who it's for
Solo builders and small teams who enter online hackathons — indie developers and students who can ship the code but have no one to read their pitch critically before the deadline, and get no explanation after they lose. Devpost's galleries are full of solid builds whose pitches never say who they're for or why it matters. I'm one of those builders: I enter several a month. AI Judges is the harsh pre-submission review I wished I had, and I ran this very submission through it (the first pass scored 72/72/20 and told me, correctly, that I had no evidence of reliability and no reason anyone beyond me would care — both fixed below).
How it's built
Four plain files (index.html, style.css, app.js, judges.js), no build step. The browser calls Ollama's native /api/chat directly with a JSON schema, so each judge returns evidence, source document, criterion, band, reason, score and fix in a fixed shape; the app validates every field, checks the quoted evidence really appears in the named document, and retries once before marking a judge as "left the room". The model is Qwen2.5 32B on an RTX 4090 with a quantized KV cache (6k context for pitches, 12k for full submissions) — about 3–4 seconds per judge for a pitch, 5–7 with documents, fully on the GPU. Judge portraits are hand-drawn SVGs rendered to PNG. No API key, no cloud, no cost per run, and nothing leaves the machine.
How I know it works
The 3-round demo (vague pitch → add the audience → add the business model) is written down as fixed inputs with expected scores and runs as a regression test against the real model. It has reproduced 30 → 48 → 75 on every run since the prompt was frozen, and the no-attachment request is byte-compared against a golden copy so later features can't drift it. Mocked tests cover validation, retry, the Ollama-down banner, persistence and both UI languages (50 checks).
I ran this submission through it
Before writing this page, I pasted my own Project story into AI Judges with this hackathon's three criteria.
| Pass | Design | Presentation | Innovation | What the panel said |
|---|---|---|---|---|
| 1st draft | 72 | 72 | 20 | No evidence it works reliably · "starting with me" gives no reason anyone else would care · never says what's new vs. existing tools |
| After fixes | 75 | 75 | 75 | Added "How I know it works", rewrote "Who it's for" around solo builders, added "Why not just ask a chatbot" |
The judges were right on all three counts. Whether their fixes earn points from the human judges is, fittingly, the real test of this project.
What I learned
The limit of v1 was the model's judgement, not the UI. Qwen 14B couldn't reliably tell "stated" from "missing" — it kept saying the audience was absent when the pitch named it. Switching to 32B and restructuring the prompt as evidence-first (quote the sentence → pick a band → explain → score) fixed it. The habit I'm keeping: once the core loop works, write the demo down as fixed inputs and an expected result, and make "the demo still ends the same way" the test every late addition must pass — it caught a one-line prompt change that silently dropped the final score from 75 to 67, and a 6k-context change that halved the speed.
Built With
- claude-code
- css
- html
- javascript
- ollama
- qwen

Log in or sign up for Devpost to join the conversation.