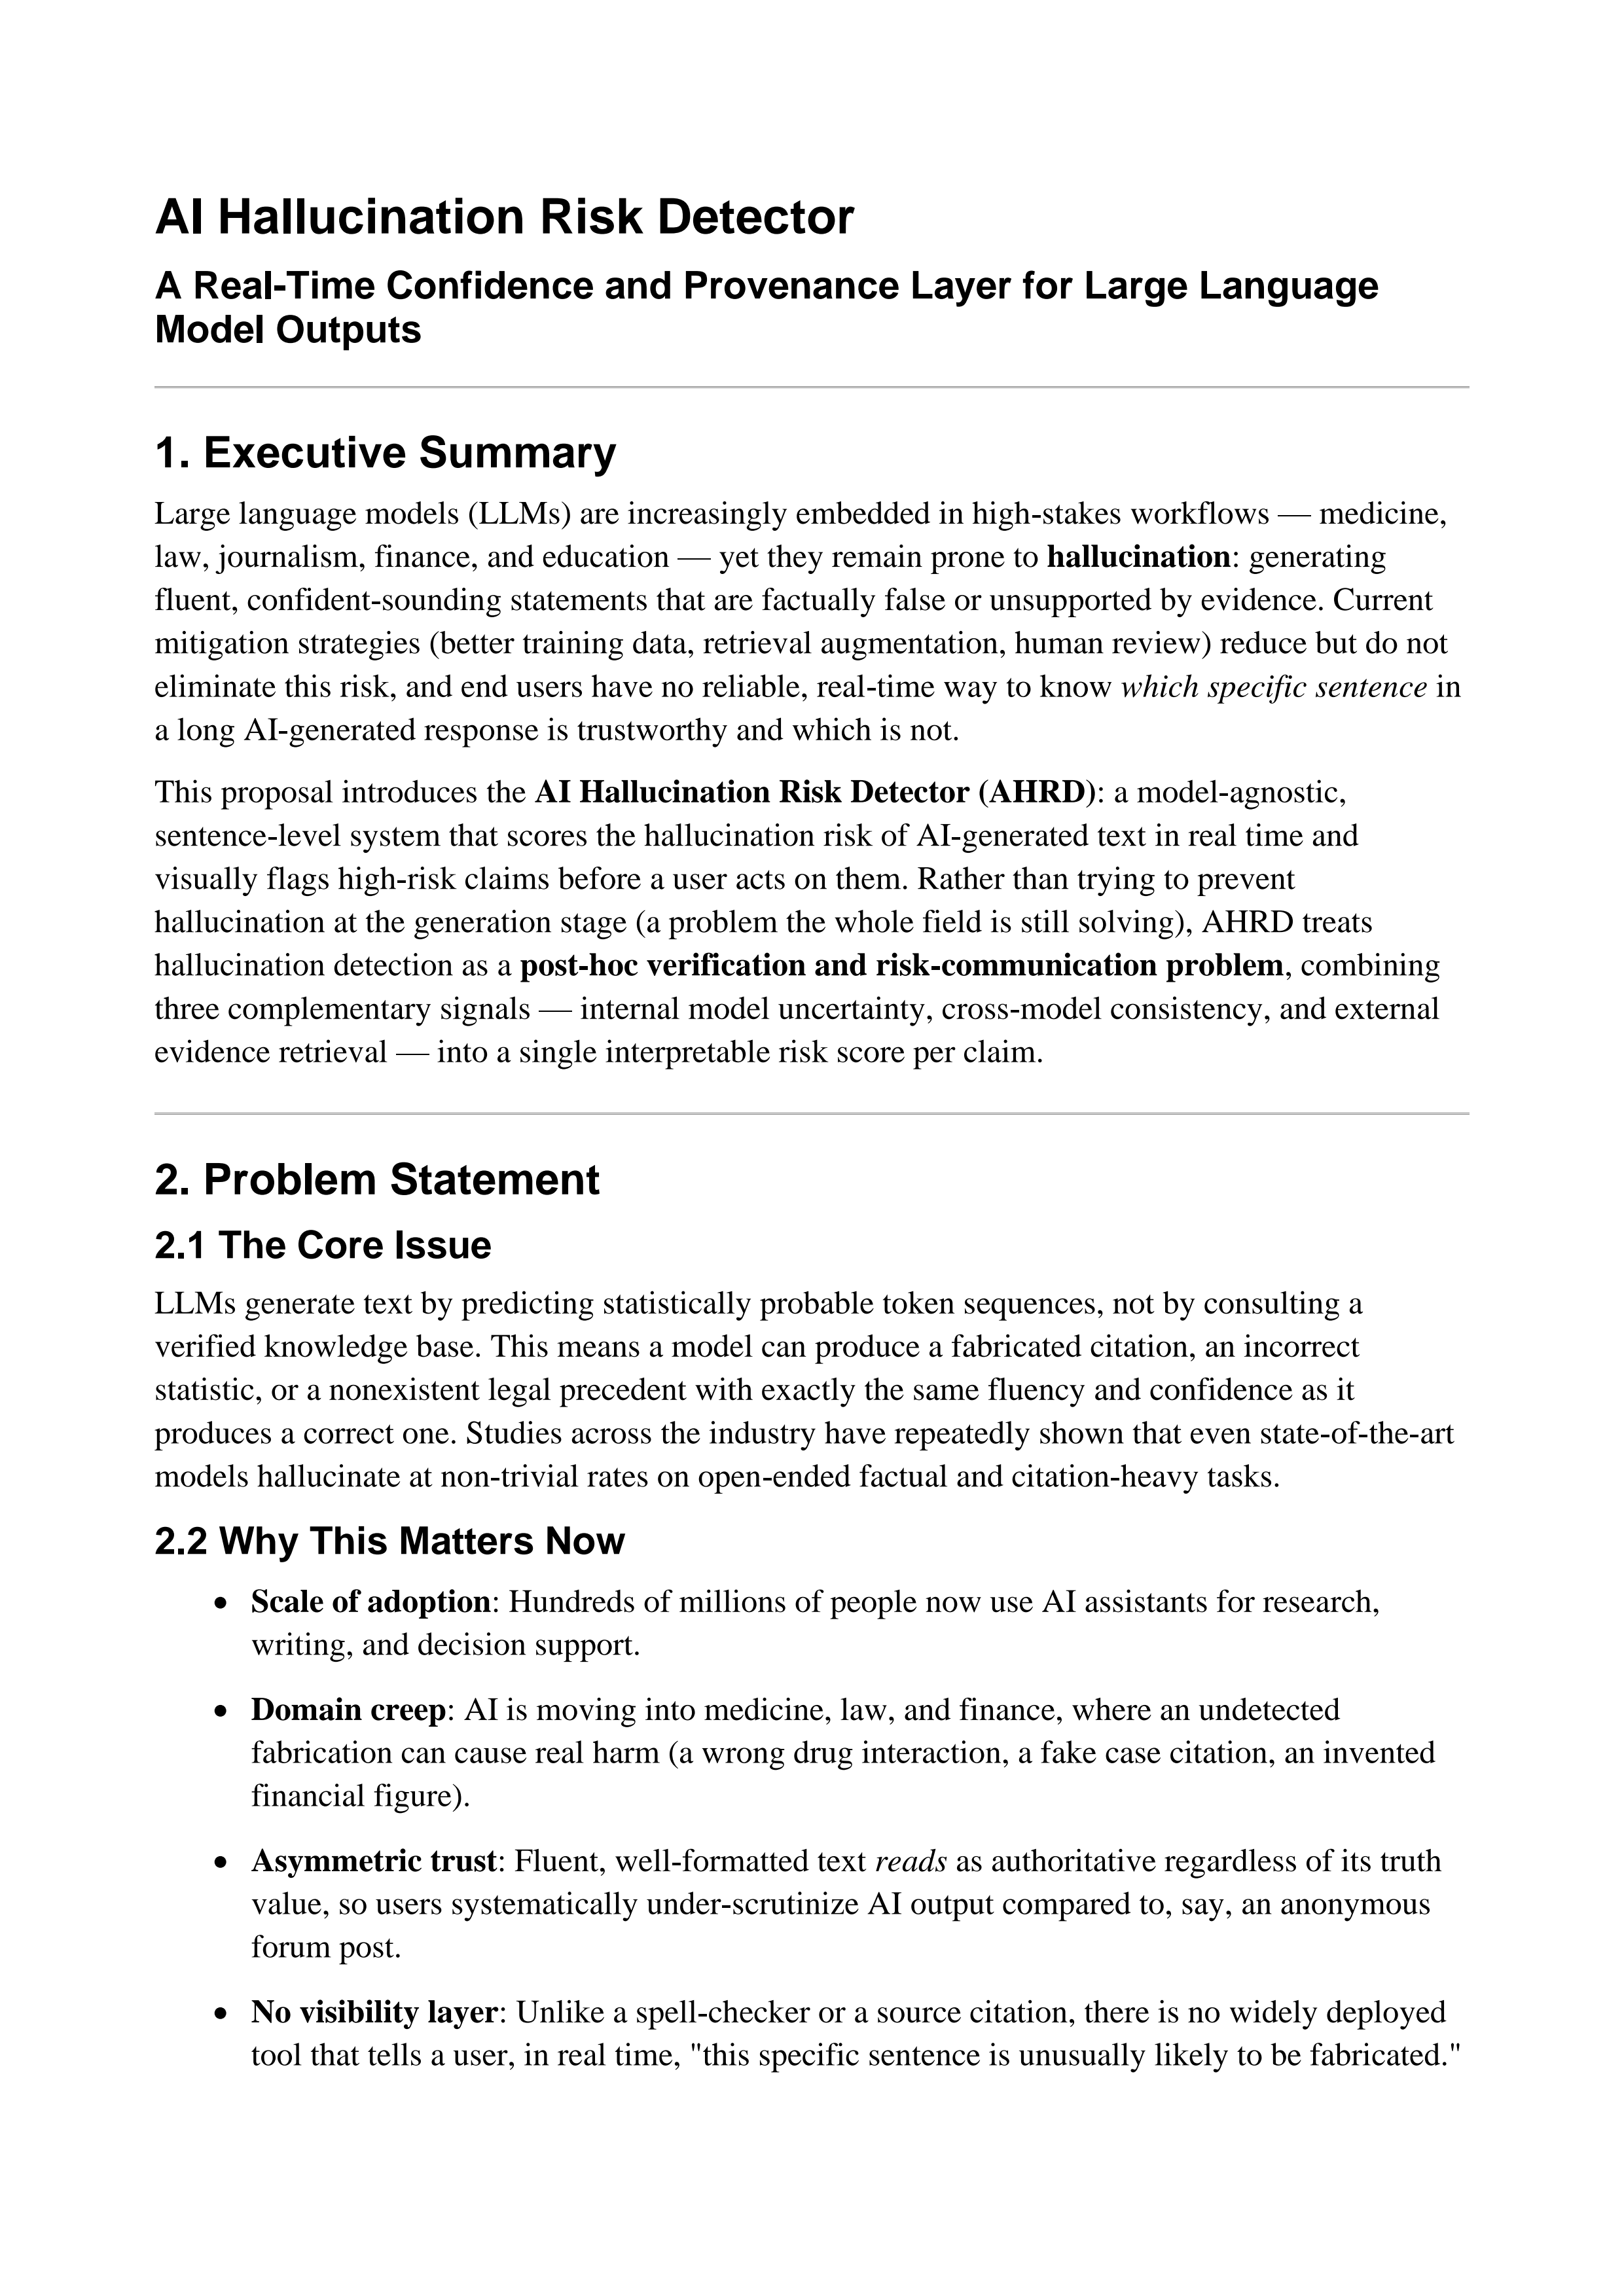
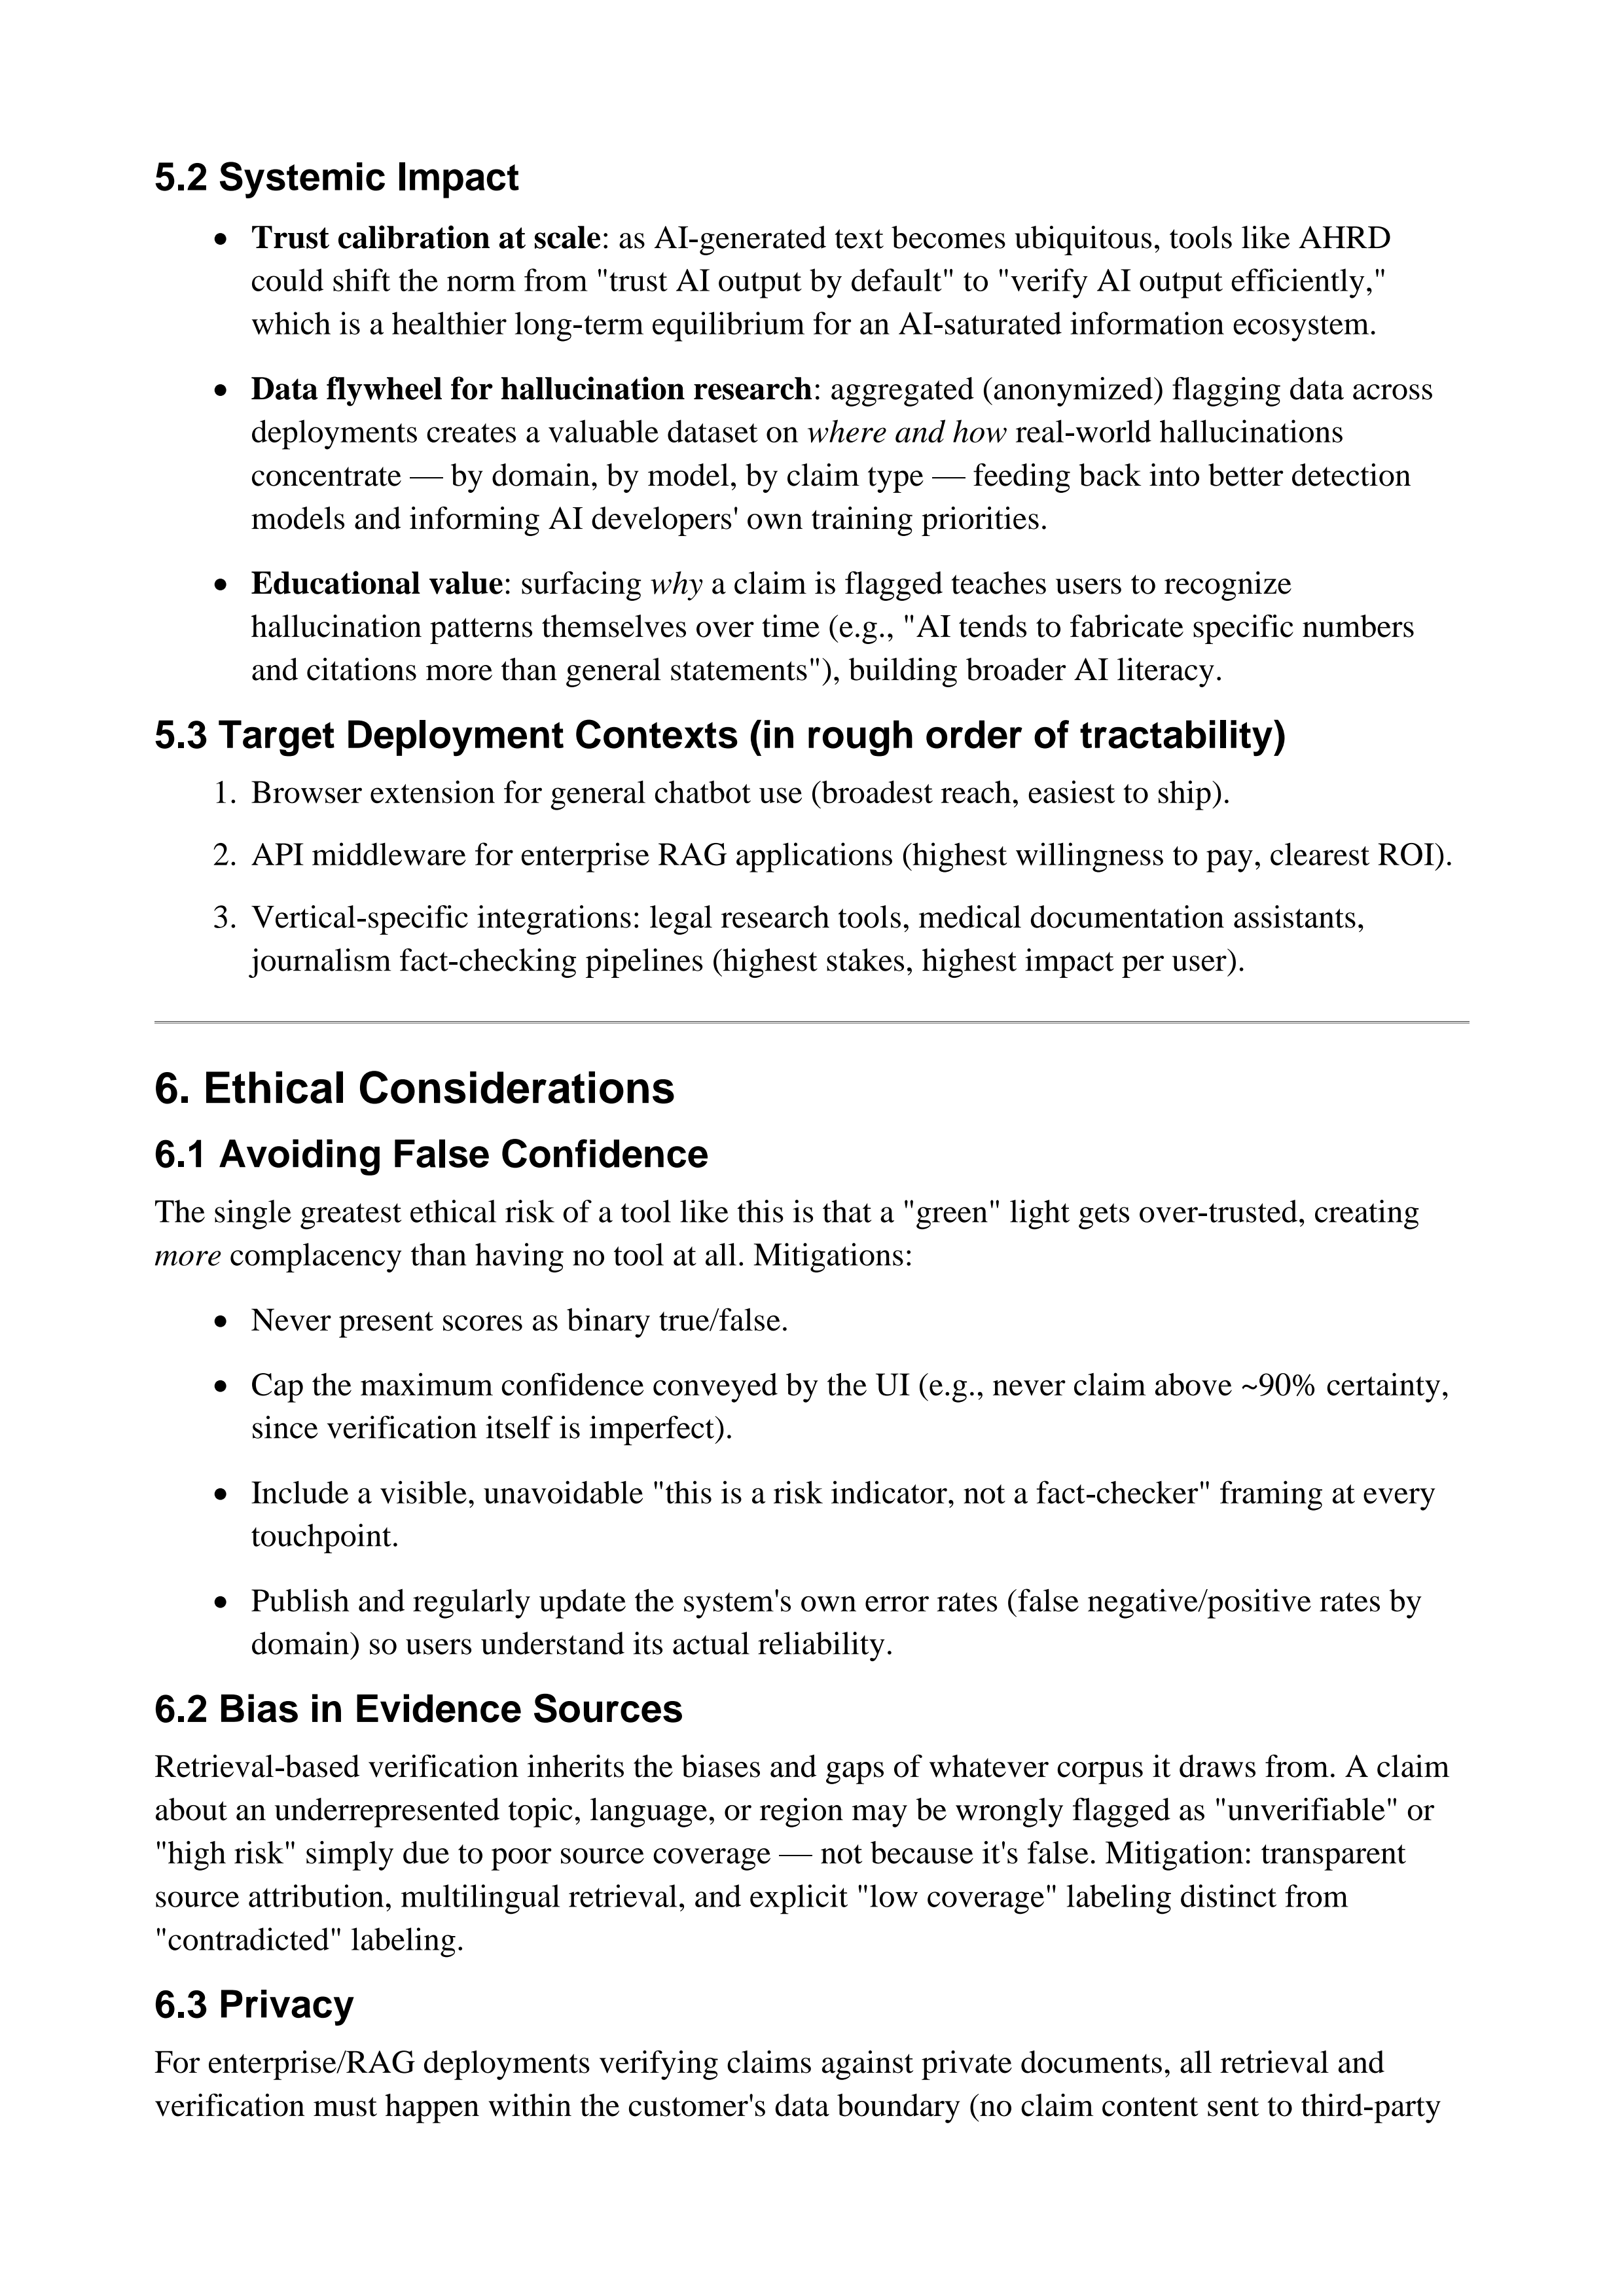
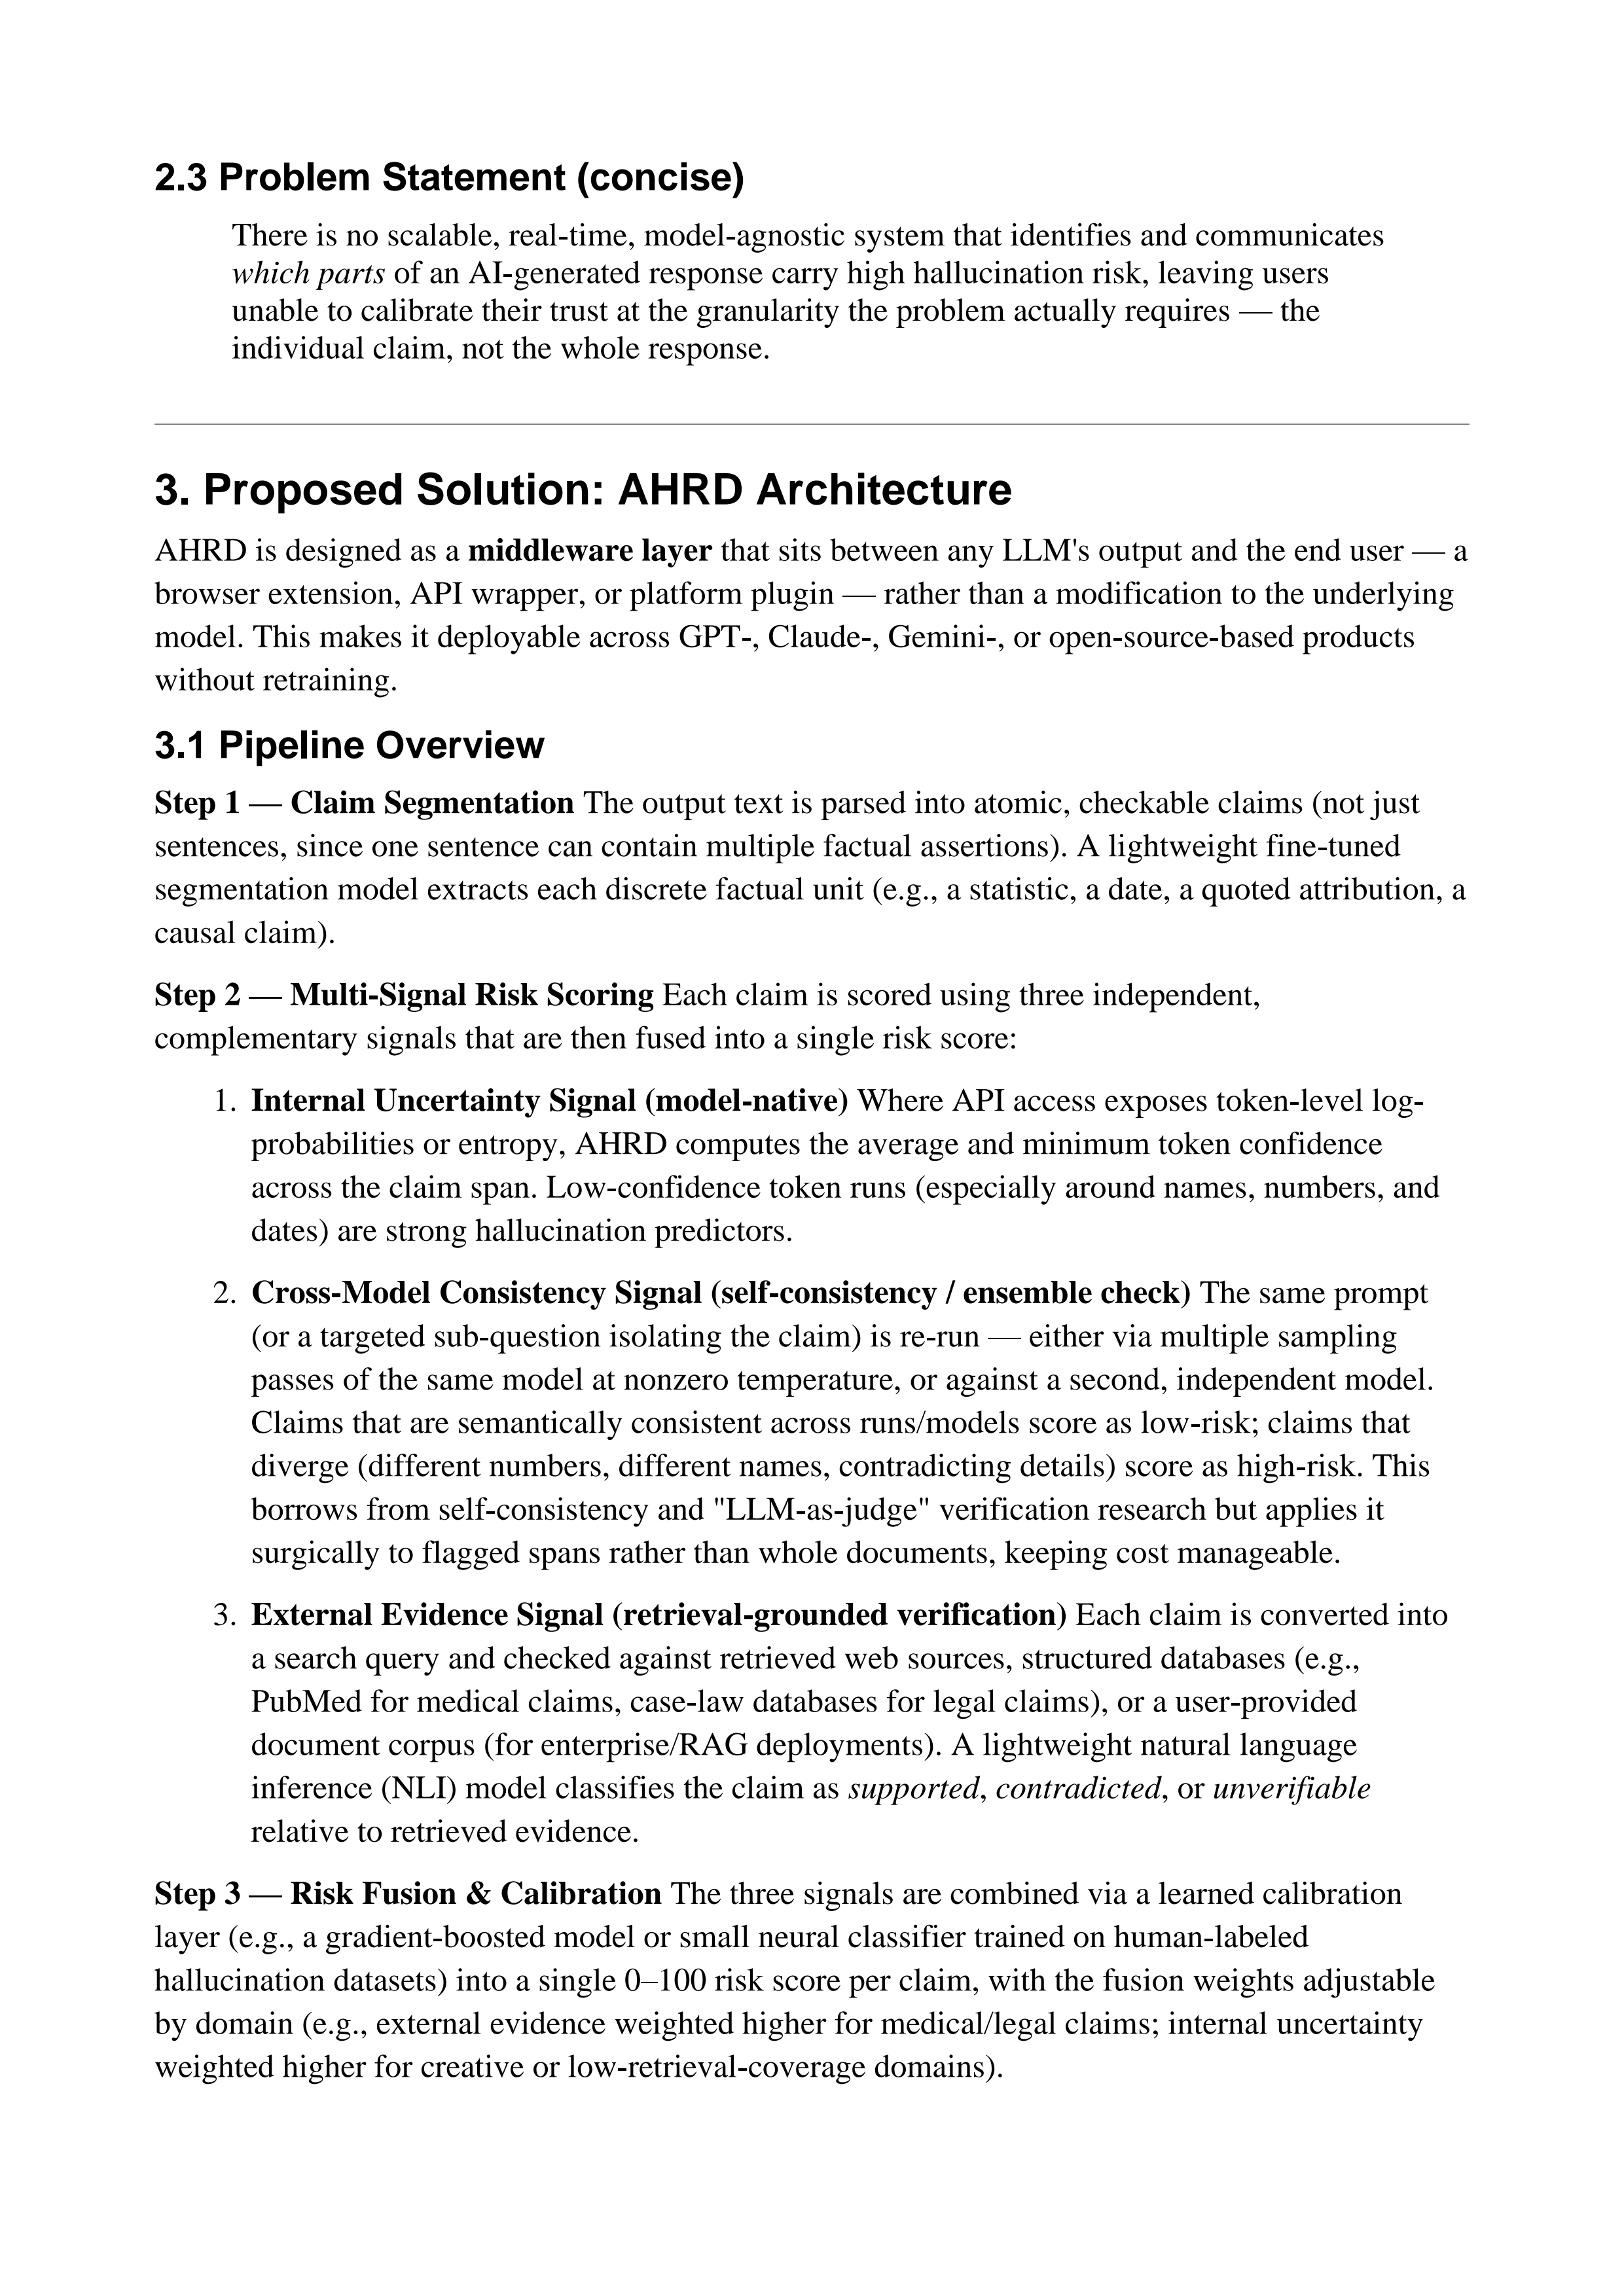
Large language models (LLMs) are increasingly embedded in high-stakes workflows — medicine, law, journalism, finance, and education — yet they remain prone to hallucination: generating fluent, confident-sounding statements that are factually false or unsupported by evidence. Current mitigation strategies (better training data, retrieval augmentation, human review) reduce but do not eliminate this risk, and end users have no reliable, real-time way to know which specific sentence in a long AI-generated response is trustworthy and which is not.
AI Hallucination Risk Detector
This proposal introduces the AI Hallucination Risk Detector (AHRD): a sentence-level system that scores the hallucination risk of AI-generated text in real time and visually flags high-risk claims.
Updates

Leave feedback in the comments!
Log in or sign up for Devpost to join the conversation.