-
-
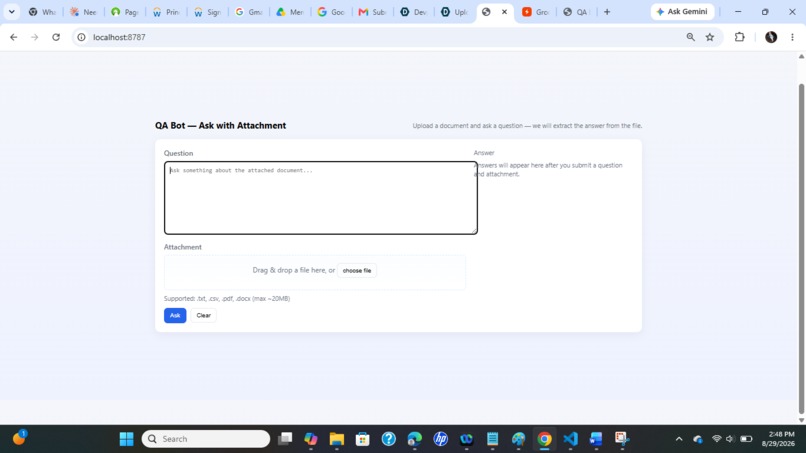
Step 1: CHAT BoT application launched.
-
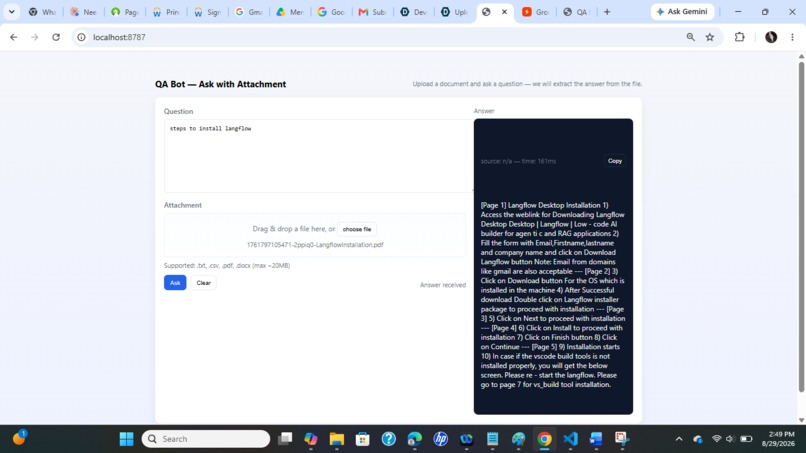
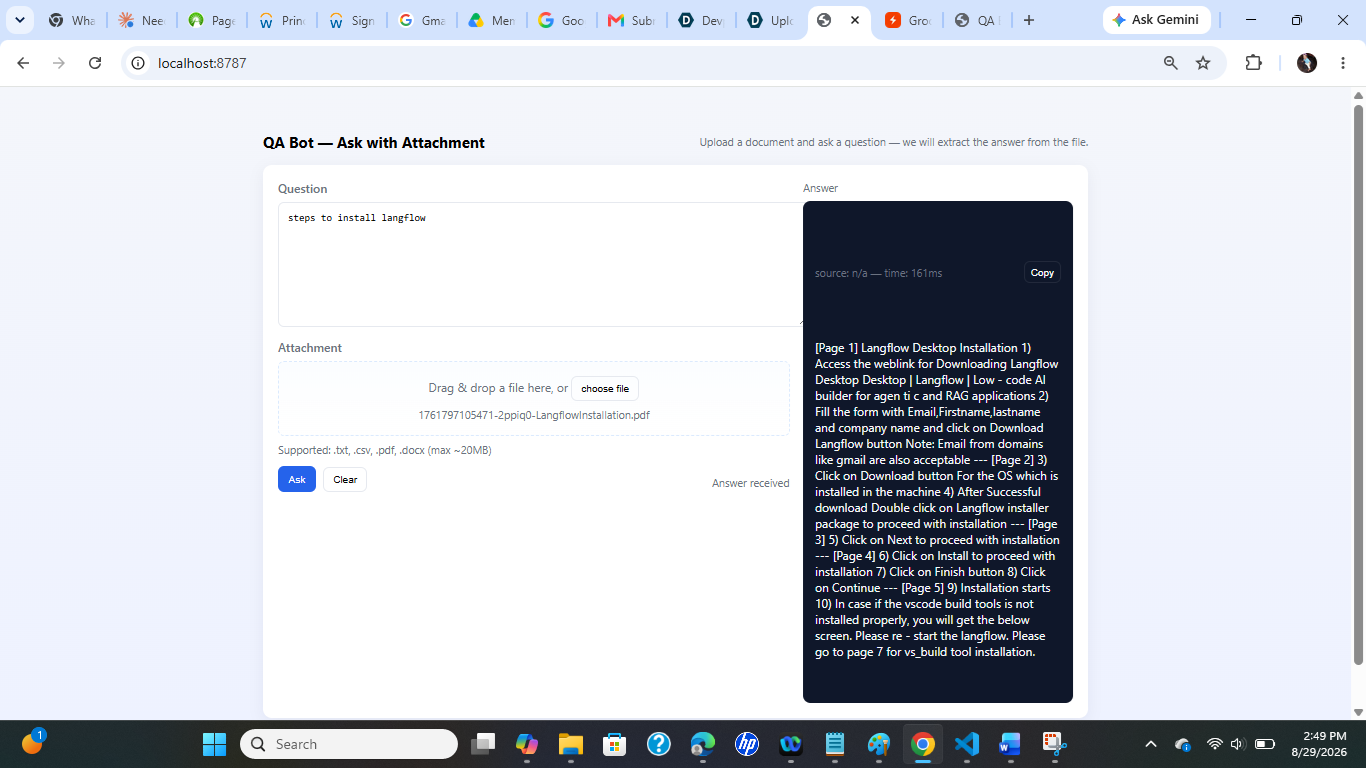
Step 2: Upload the source document and ask question, it will give the response from the source document based on the user query
Inspiration : The project was inspired by the challenge of navigating long documents, manuals, and PDFs where finding specific information is slow and inefficient. I wanted to create a tool that could instantly answer questions from any document — almost like having an intelligent assistant that understands the content better than the reader
What it does : The AI Chat Bot allows users to upload any document and ask natural‑language questions about its content. The system interprets the context of each query, retrieves the most relevant information using semantic search, and generates accurate, grounded responses. It transforms static documents into interactive knowledge sources.
How we built it : The chatbot is built using a Retrieval‑Augmented Generation (RAG) pipeline:
Document Upload & Parsing
The uploaded file is processed and split into meaningful text chunks.
Embedding Generation
Each chunk is converted into a vector representation using an embedding model: embedding =𝑓(chunk)
Vector Storage & Retrieval
Embeddings are stored in a vector database.
When a user asks a question, the system computes a query embedding and retrieves the most relevant chunks using cosine similarity: similarity(u,c)=u⋅c∥u∥∥c∥
LLM Response Generation
The retrieved context is passed to the LLM, which generates a precise, context‑aware answer.
Chat Interface
A clean UI enables users to ask follow‑up questions and explore the document conversationally.
Challenges we ran into:
Handling large documents efficiently without losing context Ensuring the LLM stays grounded in retrieved content and avoids hallucinations Choosing the right chunking strategy for better semantic retrieval Optimizing latency for fast responses Managing ambiguous or incomplete user queries gracefully Each challenge pushed us to refine the architecture and improve reliability.
Accomplishments that we're proud of :
Successfully built a fully functional RAG‑based chatbot Achieved accurate, context‑aware responses grounded in the document Designed a smooth user experience for uploading and querying documents Learned and implemented modern LLM techniques in a real project Created a solution that can scale to multiple document types and use cases
What we learned:
Deep understanding of RAG workflows and semantic search Practical experience with embeddings, chunking, and vector databases Importance of prompt engineering for grounded responses How to balance performance, accuracy, and user experience Real‑world limitations and strengths of LLMs
What's next for AI CHAT BOT implementation:
Support for multiple documents and cross‑document reasoning Adding citations to show exactly where answers came from Improving UI with conversation history and document previews Integrating speech‑to‑text and text‑to‑speech for accessibility Fine‑tuning domain‑specific models for enterprise use cases

Log in or sign up for Devpost to join the conversation.