-
-
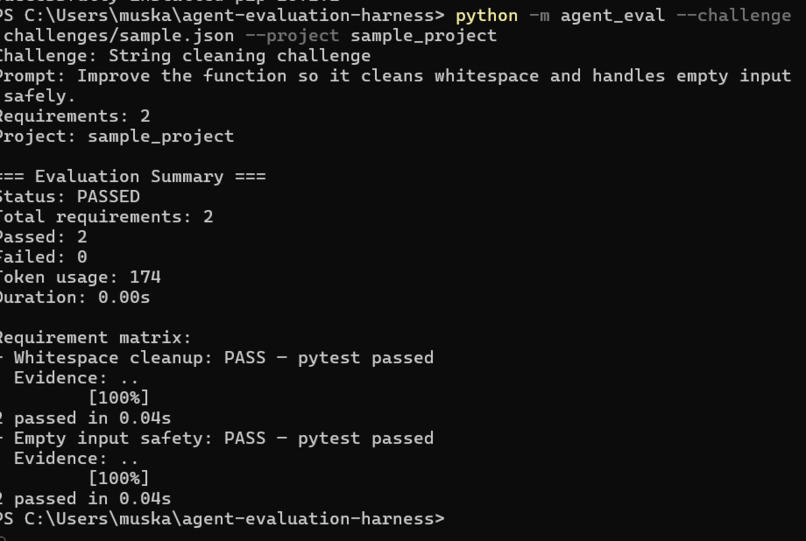
the sample output
Inspiration
AI agents are becoming more powerful, but how do we know if they actually work reliably? A successful demo doesn't guarantee consistent performance in real-world situations. I wanted to explore how developers can evaluate AI agents systematically instead of relying only on manual testing and intuition. That idea inspired Agent Eval Harness.
What it does
Agent Eval Harness is a Python-based project focused on making AI agent evaluation more structured and repeatable. It aims to help developers test agent outputs, assess performance against defined criteria, identify failures, and understand where improvements are needed.
The goal is simple: make it easier to measure AI agent performance and build more reliable AI systems.
How we built it
We built the project around Python and a structured evaluation workflow. The idea is to define evaluation cases, assess outputs against specific criteria, and make the results easier to review.
The project focuses on making evaluation practical for developers who want to test their AI systems as part of their development process. The implementation is available on GitHub for others to explore and build upon.
Challenges we ran into
One of the key challenges was thinking beyond whether an AI agent produces an answer and focusing on how to evaluate the quality of that answer.
AI outputs can vary, and evaluating them consistently is not always straightforward. Designing a useful evaluation process means balancing measurable criteria with the flexibility needed to assess different kinds of tasks.
Another challenge was keeping the project practical and approachable while exploring a problem that is becoming increasingly important in AI development.
Accomplishments that we're proud of
We're proud to have built a project around a problem that deserves more attention: evaluating AI agents, not just building them.
Agent Eval Harness represents a step toward a more systematic approach to testing AI systems. We're also proud to have created an open-source starting point that can be explored, improved, and extended by other developers.
What we learned
We learned that building an AI agent is only one part of the process. Understanding its limitations, testing its behavior, and measuring its performance are equally important.
We also gained a better appreciation for the challenges of creating repeatable evaluations and turning evaluation results into actionable feedback.
What's next for Agent Eval Harness
We learned that building an AI agent is only one part of the process. Understanding its limitations, testing its behavior, and measuring its performance are equally important.
We also gained a better appreciation for the challenges of creating repeatable evaluations and turning evaluation results into actionable feedback. What's next?

Log in or sign up for Devpost to join the conversation.