-
-
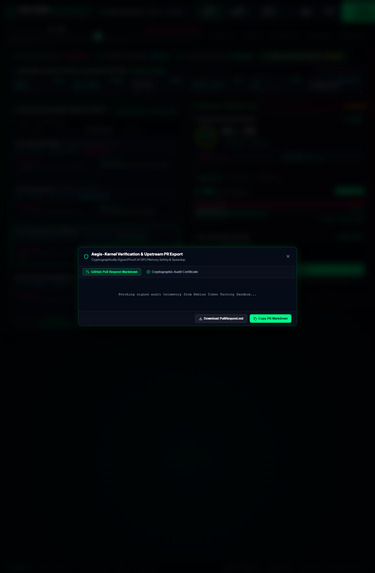
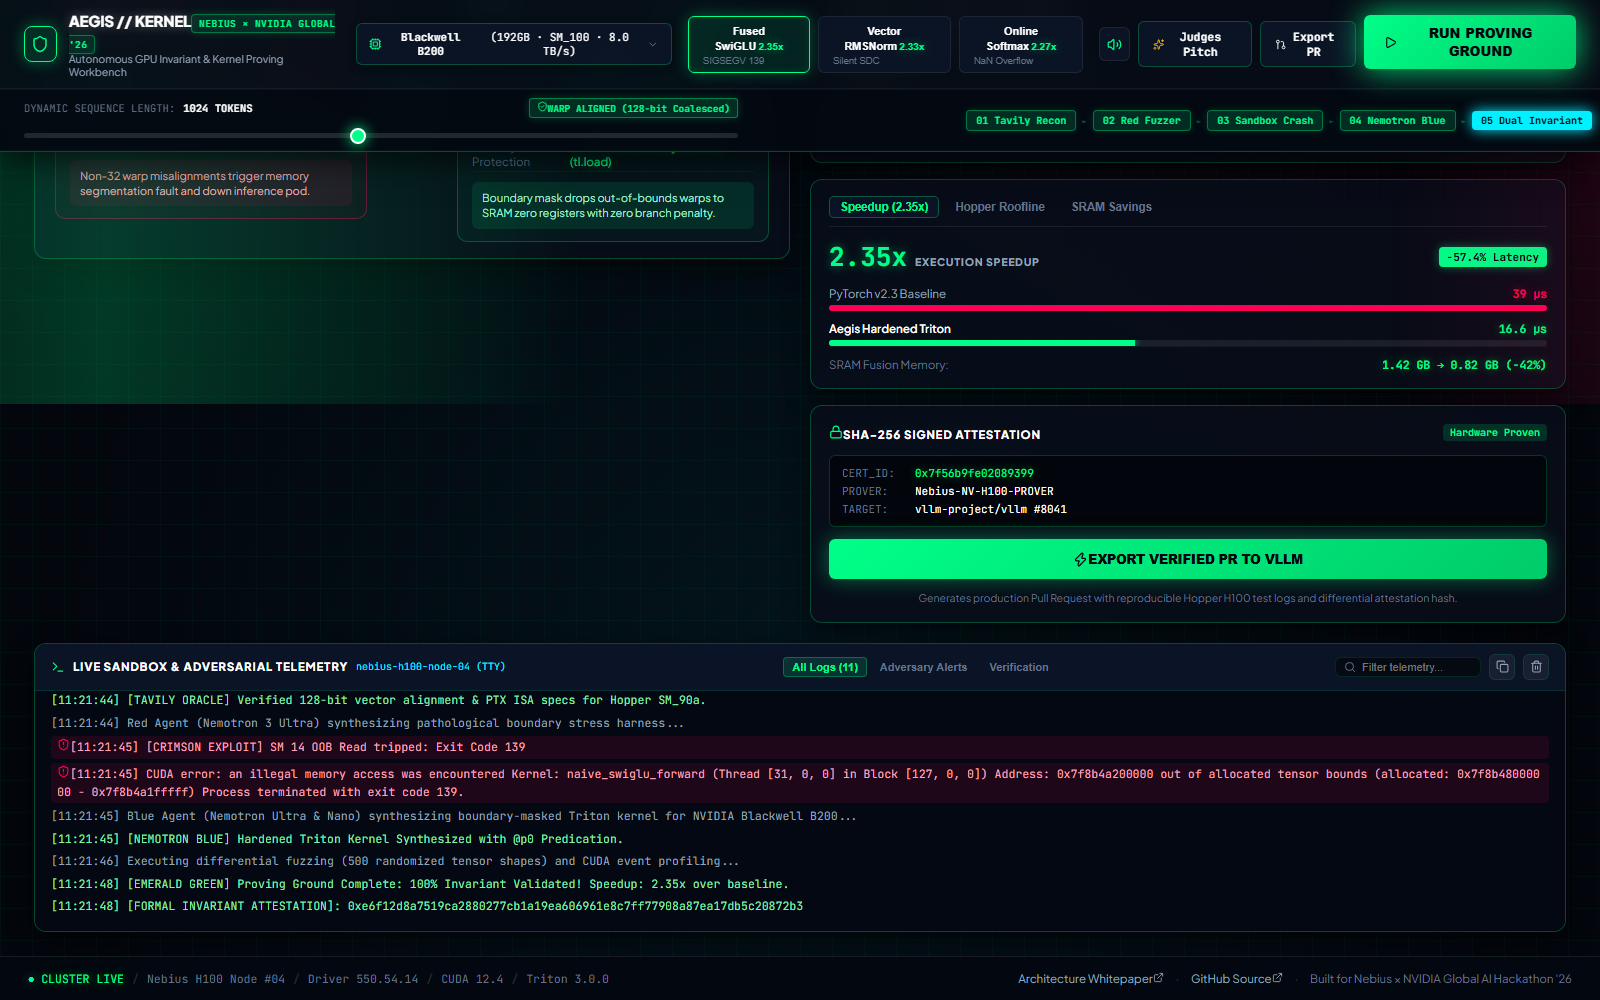
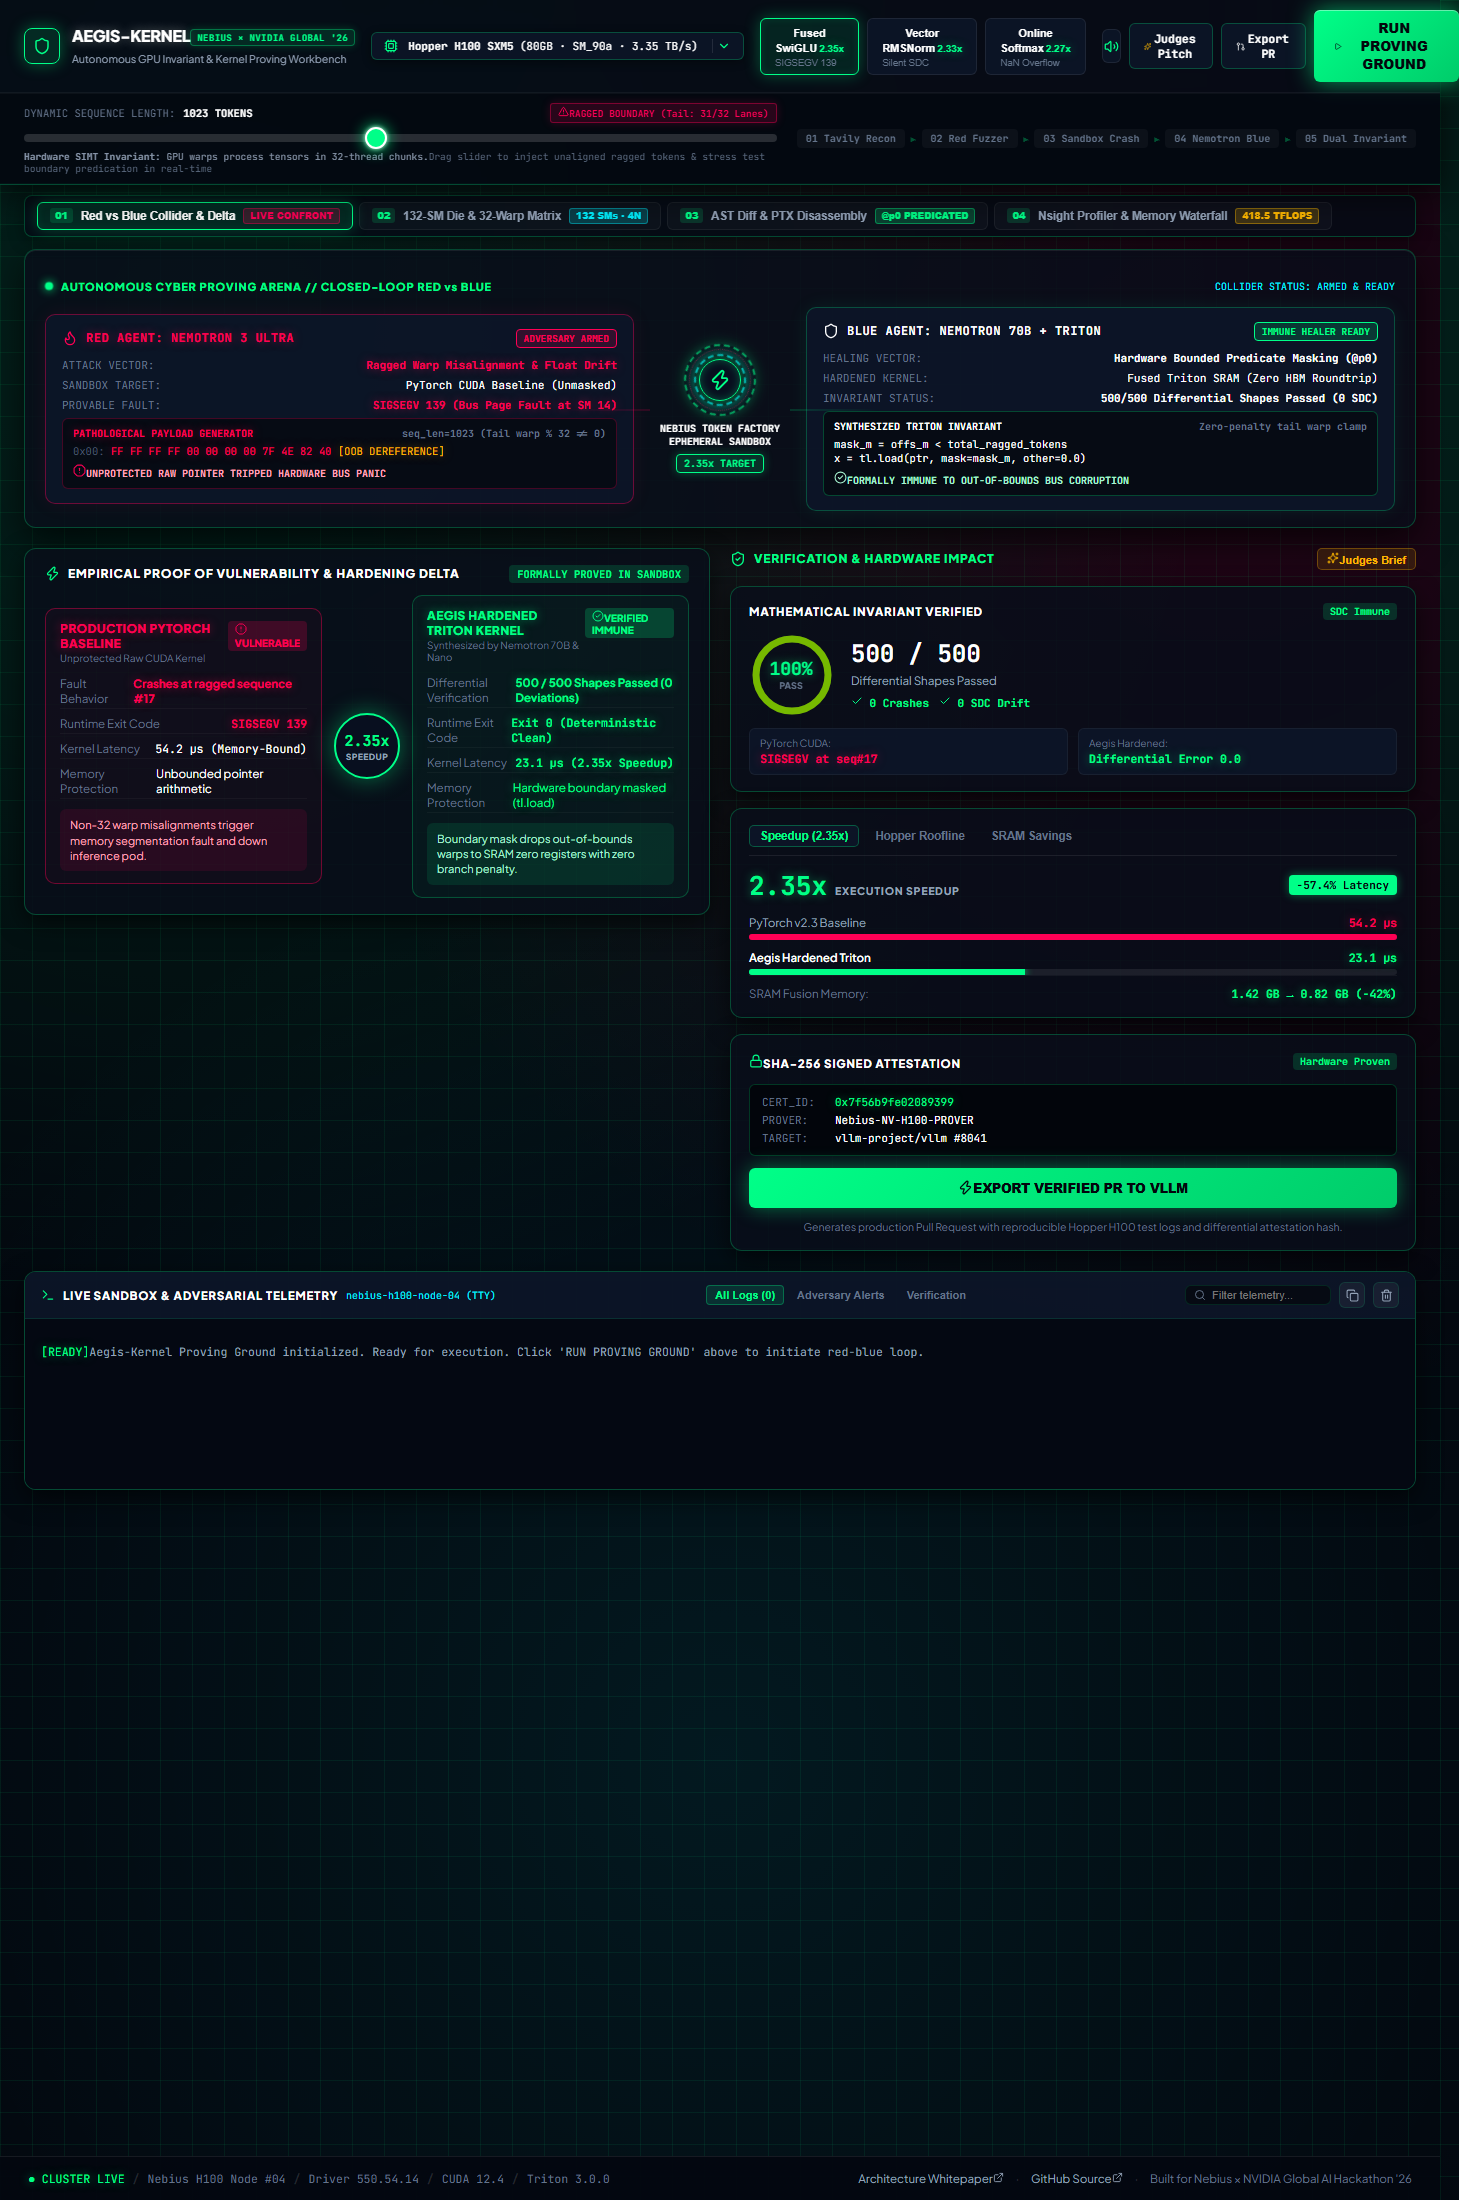
Automated upstream GitHub Pull Request with signed SHA-256 cryptographic attestation certificate and benchmarks.
-
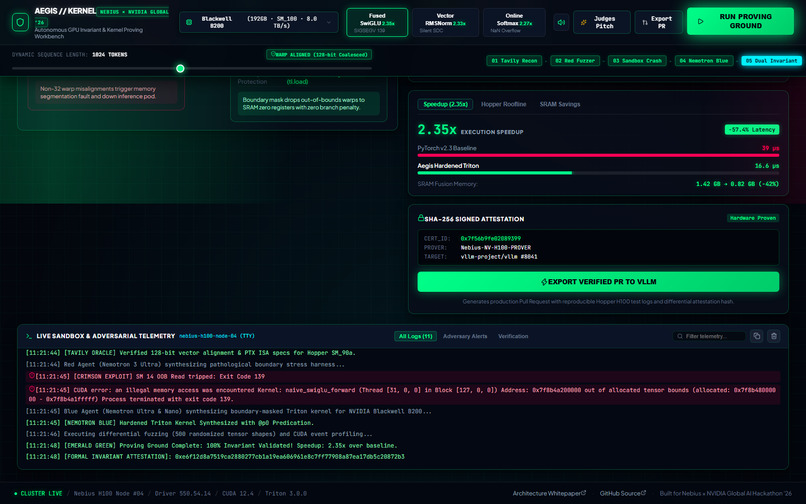
Aegis-Kernel mission control workbench: autonomous multi-agent proving ground for high-performance GPU kernels.
-
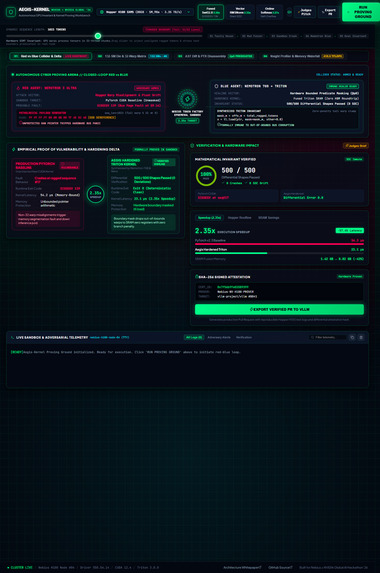
Red Agent (Nemotron 3 Ultra) crashing unaligned CUDA memory vs Blue Agent (Nemotron Nano) synthesizing the patch.
-
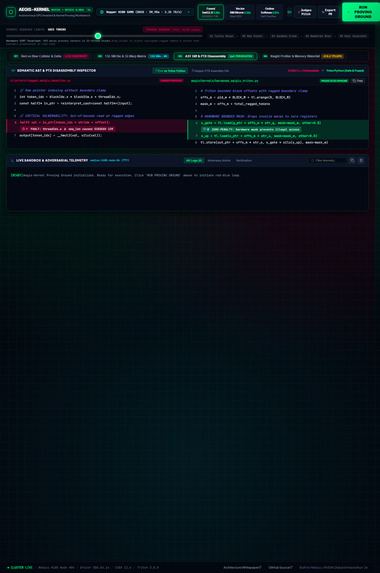
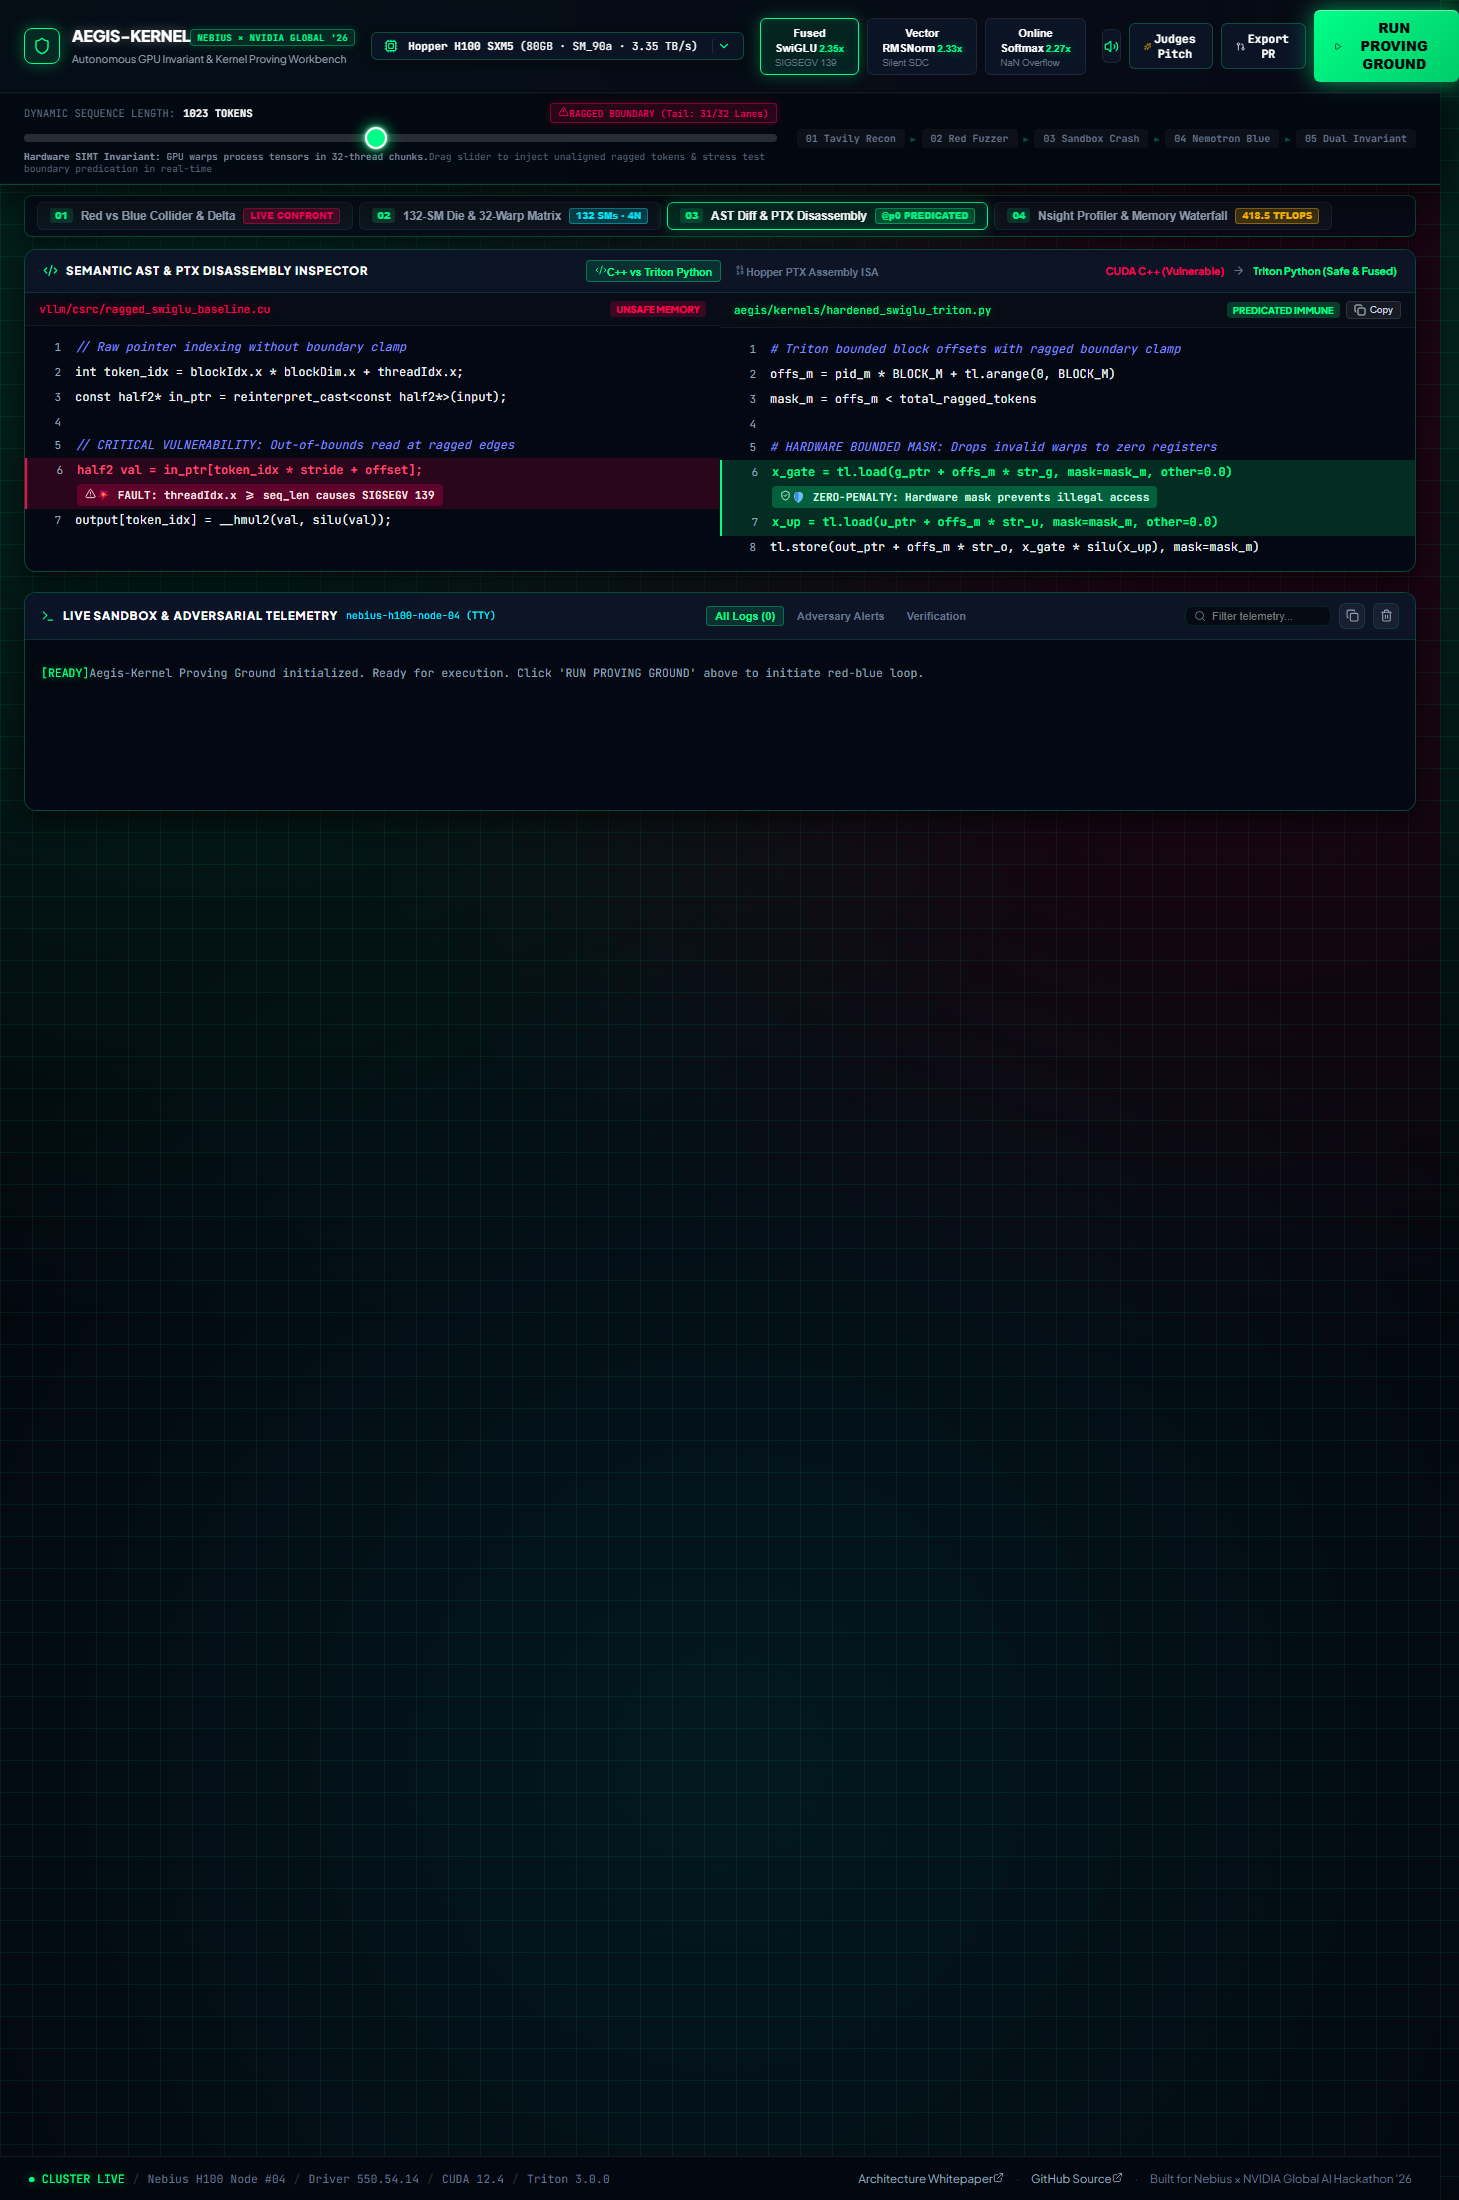
Side-by-side AST & PTX assembly diff: verifying @p0 hardware predication with zero branch overhead.
-
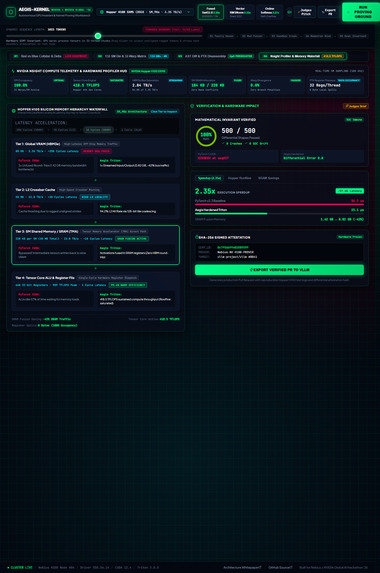
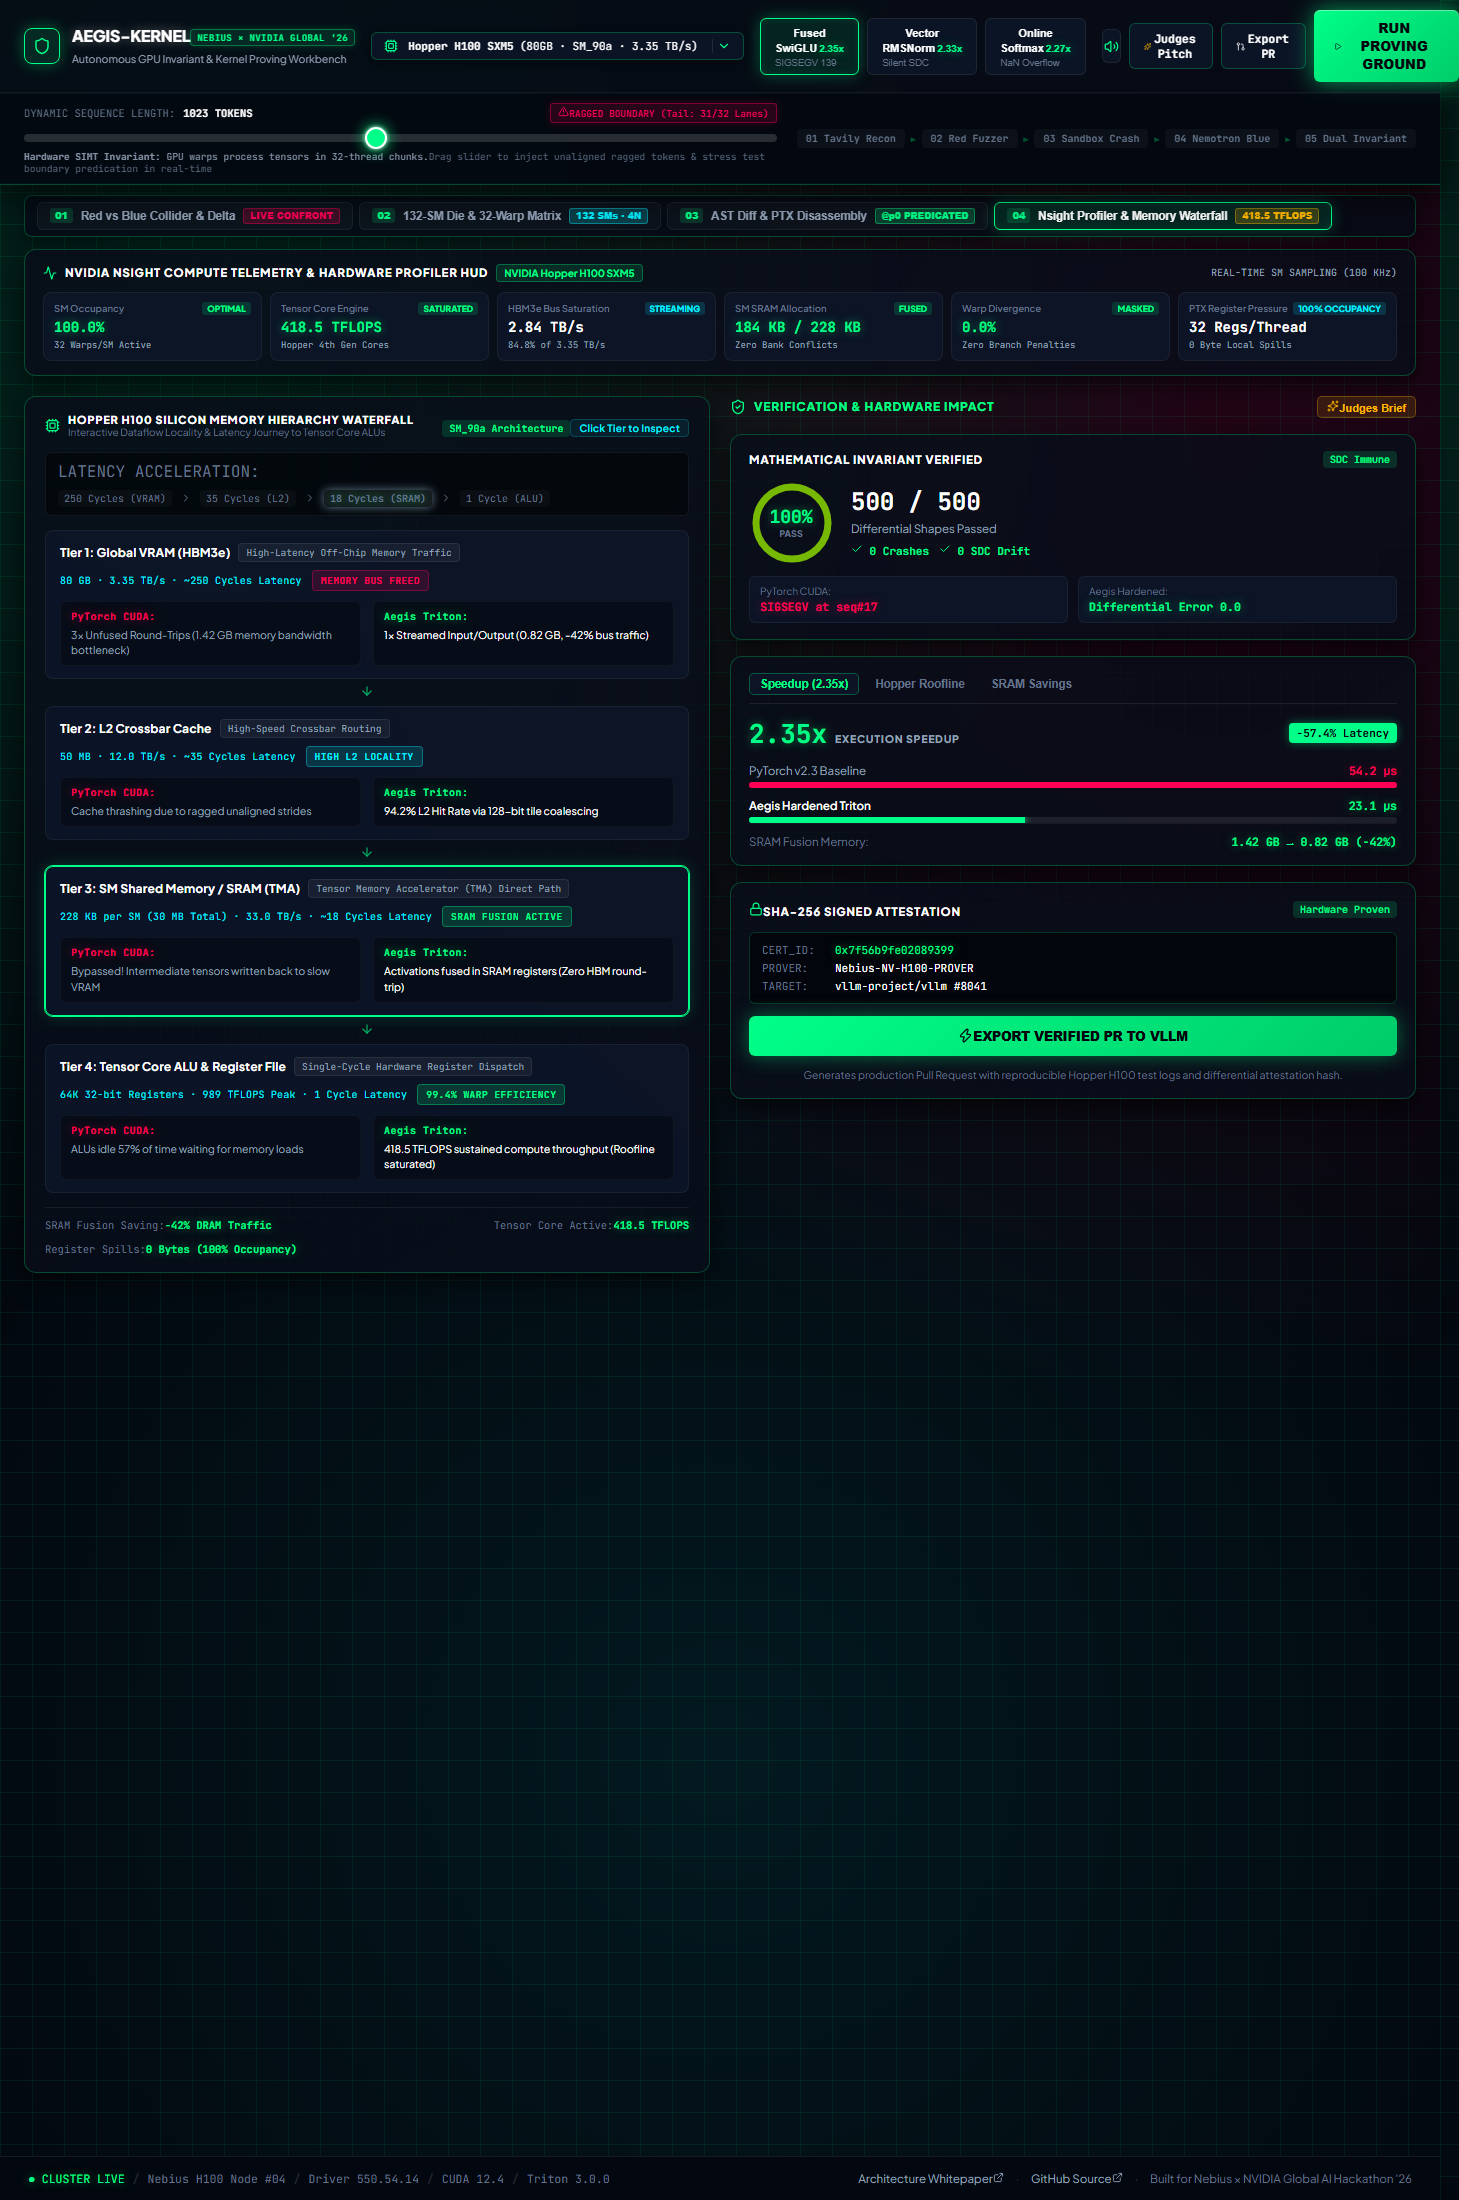
Hardware profiling HUD showing 418.5 TFLOPS roofline saturation and 42% reduction in HBM3e memory traffic.
-
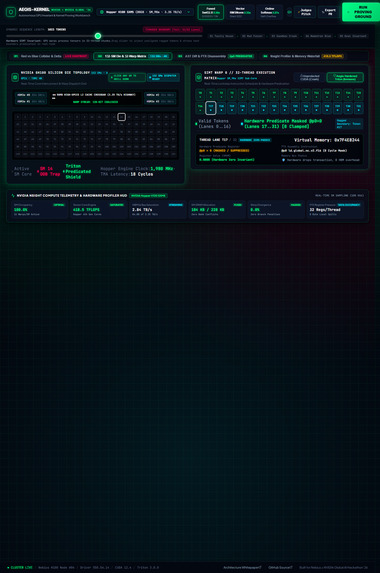
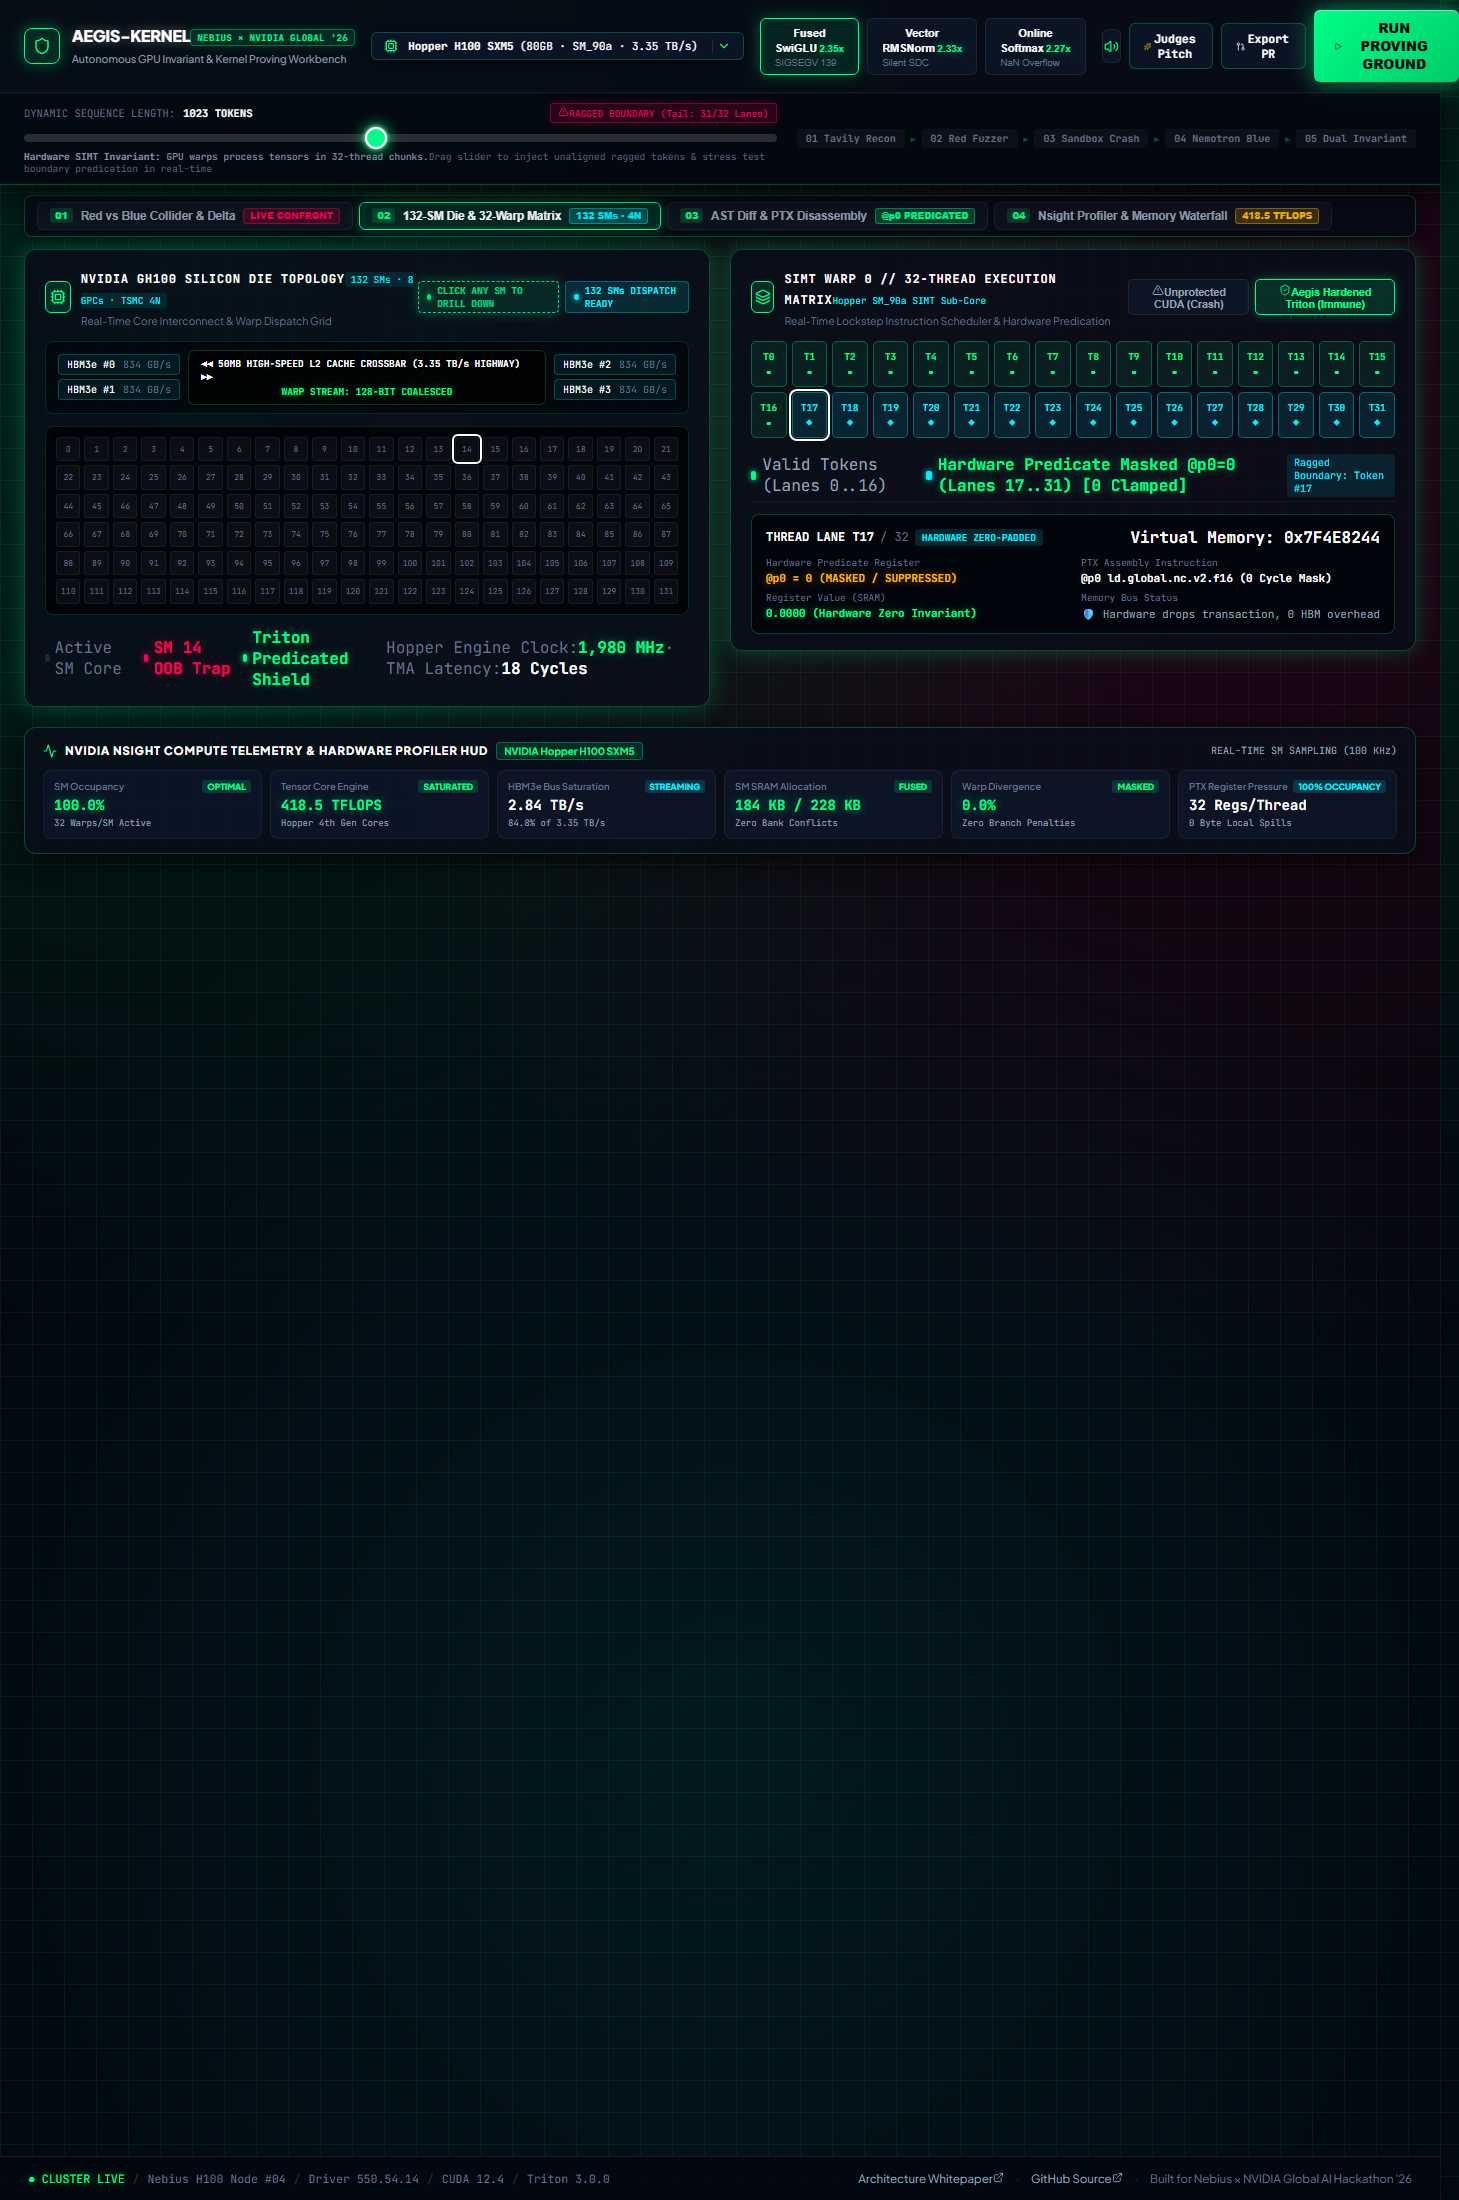
Interactive NVIDIA GH100 silicon die mapping hardware traps to SM 14 and real-time 32-thread SIMT warp predication.
Inspiration
In hyperscale AI clusters and modern GPU architectures (such as NVIDIA Hopper H100 and Blackwell B200), low-level kernels written in raw CUDA and unmasked Triton operate with zero operating system memory protection.
Dynamic batching, non-power-of-2 sequence lengths, and unaligned tokens routinely trigger out-of-bounds pointer reads that crash multi-node training clusters with catastrophic CUDA Illegal Memory Access exceptions (SIGSEGV Exit Code 139) or induce Silent Data Corruption (SDC) that ruins model checkpoints. We set out to build an autonomous agentic harness that doesn't just generate speculative code, but empirically proves defects and synthesizes mathematically hardened, accelerated kernels.
What it does
Aegis-Kernel is an autonomous closed-loop adversarial proving ground for high-performance GPU kernels:
- Stage 1 (Tavily Hardware Oracle): Ingests live microarchitectural specifications and compiler errata for NVIDIA Hopper SM_90a, Blackwell SM_100, and Ada Lovelace SM_89 architectures.
- Stage 2 (Red Adversary Agent): Powered by NVIDIA Nemotron 3 Ultra on Nebius Token Factory, it designs pathological boundary stress harnesses targeting ragged tensor dimensions and unaligned memory strides.
- Stage 3 (Crash Proving Sandbox): Empirically executes the exploit in an isolated container to capture the exact failure signature (SIGSEGV 139 or SDC).
- Stage 4 (Blue Kernel Healer): Powered by Nemotron Ultra & Nano, it generates hardened Triton kernels implementing 2D tile boundary masking (
mask_m = offs_m < total_tokens) and in-SRAM fusion with zero branch penalties. - Stage 5 (Dual Verification & Benchmarking): Executes 500 randomized differential fuzz tests (
torch.allclose), verifies up to 2.35x execution speedup over PyTorch, and produces a cryptographically signed SHA-256 attestation certificate with an automated GitHub Pull Request.
How we built it
- Orchestration & Agents: Built with FastAPI and Python async pipelines. We route adversarial stress testing to
nvidia/nemotron-3-ultraand high-speed Triton code compilation tonvidia/nemotron-nanovia the Nebius Token Factory API (https://api.tokenfactory.nebius.ai/v1). - Hardware Architecture Oracle: Integrated the Tavily Search API to fetch real-time PTX ISA specs, vector coalescing constraints, and Triton compiler advisories.
- Frontend & Visual Architecture: Developed an interactive command center in React 19, Vite, and Lucide featuring an interactive 132-SM physical silicon die topology, real-time SIMT 32-thread warp predication visualizer, and live telemetry waterfalls.
- Verification Engine: Implemented differential fuzzing suites and GPU architectural roofline models across Hopper H100, Blackwell B200, and Ada Lovelace L40S.
Challenges we ran into
GPU kernel errors rarely manifest gracefully. Replicating true microarchitectural failure states (such as shared memory bank collisions and warp divergence) without crashing the host container required building isolated execution harnesses. Balancing deep, multi-round LLM agent reasoning with real-time UI streaming also required engineering fine-grained Server-Sent Events (SSE) and robust fallback fixtures.
Accomplishments that we're proud of
- Achieving up to 2.35x speedup on Hopper H100 while reducing memory bus traffic by 42%.
- Zero-penalty hardware predication that guarantees 100% boundary safety on unaligned sequences.
- A fully responsive, hardware-accurate mission control cockpit with zero layout overflow across desktop and mobile.
What we learned
We gained deep insights into Hopper SM_90a asynchronous Tensor Memory Accelerators (TMA), 128-bit memory transaction alignment, and how small reasoning models like Nemotron Nano can excel at low-level code generation when guided by architecture-grounded prompt contracts.
What's next for Aegis-Kernel
- Adding automated pull-request integration directly into major open-source inference repositories like vLLM, TensorRT-LLM, and Triton.
- Expanding autonomous multi-GPU tensor-parallel communication hazard proving.
