-
montage-examples.png
-
montage-examples.png
-
montage-examples.png
-
montage-examples.png
-
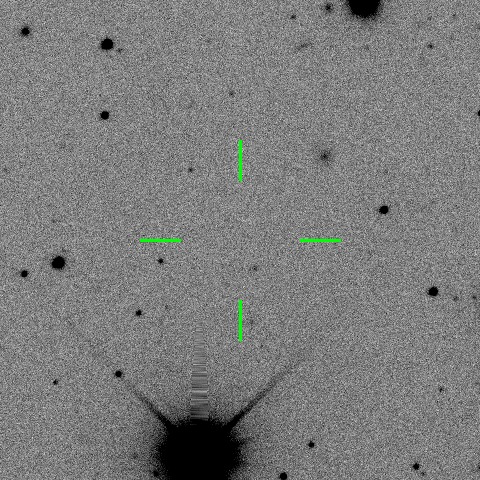
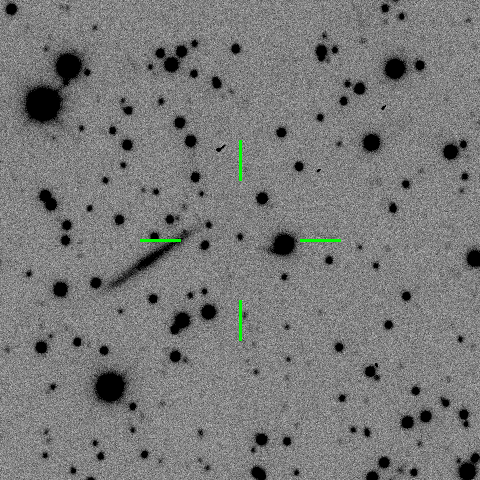
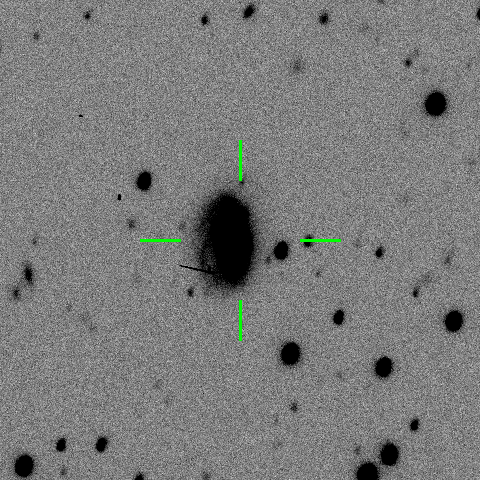
montage-top-candidates.png
Active Asteroids ML
Detecting comet-like activity in NASA citizen-science cutouts — an open, honest ML baseline for the Active Asteroids (Zooniverse) volunteer task: is the central object active?
A small public re-implementation-style baseline in the spirit of the team's own TailNet prototype — deliberately simple, fully auditable, built in a 2-day sprint on public data.
Results (all real, run on free Kaggle T4 GPUs)
| Model | Split | ROC-AUC | PR-AUC | R @0.5 | P @0.5 | Recall @top10% |
|---|---|---|---|---|---|---|
| Logistic regression (8 features) | Val | 0.526 | 0.258 | 0.30 | 0.21 | ~0.10 |
| Logistic regression (8 features) | Test | 0.532 | 0.219 | 0.21 | 0.21 | ~0.10 |
| ResNet18 fine-tune | Val | 0.603 | 0.358 | 0.30 | 0.40 | 0.18 |
| ResNet18 fine-tune | Test | 0.650 | 0.279 | 0.15 | 0.29 | 0.15 |
- Logistic regression is near-random (ROC-AUC ≈ 0.53) — cheap hand features cannot capture tail/coma morphology. This is the honest baseline the CNN has to beat.
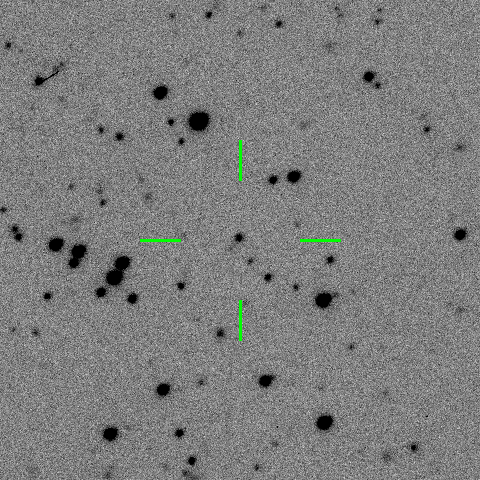
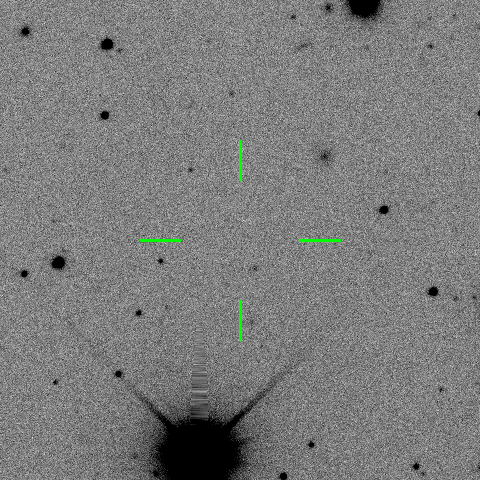
- ResNet18 is a real but modest gain — it ranks genuinely known-active objects at the top of its predictions: Chariklo (10199), 2060 Chiron, 2014 OG392, 2018 VL10, 2015 TC1.
- Why it's weak (honest finding): trained on textbook-activity teaching cutouts, evaluated on the general stream (different objects, epochs, SNR). Best checkpoint = epoch 1; validation precision-recall never improved → a clear train/eval distribution shift.
- Error analysis: a cluster of
no-matchcutouts scored p>0.93 violates the "galaxy / CCD artefact" false-positive hypothesis — and doubles as an honest shortlist of uncatalogued candidate objects worth a second look.
Full metrics, thresholds, and methodology in report.md.
Dataset
- 2,054 DECam cutouts (480×480 px)
- 1,315 training positives — CSB00 "Training Set 1" teaching cutouts (all volunteer-labeled active)
- 66 eval positives — catalog-matched subjects from the general stream (split ~50/50 val/test)
- 673 negatives — no-catalog-match cutouts (60/20/20 split)
- Auto-labeled by object identity (packed MPC designation in the subject filename), from a 25-entry known-active catalog distilled from the team's discovery papers (arXiv:2403.09768).
- Contamination-free: the training set is never in val/test; eval positives are matched only via the published catalog.
Reproduce
pip install -r requirements.txt

# 1. enumerate Zooniverse subjects -> cutouts -> labeled splits
python scripts/build_dataset.py

# 2. logistic-regression baseline (local CPU)
python scripts/baseline.py

# 3. ResNet18 fine-tune (GPU preferred; Kaggle kernel ready)
python scripts/train_cnn.py --epochs 8

# 4. run a checkpoint on new cutouts -> top-k candidates
python scripts/infer.py --checkpoint runs/cnn_best.pt
- Kaggle kernel:
zamirmemon/active-asteroids-resnet18-baseline - Kaggle dataset:
zamirmemon/active-asteroids-ml-cnndata
Layout
scripts/
  step0_probe.py     Path B gate — anonymous project/workflow/subject info
  build_dataset.py   enumerate subjects -> cutouts -> catalog labels -> splits
  baseline.py        logistic regression (8 hand features)
  train_cnn.py       ResNet18 fine-tune, balanced sampler, best-by-val-AP
  infer.py           run checkpoint on new cutouts -> top-k candidates
  assemble_splits.py rebuild splits from downloaded raw cutouts
  make_kaggle_data.py stage relative-path splits + images for Kaggle upload
  scan_sets.py       identify subject sets / catalog-match candidates
data/
  catalog/           CSV of known-active objects (labels, provenance)
  raw/               cutouts (not committed; ~0.8 GB)
  splits/            train/val/test manifests + prediction/candidate exports
report.md            full write-up, metrics tables, threats to validity
requirements.txt
kaggle/              Kaggle kernel metadata + dataset staging scripts
Scope & honesty
- Built in a 2-day sprint as a portfolio/ad hoc reference baseline — not competitive with, or endorsed by, the Active Asteroids team's science-grade TailNet.
- Not peer-reviewed, not submitted to arXiv. Evaluated only against public volunteer labels.
- The eval-positive pool is small (~25 catalog objects) — PR-AUC estimates are noisy; we report both ROC-AUC and PR-AUC across thresholds to be transparent about that.
DoD
- [x] Public pipeline + CNN baseline + inference + notebook
- [x] Honest rare-class evaluation (recall/precision, thresholds, @top-10%)
- [x] Error analysis + candidate exports
- [x] report.md with all real metrics
- [ ] Volunteer badge / Talk forum post (user-side follow-up)

Log in or sign up for Devpost to join the conversation.