https://hack-the-6ix.netlify.app/
Inspiration
We've mentioned going to Japan to more friend groups than we can count (but somehow none of us have ever gone).
What it does
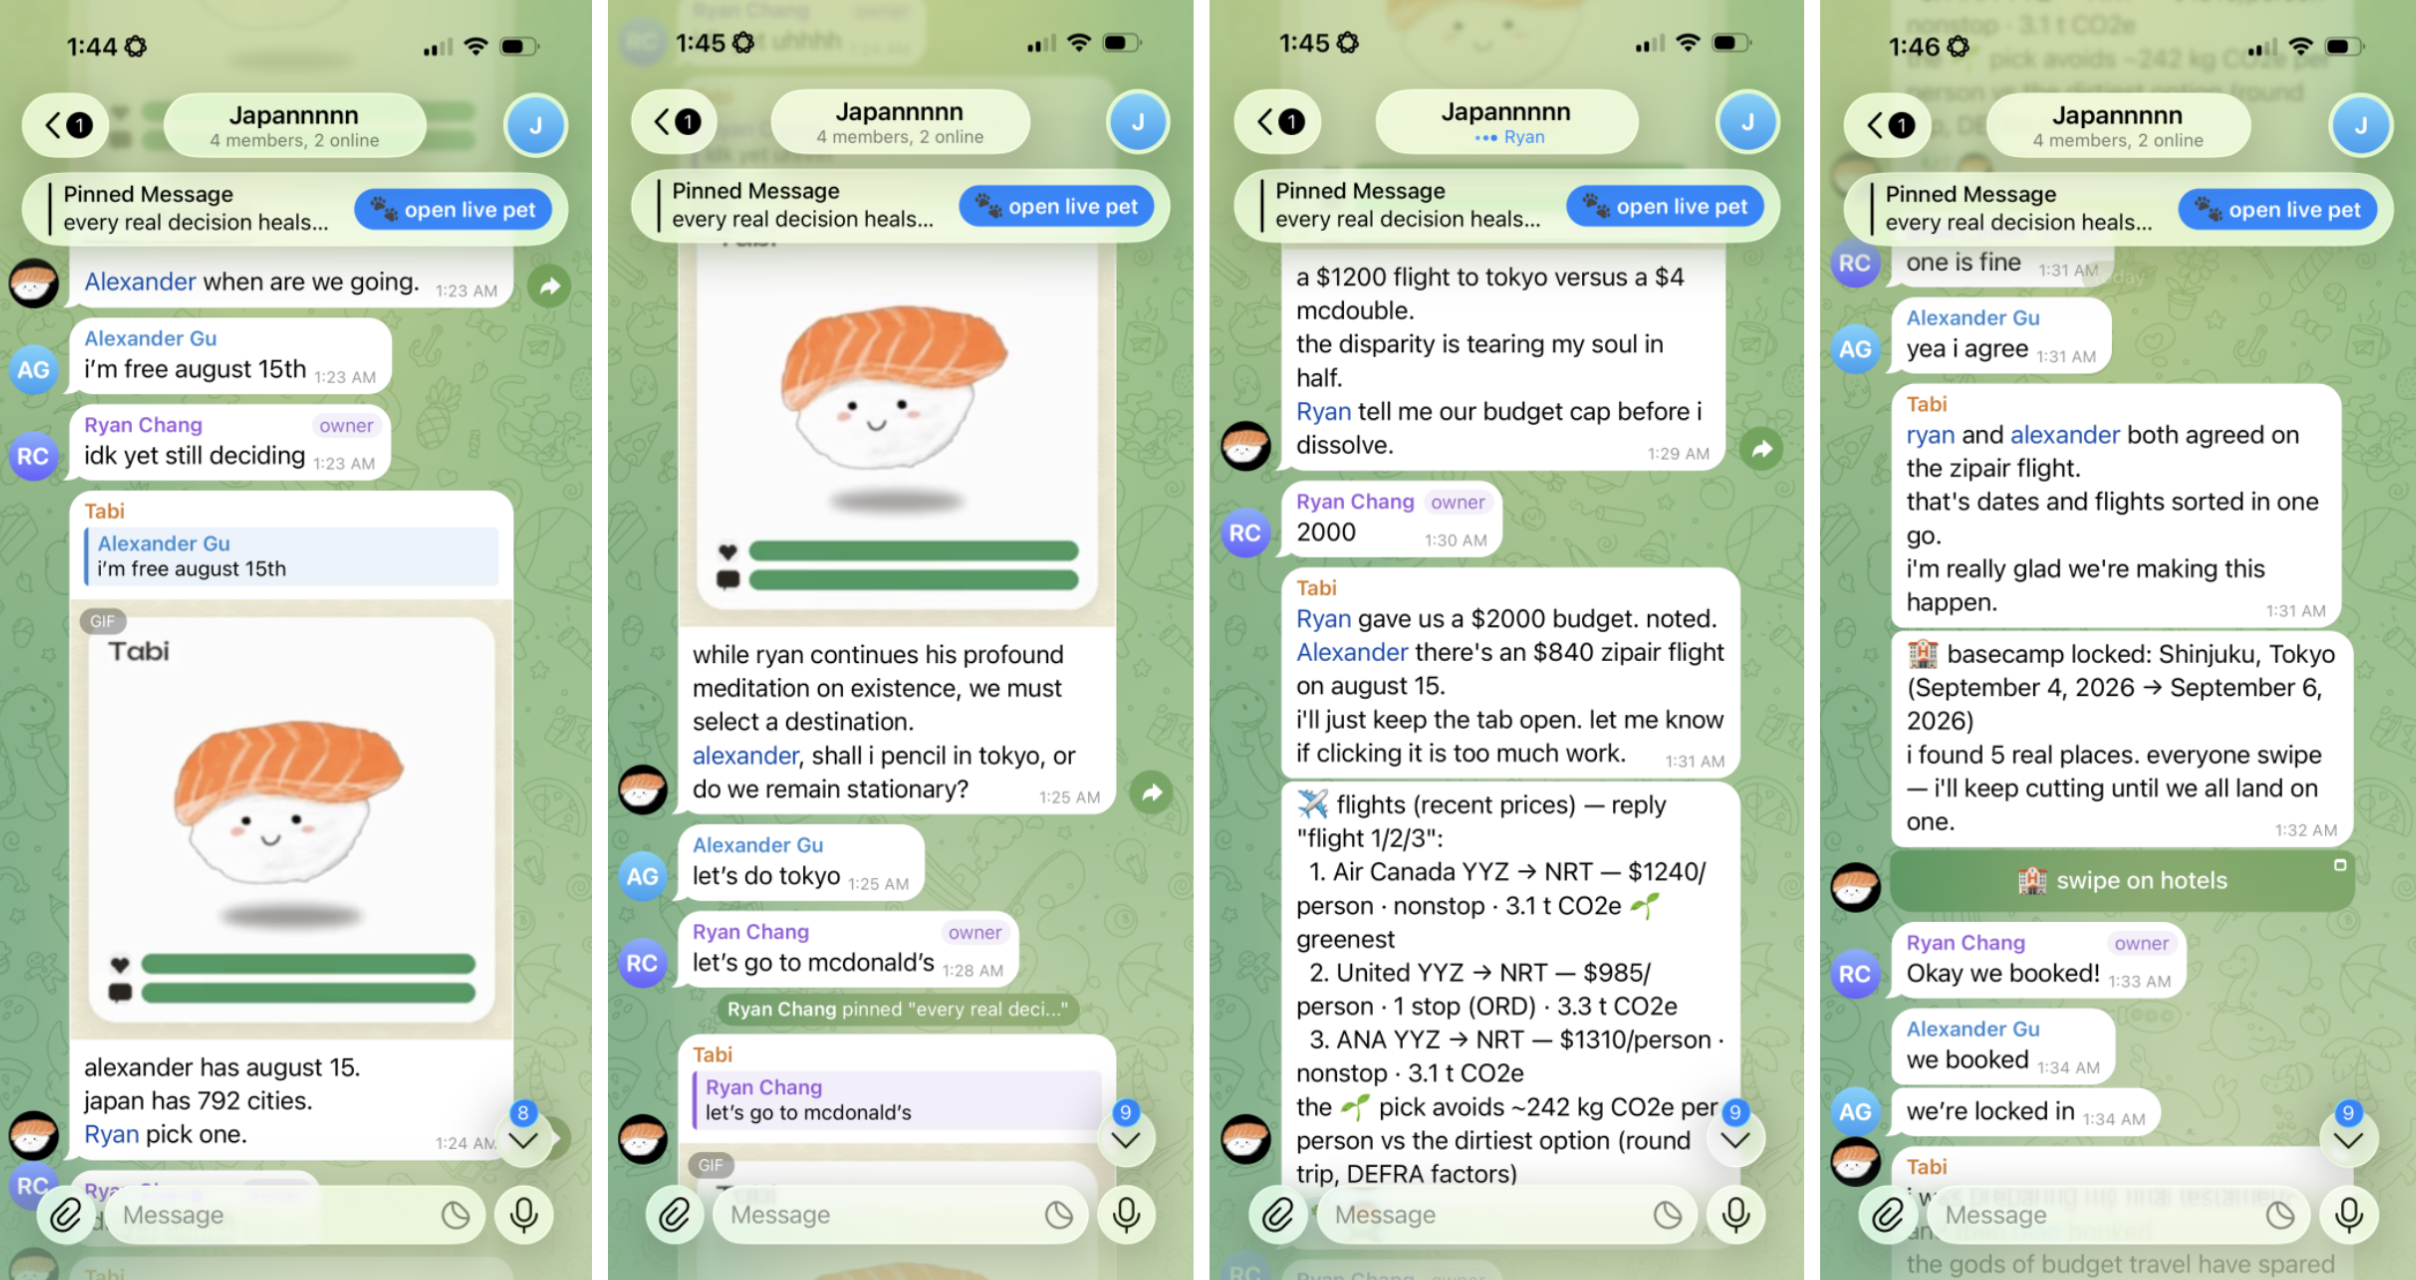
Your trip to Japan is NEVER going to happen. Everyone means it, nobody moves, and slowly it becomes a fantasy. Tabi makes the stalling visible: a pet named Tabi lives in your group chat, and it will literally die if your group doesn't go.
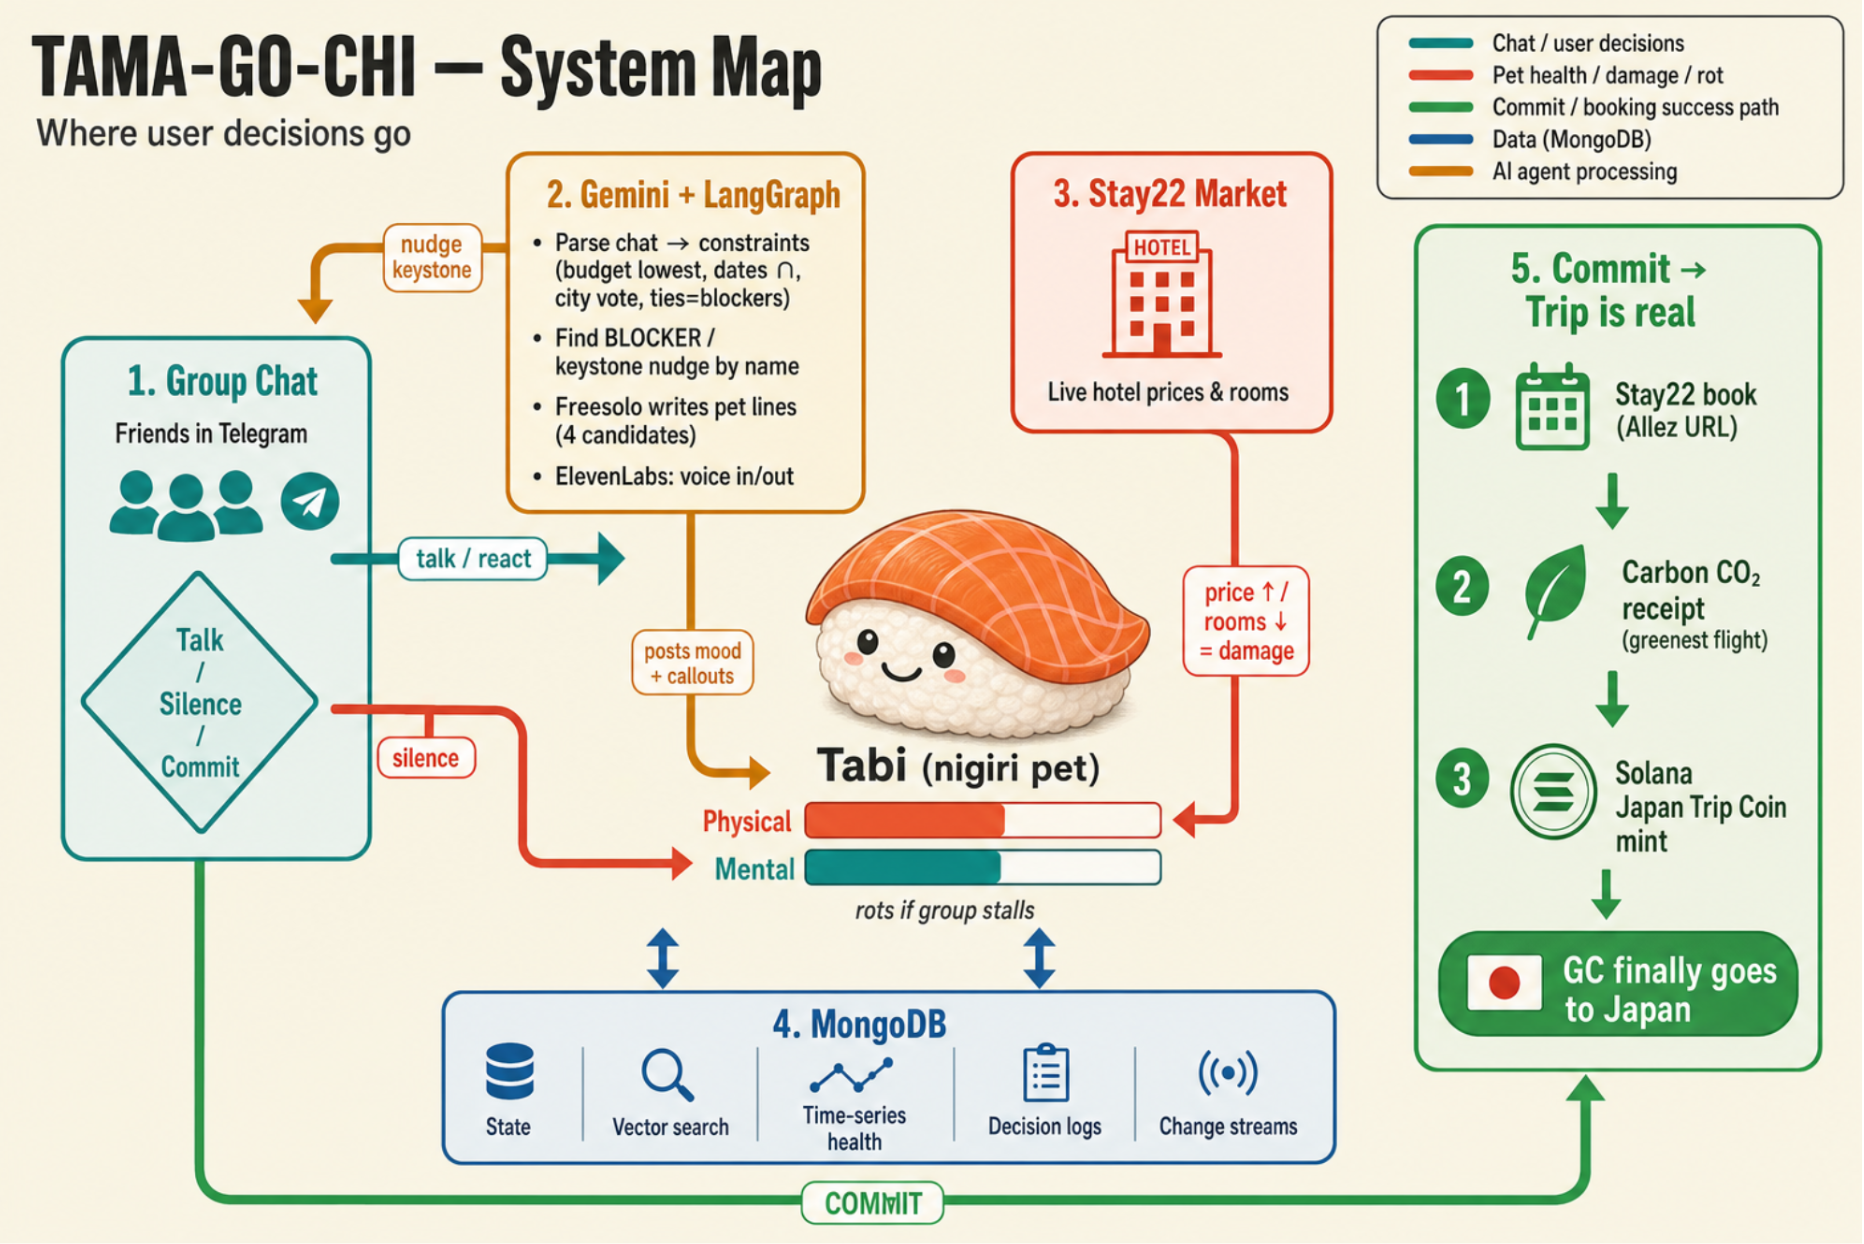
But beyond the emotional manipulation, Tabi is a real agent. It reads your trip talk, assembles one plan out of everyone's contradictory answers, and points out the real BLOCKERS — if freaking Alex keeps being a cheapo about the budget, Tabi calls him out by name.
Commit to the plan, and the trip becomes real ✨. A room booked through Stay22, and a Solana coin minted to seal it. Tabi is also ECO-FRIENDLY: every flight and transport option is carbon-scored so the group takes the cleanest route, with the CO₂ saved tracked on a shared ledger. Go to the land of ANIME with your friends!
PIPELINE
- Add Tabi to your group chat →
- Talk about the trip like you normally would →
- Tabi creates a real plan →
- It proposes, the group reacts, and it fixes whatever's stuck (calling out the holdout by name) →
- commit or reiterate (restart from 2) →
- Room booked, flights green, your GC is going to Japan with the cheapest & most eco-friendly deals.
How we built it
Gemini — an AI teammate that coordinates real people
Parses raw chat into structured trip constraints, reconciled with named rules: budget = lowest cap, dates = intersection, city = plurality, ties = blockers — turning five conflicting opinions into one plan without a human in the loop. A LangGraph supervisor drafts 4 candidate messages, self-scores each, and only sends the winner — every line the pet says is explainable by its score. It diagnoses the one binding blocker, profiles every member from the chat, and nudges the one person whose answer unblocks the plan by name, then removes the objection with real deterministic actions: dealing the hotel card deck, posting flight options, posting the itinerary.
MongoDB — the product builds its own research dataset
Every agent decision — context, all 4 candidates, scores, the pick — is logged as a labeled example, and an outcome loop is wired to label whether the nudge landed: a labeled dataset no one else has, and the one our Freesolo model was trained on. Atlas also holds the member registry for real @-mentions, preference profiles, trip state, and pet health across redeploys. Every write fail-open — a database hiccup can never kill a trip.
Stay22 — live inventory is the pet's body
The bot polls Stay22's v2 API for the group's reconciled city and dates: price spikes and sell-outs deal damage via a delta formula — capped damage, uncapped heal, so a good market week visibly heals the pet. No hotel list mid-game: inventory appears only as vital signs, then a swipeable card deck, then the booking. On commit it re-queries live, ranks by rating within budget × guests × nights, and posts the Allez URL verbatim from the API — affiliate attribution intact, real commission on every booking.
Freesolo — we trained the pet's brain ourselves
Full post-training ladder on Qwen3.5-4B: SFT → on-policy distillation → GRPO, with guided-decoding JSON, trained on the dataset our own product generated. The GRPO reward is verifiable — did the line address the group's real blocker? — with a KL leash + length penalty so the model can't cheat by nagging or rambling. We caught distillation collapse mid-training (degenerate loops at greedy decoding), diagnosed it in the traces, and re-laddered GRPO from the SFT checkpoint. Result on held-out data: frontier model zero-shot 0.086 gold-F1, 0% pet-voice. Our 4B: 0.33 gold-F1, 96% pet-voice, 100% schema-valid — ~4× the frontier, and the live pet runs on it right now.
ElevenLabs — a pet you can actually talk to
Tabi speaks its actual line in a mood-matched voice — frail when dying, bright when the trip's alive — saved for story moments like the deathbed plea, never spam. Two-way: voice notes are transcribed with Scribe, run through the identical pipeline as text, and answered out loud.
Carbon — every booking gets a carbon receipt
Flights are scored locally for CO₂e against cited DEFRA 2024 factors with EPA equivalencies — greenest route surfaced by default. Avoided CO₂ accrues on a shared group ledger in the trip summary: "142 miles not driven."
Solana — proof the trip actually happened
Commit mints a "Japan Trip Coin" — an SPL token on Solana devnet, named for the trip ("Osaka · Apr 12–18"), with coin art and an Explorer link. Additionally includes the time it took to book the trip and the person who slacked off the most according to Tabi.
Auth — a public bot that can't drain our keys
Tabi is a public Telegram bot — anyone can find her and add her to a chat. Unprotected, every stranger's message would burn our Gemini, Stay22, and ElevenLabs quota. So access is gated: only authorized groups get the full pipeline — everyone else gets politely turned away before a single API call fires. The keys stay safe, the demo stays alive.
Challenges we ran into
Reconciling five people who all "agree" but actually don't — turning contradictory chat into one structured plan without a human in the loop was the hardest engineering problem in the project. Mid-training, our distillation stage collapsed — the model fell into degenerate loops at greedy decoding. We diagnosed it in the traces, re-ran GRPO from the SFT checkpoint, and shipped the fixed model. And reward design: our first reward could be gamed by nag-spam, so we adversarially tested it and added a KL leash + length penalty before trusting a single number it produced.
Accomplishments that we're proud of
A 4B model trained on data our own product generated about itself, beating a frontier model ~4× on held-out data (0.33 vs 0.086 gold-F1, 96% vs 0% pet-voice) — and it's running the live pet right now. An agent that finds the one person blocking the trip and nudges just them, by name — instead of spamming the whole chat. And a pet voice that's genuinely charming and a little heartbreaking — not a notification with extra steps.
What we learned
The best training data isn't scraped; it's generated by the product itself: logging every decision with its candidates, scores, and real outcome gave us a labelled dataset no one else has. Simple conversational logic with a strong personality reads as more "alive" to users than deeper reasoning would.
What's next for Tabi
Making pet updates fully live with MongoDB change streams instead of polling. Expanding tool-calling into a full voice-driven booking flow. Building a simulated friend group — keystone, anchor, flake personas — as a proper self-play training environment for Freesolo.
Built With
- claude
- css
- docker
- elevenlabs
- fastapi
- freesolo
- gemini
- html
- javascript
- mongodb
- python
- typescript


Log in or sign up for Devpost to join the conversation.