-
-
Poster
Inspiration
Many industries and individuals suffer from a productivity bottleneck caused by the limited number of document summaries. Text summarization, a type of natural language processing, can eliminate this problem by instantly providing readers with critical details from the document in question. With these summaries, readers can rapidly determine a document’s relevance or cut out needing to read it altogether. And text summarization can be applied to a broad range of document types, including news articles, books, movie scripts, scientific journal articles, and electronic health records. Given its potential use cases, advancements in this field could revolutionize the legal, pharmaceutical, and medical industries. Lawyers could extract the necessary information from long legal judgments at astonishing speed. Pharma company employees could rapidly power through complicated government regulatory documents and journal articles. And healthcare providers could synthesize clinical data and medical research publications at a level previously impossible, allowing them to provide better care.
What it does
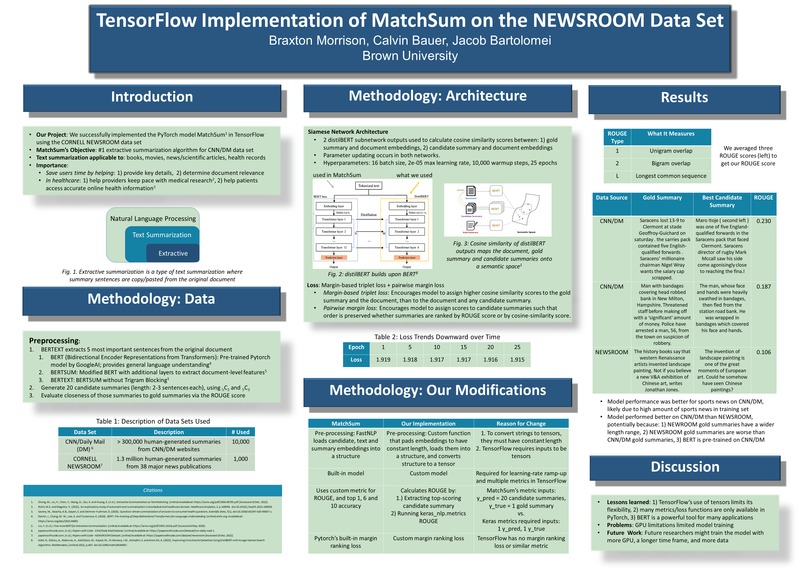
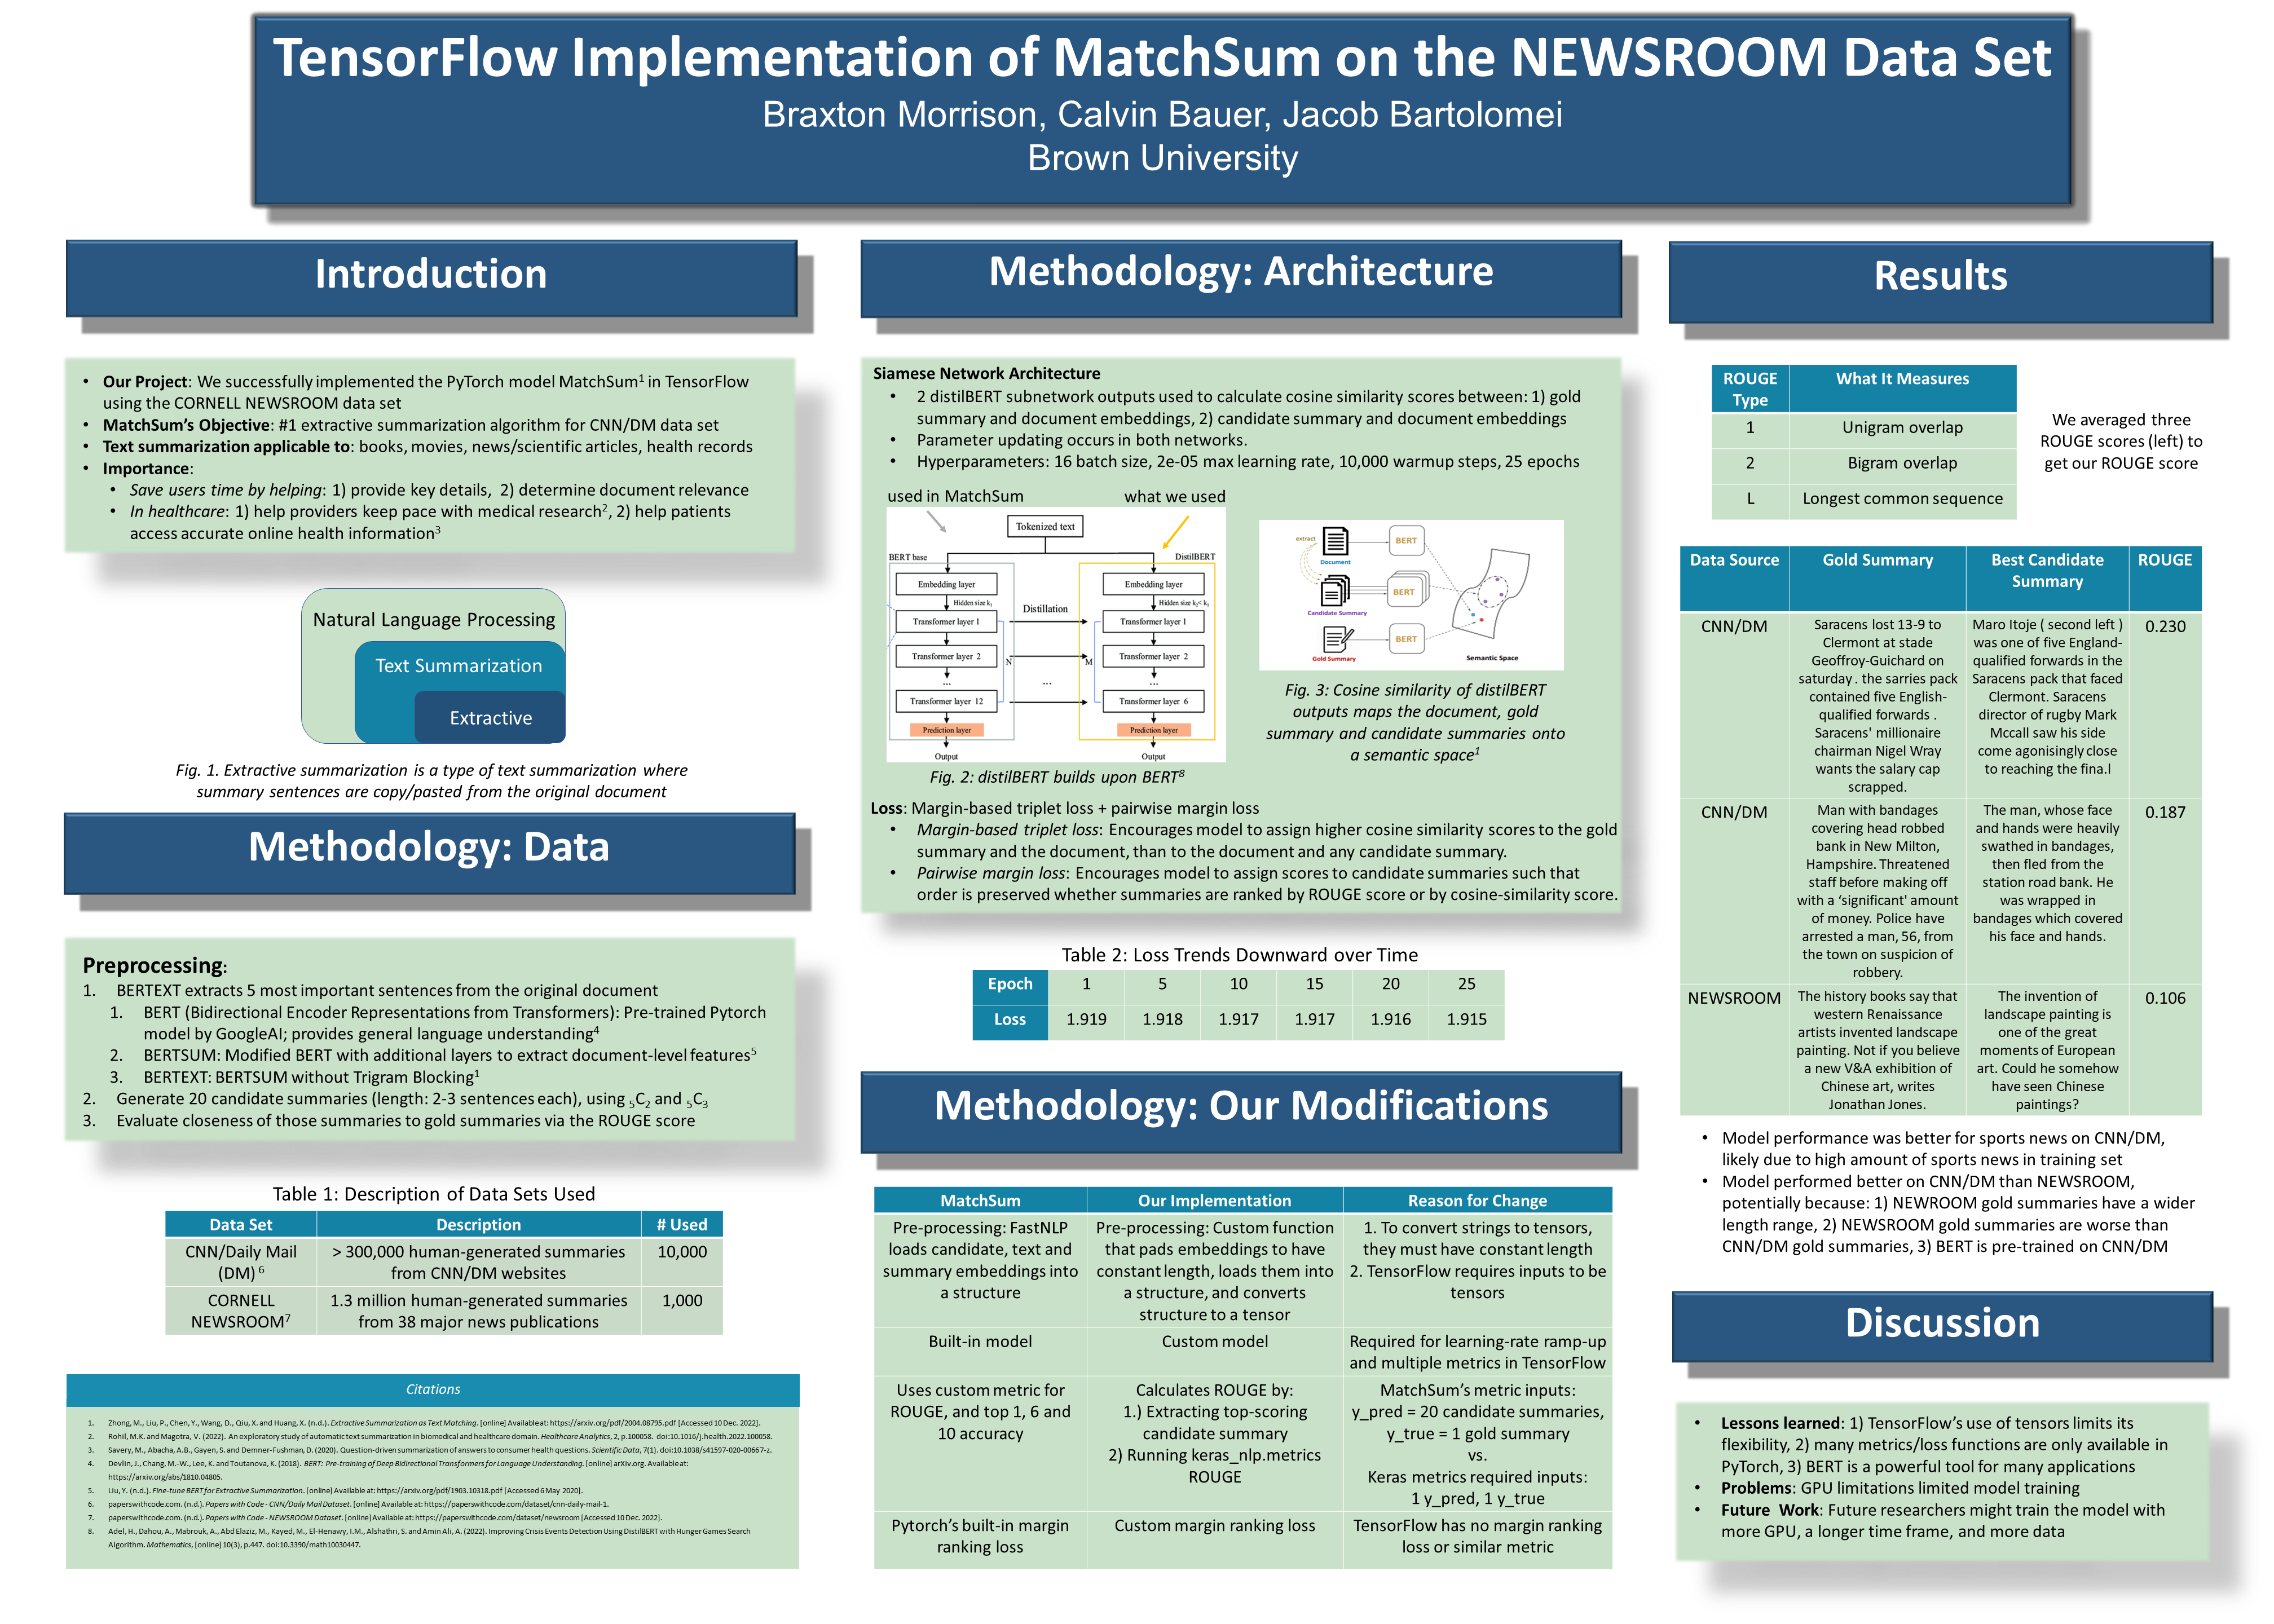
Our model builds upon MATCHSUM, a PyTorch text summarization model ranked #1 globally for summarizing CNN/DM (Cable News Network/Daily Mail) news articles. Our implementation primarily diverges from the original MATCHSUM in that we modified pre-processing and network architecture to translate it into TensorFlow. We also substituted DistilBERT for BERT to increase model training efficiency and trained it using the CORNELL NEWSROOM data set.
How we built it
We constructed a “Siamese-DistilBERT” architecture to select the best candidate summary for a given document D. Each DistilBERT subnetwork consists of a DistilBERT phase encodes the inputs, followed by an inference phase which calculates cosine-similarity scores. The DistilBERT’s in both networks had tied weights. The subnetworks differ in their inputs to the cosine-similarity functions. While one subnetwork calculated the cosine-similarity score between the gold summary and the document, another calculated the cosine-similarity score between the document and the candidate summaries.
Challenges we ran into
In order to implement the model using TensorFlow, we had to drastically alter the original model preprocessing steps so that the data was compatible with being converted to tensors. We also had to implement a custom model, incorporate a unique method within that model to make the calculation of metrics possible, and implement margin ranking loss from scratch.
Accomplishments that we're proud of
We are proud of overcoming all of the challenges listed above.
What we learned
This project allowed us to learn how to implement text summarization using both information we taught ourselves and what we learned during the course. For instance, we learned about the differences between extractive and abstractive text summarization systems. We also learned how to implement content selection modules for extractive summarization. To do so, we learned more about different forms of BERT, how to implement them, and their various use cases. We also learned how to structure a model that maps a document, gold summary, and candidate summaries onto a semantic space. In doing so, we incorporated class and lab concepts on natural language processing, transformers, and transfer learning. We also integrated various techniques implemented in the homework and labs, such as creating a custom TensorFlow model, specifying a custom loss function, and creating a metric dictionary. Overall, this project was a challenging but worthwhile way to enhance our understanding of class concepts and allowed us to implement a model with significant ramifications for individuals and industries.
What's next for A Golden oBERTunity: Siamese DistilBERT for Summarization
Future researchers might improve upon our model by increasing time and computing resources, using a different training data set, and attempting to further tune hyperparameters and pre-processing settings.
Built With
- tensorflow

Log in or sign up for Devpost to join the conversation.