Inspiration
The original motivation was personal voice ownership.
People can lose their voice because of ALS, cancer, stroke, age, or other medical conditions. Voice cloning can help, but many solutions still depend on a cloud API, an account, a subscription, and somebody else's infrastructure.
I wanted to explore a different model: train a voice once, then let the owner run it locally for years.
While working on that, I noticed another practical problem. TTS models often support many voices, but a user may only care about one. Kokoro is compact for a modern TTS model, but it still carries capability that a single-voice deployment does not need.
That led to a simple question:
How small and how fast can one useful voice become on an Arm CPU somebody already owns?
What it does
VoiceYog is a single-voice TTS model designed for local Arm CPU inference.
After installation, speech generation runs without CUDA, without PyTorch, and without a network connection.
brew install espeak-ng
git clone https://github.com/dlyog/voiceyog-arm.git
cd voiceyog-arm
bash manage.sh install
espeak-ng converts text into phonemes. The installer then detects whether it is running on Apple Silicon or DGX Spark, downloads the matching package, verifies it, installs the bundled Python wheels, and starts the local inference server.
The interesting part is what happens after that.
CPU benchmark
Measured on the DGX Spark GB10 with an idle GPU, using 20 held-out sentences and a separate process for each engine:
| Engine | RTF | Latency | Peak RSS | Model size |
|---|---|---|---|---|
| VoiceYog - Arm CPU | 0.03888 | 82.9 ms | 356 MB | 68.5 MB |
| VoiceYog - CPU to GPU | 0.01957 | 42.2 ms | 1898 MB | 68.5 MB |
| Kokoro-82M - GPU | 0.01418 | 40.1 ms | 3464 MB | 326 MB |
| Kokoro-82M - Arm CPU | 0.33447 | 947.5 ms | 2661 MB | 326 MB |
The comparison I care about most is VoiceYog CPU versus Kokoro CPU on the same Arm system:
- 8.6x lower real-time factor (RTF 0.03888 vs 0.33447)
- 11.4x lower per-sentence latency (82.9 ms vs 947.5 ms)
- 7.5x less runtime memory
- 4.8x smaller model on disk
RTF and latency give different ratios because RTF normalises by the audio produced and latency does not. Both are measured; I quote RTF when one number is needed because it is the conservative one.
A GPU is still faster once Kokoro is fully loaded. I am not trying to hide that. The point is that this workload no longer needs a GPU.
What it costs in quality
Speed and size are only half a result, so I measured the other half. Both engines spoke the same 20 held-out sentences — checked disjoint from all 4,104 training texts — scored with UTMOS22, the VoiceMOS Challenge predictor:
| Engine | Predicted MOS (95% CI) | On disk | RTF |
|---|---|---|---|
| Kokoro-82M (teacher) | 4.485 ± 0.017 | 326 MB | 0.33447 |
| VoiceYog (student) | 4.250 ± 0.126 | 68.5 MB | 0.03888 |
| paired difference | −0.235, p = 3.8×10⁻⁶ | 4.8× smaller | 8.6× lower |
My model carries the quality compromise usual to a distilled student, and a Wilcoxon signed-rank test says that difference is real rather than sampling noise. I would rather write the number down than claim "comparable quality". The trade is: 0.235 predicted MOS buys 4.8× smaller and 8.6× lower RTF.
That figure should be read against how little was spent producing it: 3.06 hours of teacher audio, 180 epochs, roughly ten hours on one GB10, and a 3.76 M-parameter vocoder against the teacher's 19.69 M. I stopped there deliberately, because the point of the project was the deployment argument, not a quality record. Every conventional scaling lever — more audio, more epochs, more vocoder capacity — is still in its lowest position, and each costs GPU time at training and nothing at inference. So 0.235 characterises this training budget rather than the approach. I have not run that experiment, so I am not predicting where it would land.
Predicted MOS is about naturalness, though, not about whether the words survive. So I also scored intelligibility: synthesizing the same held-out sentences, transcribing them back with Whisper and comparing against the input text gives WER 0.0186 and CER 0.0245, with 19 of 20 transcribed exactly. Under two percent word error says the compromise is one of polish rather than content — the words come through intact, and what the smaller model gives up is in the delivery.
The single imperfect transcript is not a synthesis failure: the reference reads "three hundred fifty" and Whisper wrote "350". I am reporting 0.0186 as measured rather than teaching the normalizer to expand numerals after seeing which sentence failed.
Anyone can re-run that on a DGX Spark with one command — python3 2_arm_optimization/8_wer_cer.py builds its own virtualenv, installs Whisper, synthesizes, scores, and writes the evidence file that the claim checker then verifies.
Two honest caveats. UTMOS is an automatic predictor, not a human listening panel — it scores about 3.3 on pure silence, so the absolute number flatters and only the delta is trustworthy. And my family and I have listened to plenty of it and find it perfectly good for narration, tutorials or a personal voice — but that is an impression from an unblinded group of four, not a study, and it should count for nothing. What is still genuinely missing is a speaker-similarity score and a panel of 20–50 independent listeners. That is future work.
Cold start also changes the experience. Kokoro GPU took 5.42 seconds from process start to first audio in my test, while VoiceYog CPU took 0.94 seconds.
Private voice deployment
The downloadable model does not contain my personal cloned voice. I distribute a single Kokoro-derived voice for the demo package.
The repository also includes the pipeline I used so people can build their own model.
A user can provide a voice sample, generate a focused training corpus with a larger local TTS model, train the smaller student once on a GPU, export it, and then run that voice locally on an Arm CPU.
That means the long-term inference path does not need a cloud voice-cloning API and the user's voice does not have to be sent to a remote service every time they want speech.
For me, that privacy story is just as important as the speed.
Provenance
Every generated clip also carries a signed provenance record containing information such as the model, checksum, runtime, and platform. It is verifiable offline, and tamper-evident: change one bit of the audio and the check fails.
The goal is simple: generated voice should be fast and private, but it should also be traceable.
There is an angle here I did not expect when I started. Regulation is moving toward persistent provenance for AI-generated audio — California's AI Transparency Act (SB 942), as amended by AB 853, becomes operative on August 2, 2026 for covered providers. Existing provenance can usually say that audio was generated and by which system, but not which voice, because in a shared multi-voice model the voice is a runtime argument rather than a property of the artifact.
Single-voice specialization changes that for free: one voice is one model file, so the checksum already in the record identifies the voice, because there is exactly one voice that file can produce.
I want to be careful about how far that goes. The record is detached, not embedded — it is not a watermark, it can be stripped by whoever redistributes the audio, and it does not let anyone identify a voice just by listening. It does not satisfy a latent-disclosure requirement, and VoiceYog is nowhere near the one-million-user threshold that makes a provider "covered", so I am claiming no compliance of any kind. What I am saying is narrower: this deployment shape is a natural place to attach identity, and pairing it with an acoustic watermark is the obvious next step. That part is future work.
This is research work and may contain inaccuracies. Nothing here is legal advice.
Architecture
The whole project is one pipeline. A sample of audio goes in at the top, and a voice that runs on an Arm CPU comes out at the bottom. Every box is a script in this repository, and every one of them was run on the DGX Spark before it was written about here.
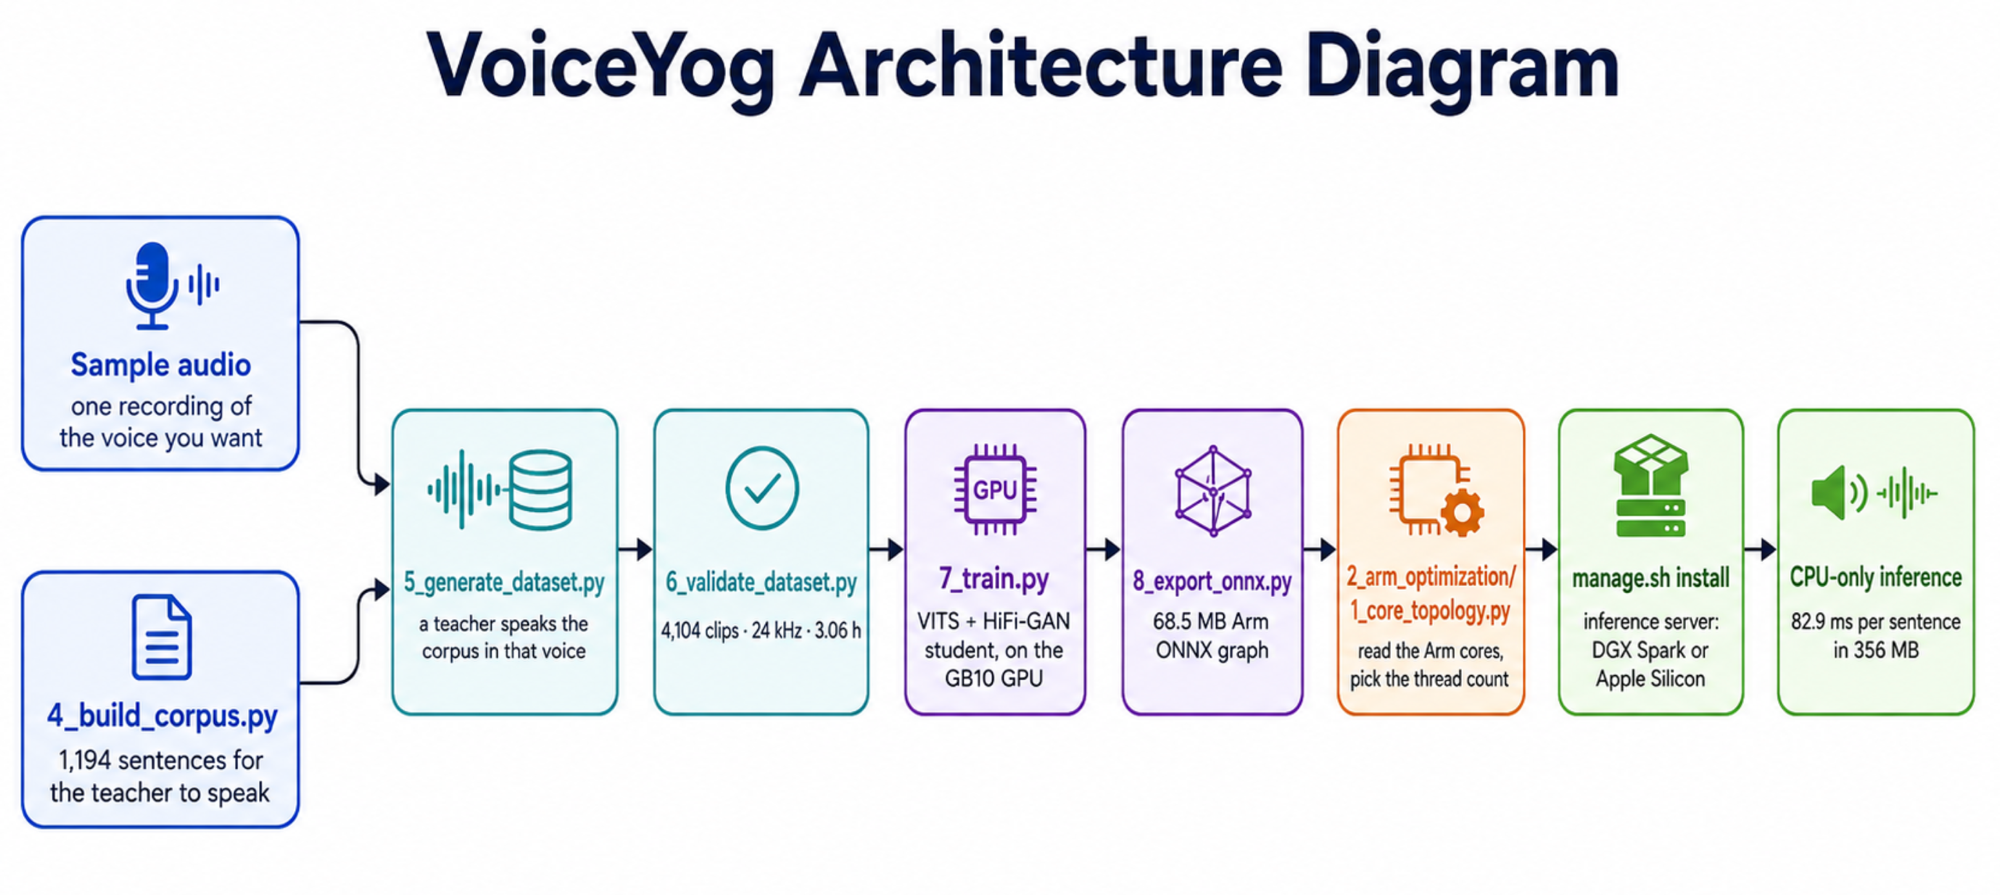
| Step | Script | What comes out |
|---|---|---|
| Build the prompt corpus | 1_word_bank.py, 2_cmu_arctic_sentences.py, 3_llm_sentences.py → 4_build_corpus.py |
1,194 sentences, offline, no network |
| Generate data from a sample | 5_generate_dataset.py |
A teacher speaks the corpus. Kokoro for an AI voice, or a local clone service conditioned on one recording of you. This is the only step that changes between the two |
| Validate before training | 6_validate_dataset.py |
4,104 clips, 24 kHz, 3.057 hours. Catches wrong sample rates, stereo files and bad delimiters before a training run wastes hours on them |
| Train the student | 7_train.py |
25.74 M generator with a 3.76 M vocoder, about 125 s per epoch on the GB10 |
| Export for Arm | 8_export_onnx.py |
A 68.5 MB ONNX graph that runs on any modern Arm CPU |
| Tune for the Arm CPU | 2_arm_optimization/1_core_topology.py |
The thread count, read from the hardware at runtime: 9 on DGX Spark, 8 on M1 Max |
| Install and serve | manage.sh install |
Detects the platform, installs the matching package from bundled wheels, starts the local server |
The GPU appears exactly once, in the training step. Everything below the export runs on the CPU, which is the whole point of the project.
What you get at the end
Against the same Kokoro model on the same DGX Spark Arm CPU:
- 8.6x lower RTF, 11.4x lower per-sentence latency, and 7.5x less memory
- 68.5 MB on disk instead of 326 MB
And against Kokoro running on the GB10 GPU:
- 9.7x less memory while running, 356 MB against 3464 MB
- 5.8x faster to the first word from a cold start, 0.94 s against 5.42 s
- but once loaded Kokoro on the GPU still has 2.74x lower RTF, equivalently about 2.07x lower per-sentence latency, and I would rather say so than have somebody find it
How I built it
The project came together in four main steps.
1. Build a smaller single-voice model
The student is a smaller VITS/HiFi-GAN model trained from scratch on roughly three hours of Kokoro-generated speech.
Kokoro supports multiple voices. VoiceYog does not need that flexibility at inference time, so the student architecture can be much smaller.
That is how the deployed model comes down from 326 MB to 68.5 MB.
The expensive part happens on the DGX Spark GB10 GPU during data generation and training. Once the model is trained and exported, the GPU is no longer required for normal inference.
2. Profile before optimizing
I did not want to guess where the CPU time was going, so I profiled the shipped workload with Arm Performix.
Across 41,593 samples:
| CPU time | Component |
|---|---|
| 94.0% | ONNX Runtime |
| 3.1% | OpenBLAS |
| 2.0% | libc |
| 0.3% | espeak-ng |
| 0.2% | Python |
That was useful because it showed that almost all of the work was in ONNX Runtime, not Python glue code.
So that is where I focused the optimization.
3. Make threading aware of the Arm CPU
Both of my targets are asymmetric Arm systems. They mix faster and slower cores.
That matters for latency. If an ONNX operator runs across several threads, the operation cannot finish until the slowest participating thread is done. Using more cores can therefore make inference slower when some of those cores are significantly slower.
Instead of hard-coding a thread count, VoiceYog reads the hardware topology at runtime.
On Linux it uses information including MIDR_EL1 and cpu_capacity. On macOS it uses the performance-level information exposed by the system.
The measured result:
| Platform | Best threads | Versus all cores | Versus ORT default |
|---|---|---|---|
| DGX Spark GB10 | 9 | 1.39x faster | 1.65x faster |
| Apple M1 Max | 8 | 2.21x faster | 1.20x faster |
This is why the demo shows different thread counts on the two machines. The runtime is not just asking for every available CPU core. It is adapting to the Arm hardware it actually finds.
4. Make the claims reproducible
While preparing the submission, I caught several numbers that had become stale after code or model changes.
So I stopped trusting numbers copied by hand.
verify_claims.py checks the figures in the project against the JSON produced by the measurement scripts and exits with an error when they disagree.
That became one of the most useful pieces of the project because optimization claims are easy to get wrong when hardware, model versions, and runtime settings keep changing.
Challenges I ran into
A benchmark I had to correct
An earlier version of my notes said VoiceYog was "3x faster than Kokoro GPU."
When I re-ran both engines fairly on an idle system, that claim did not hold. The old baseline had been measured while the GPU was busy.
I removed the claim and built the checker so that kind of drift is harder to publish again.
My own package was using the wrong thread count
At one point the DGX build was using all 20 CPU threads even though the documentation said the runtime was tuned.
The reason was embarrassing but useful: an old assumption in the Linux code treated all DGX CPU cores as equivalent.
They are not.
Fixing the topology detection improved the measured RTF from 0.0528 to 0.0339 in that test.
The fast cores were not where I expected
On the GB10, the performance cores are not simply the first half or second half of the CPU IDs. They are spread across the topology.
That broke an early attempt to pin threads using a simple CPU range and convinced me that the runtime should read the hardware instead of guessing from core numbers.
Dynamic INT8 was smaller, but unusable
Dynamic INT8 quantization made the model file about 3.3x smaller.
It also rewrote convolutions into ConvInteger, which the ONNX Runtime CPU provider did not have an AArch64 kernel for in this workload.
So the model would not load on either target.
I kept that result in the project because "smaller file" is not an optimization if the artifact cannot run.
I later found the lesson I took from it was too broad. Static quantization emits QLinearConv instead, and that operator does have an AArch64 kernel: the quantized convolution runs at 94.8 microseconds per call against 385.1 for FP32, in a model 3.5x smaller. "INT8 does not run on Arm" was the wrong conclusion. "ConvInteger does not run on Arm" was the right one.
KleidiAI could not run at all, and I tested that rather than assuming it
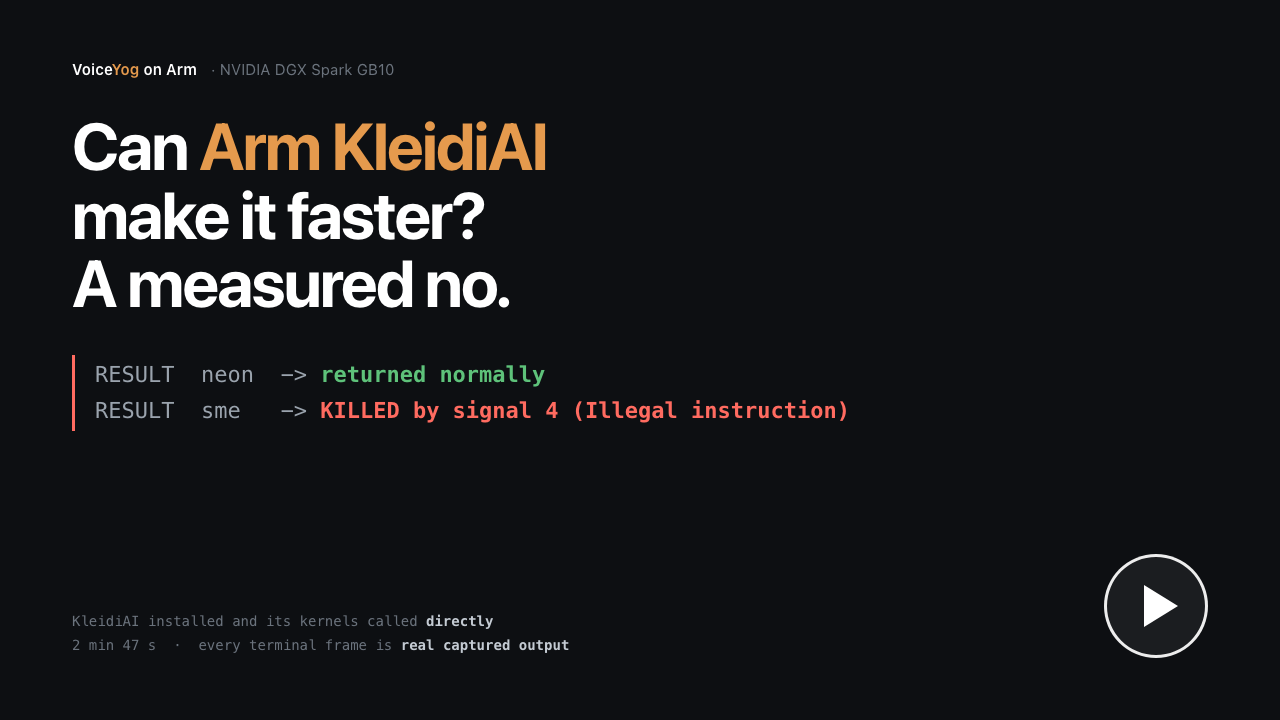
There is a 2 minute 47 second video of this: youtu.be/r2mlrF9LK4E. It shows KleidiAI being installed and its kernels called directly, one returning and one dying, and then the 2x thread-placement result. Every terminal frame in it is real captured output; nothing was screen-recorded or typed for the camera, and the narration is my own cloned voice running locally on the DGX Spark.
The packages pin ONNX Runtime 1.20.1, which contains no KleidiAI symbols. A 1.28.0 build on the same DGX Spark contains 11 kai_run_matmul_* symbols, so the obvious question was whether upgrading would make the CPU path faster.
It cannot. ONNX Runtime installs every KleidiAI kernel behind a single check, HasArm_SME() || HasArm_SME2(), and neither the GB10's Cortex-X925 and Cortex-A725 cores nor the M1 Max implements SME.
I did not want to stop at reading the dispatch logic, so I installed KleidiAI from Arm's repository on both machines and called its kernels directly, with ONNX Runtime out of the picture. On both machines the NEON kernel returns normally and the FP32 SME kernel dies with an illegal instruction, before it touches any matrix data. The gate in ONNX Runtime is not a limitation. It is the check that prevents that crash.
Two smaller things fell out of the attempt. The DGX Spark's gcc 13.3.0 rejects -march=...+sme2 outright, because GCC only gained SME in version 14, and KleidiAI builds anyway because it emits raw instruction encodings instead of relying on the assembler. On macOS the same source refuses to compile for the default Apple target, because the M1 Max has no SVE at all.
KleidiAI would also have been aimed at the wrong operator here. It accelerates matmul, and matmul is under 1% of this model's CPU time, while convolution is about 70%. The kernels that do run on these CPUs without SME are INT4 matmul kernels, and this model is FP32.
Upgrading the runtime is worth something on its own, but not unconditionally, and the condition turned out to be the more interesting result.
Pinned to the performance cores, 1.20.1 to 1.28.0 is 5.2% faster at p50 over 1,200 inferences. That is a general ONNX Runtime improvement, not a KleidiAI one, and I report it as such.
Left unpinned, 1.28.0 is bimodal. It is usually 58 to 60 milliseconds, but it repeatedly measured around 120 milliseconds on an idle machine with nothing else running, which is a 2x regression. ONNX Runtime 1.20.1 never did that in any run I took. The slow mode is thread placement: some of the intra-op pool lands on Cortex-A725 efficiency cores, and because the join at the end of every operator waits for the slowest thread, the whole graph runs at efficiency-core speed.
So the upgrade is not free. Unpinned it is a coin flip between 5% faster and 2x slower. Pinned it is a reliable 5%. I have not isolated what tips it into the slow mode, so I am reporting the mitigation, which is measured, and not a mechanism, which is not.
That is the same lesson as the rest of this project, arriving from a direction I did not expect: on an asymmetric Arm CPU, where the threads land matters more than which runtime you picked.
All of it is reproducible in kheledi/, which is deliberately self-contained: its own virtualenvs, its own frozen input fixture, no imports from the rest of the repository, and deleting the folder leaves the project unchanged. The input fixture is frozen rather than generated per machine because the DGX Spark has espeak-ng 1.51 and my Mac has 1.52, and the two disagree on liaison — regenerating locally would have given each platform different phonemes and quietly invalidated every comparison. Each result also records the machine's load average and marks itself usable or not, which is how I caught my first Apple run: it was taken while the laptop was compiling Rust, and it described a busy laptop rather than the model.
The pipeline had to become real, not reference code
Some of the original training scripts were effectively reference copies and depended on paths from my earlier project.
When I tried to run the pipeline cleanly from this repository, those assumptions broke.
I fixed the paths, separated teacher outputs, and ran the complete flow on the GB10 before documenting it.
That was a useful reminder that a pipeline is only part of the submission once another person can actually execute it.
Accomplishments I am proud of
The biggest win is not just the 68.5 MB model. It is that the whole deployment behaves like an Arm application instead of a GPU application that happens to have a CPU fallback.
The same repository can install on DGX Spark or Apple Silicon and choose a hardware-appropriate thread configuration automatically.
The core-topology utility is also reusable beyond TTS. The same idea applies to other ONNX workloads running on asymmetric Arm CPUs.
I am also happy that the demo is produced with the project's own models. During Demo VoiceYog model speaks for itself during the inference scenes.
And finally, I am proud that the failed experiments are still visible. The INT8 result failed. The cooperative CPU-to-GPU path did not beat pure Kokoro GPU inference. Those results helped narrow the project toward the part that actually worked well: small, local Arm CPU inference.
What I learned
The biggest lesson was that more CPU cores do not automatically mean more performance.
On an asymmetric Arm processor, a latency-sensitive workload can end up waiting for its slowest thread. On the M1 Max, the difference between the right thread count and using every core was 2.21x.
I also learned to read the hardware instead of inferring it from names or CPU numbering. The topology information was more reliable than every heuristic I tried.
Another lesson was that specialization can be more useful than generic compression. I did not make all of Kokoro smaller while preserving every feature. I built a model around the narrower job I actually wanted: one voice, local inference, on Arm.
And finally, benchmark documentation needs to be treated like code. If the measurements change, the write-up has to change with them.
What's next
Better CPU pipelining
There is still work left in the cooperative CPU/GPU path. Today the stages run mostly one after another, so there is room to overlap work instead of leaving one processor idle while the other is active.
I have not implemented that yet, so I am not claiming a result.
INT8 on the convolutions
Profiling says about 70% of my CPU time is convolution and under 1% is matmul, so the only optimization left that can move the number meaningfully is integer convolution.
Static QDQ quantization already runs: it produces QLinearConv rather than ConvInteger, and the quantized convolution measures 94.8 microseconds per call against 385.1 for FP32.
The version I built quantizes the whole graph, which moved the duration predictor and changed the output length on 17 of 20 sentences, so it is not shippable. The next step is to quantize the vocoder only and leave the duration path in FP32.
Observe real thread placement
I currently measure the topology and the latency result, but I do not yet record exactly which physical core every inference thread lands on.
Adding that measurement would make the threading analysis stronger.
Make bring-your-own-voice easier
The eight training pipeline scripts now ship and run end to end, covering corpus generation, teacher generation, validation, training, and ONNX export.
The next step is making that process simple enough for somebody who cares about preserving their own voice, not somebody who wants to debug a TTS training pipeline.
More Arm targets
The inference path is ONNX-based, so Android, iOS, and Windows on Arm are natural next targets.
The goal is to keep the same model and the same idea: detect the hardware, tune locally, and run the voice where the user already is.
Built with
onnxruntime · numpy · FastAPI · uvicorn · pydantic · cryptography · espeak-ng · PyTorch (training only) · Arm Performix · Qwen3-TTS · Playwright · ffmpeg · Kokoro-82M · VITS · HiFi-GAN · CMU ARCTIC · NVIDIA DGX Spark GB10 · Apple Silicon
Thanks
Kokoro-82M is both the teacher behind this experiment and the baseline I used to measure it.
VoiceYog is not an attempt to replace everything Kokoro can do. The project asks a narrower question: if I only need one voice, how much of the deployment cost can I remove, and how well can I make what remains run on Arm?
For this project, the answer was: enough to make CPU-only TTS genuinely practical for my use case.
Summary
Kokoro-82M is one of the best lightweight text-to-speech models I have used. It is already very fast on a GPU, but on an Arm CPU it can take close to a second to generate a sentence.
That felt wasteful for my use case. Most of the time I need one language and one voice, not a full multi-voice TTS system.
So I built VoiceYog: a smaller, single-voice TTS model and an Arm-aware inference runtime around it.
On the same DGX Spark Arm CPU, VoiceYog attains 8.6x lower RTF than Kokoro CPU inference while using 7.5x less memory. The model is 68.5 MB on disk and uses about 356 MB while running. Inference needs no GPU, no cloud API, and no internet connection.
The DGX Spark was my main development box. I generated the training data there, trained the student model on its GB10 Blackwell GPU, built the inference path there, and used it for the benchmark, profiling, and thread-tuning work.
From the same project I prepared inference packages for two Arm targets: DGX Spark and Apple Silicon.
That split became the main idea behind the project:
Use the GPU for the expensive work you do once. Run the voice on the Arm CPU for the work you do again and again.
I have also published a paper that takes the idea further, as DTVS — Distribution-Time Voice Specialization. The argument is that a multi-voice system makes every device carry the ability to be any voice so that it can be one, and that the voice should therefore be chosen at distribution time rather than inside the network at inference time: one N-voice deployment becomes N single-voice specialists, each independently deployable. It is a deployment-time analogue of Mixture-of-Experts, moving in the opposite direction, because it specializes before deployment and removes runtime routing entirely. The paper also explains why one distilled voice is enough to characterise that: the cost a device pays is the cost of one specialist, and that number does not depend on how many voices the catalogue holds. The single-voice result in this project is the measurement behind it.
The paper is careful about what it does not show. My student drops multi-voice conditioning and uses a smaller architecture, so the size and speed gains cannot be credited to specialization alone; it names the ablation that would settle it rather than claiming a result it has not run. It also reports no speech-quality evaluation, and says so.
Paper: Distribution-Time Voice Specialization: Only One Voice Is Needed at a Time in On-Device Text-to-Speech · PDF
Built With
- apple-silicon
- arm
- dgx
- gb10
- kokoro
- tts

Log in or sign up for Devpost to join the conversation.